

Error-Correcting Code Memory Explainer
Error-correcting code memory, commonly called ECC memory, protects stored data with additional check bits. When a processor writes a data word, the memory controller calculates a code from the data and stores the resulting redundancy alongside it. On a read, the controller calculates the code again and compares it with the stored check bits. The pattern of disagreement, called a syndrome, can identify certain error locations. A common single-error-correct, double-error-detect scheme can repair one wrong bit in a protected word and report when two bits are wrong.
The code works because valid combinations occupy only part of the available bit patterns. Hamming-style parity checks cover overlapping groups of positions. If one stored bit flips, several checks fail in a unique combination that points to that position. The controller inverts the identified bit before passing the corrected word to the processor. An extra overall parity bit can distinguish many double-bit errors from a correctable single error. Stronger server systems may use wider symbols, chip-level protection, or advanced codes to tolerate larger failure patterns.
Memory errors have several causes. A transient electrical disturbance, radiation particle, timing margin problem, overheating component, or weak cell can change a bit. A soft error disappears after correct data is rewritten, while a hard error recurs because hardware is damaged or marginal. ECC reduces the chance that an isolated fault silently changes an instruction, database field, or address. It does not make faulty hardware healthy, so corrected-error counts are logged and monitored for trends that indicate a module or channel should be replaced.
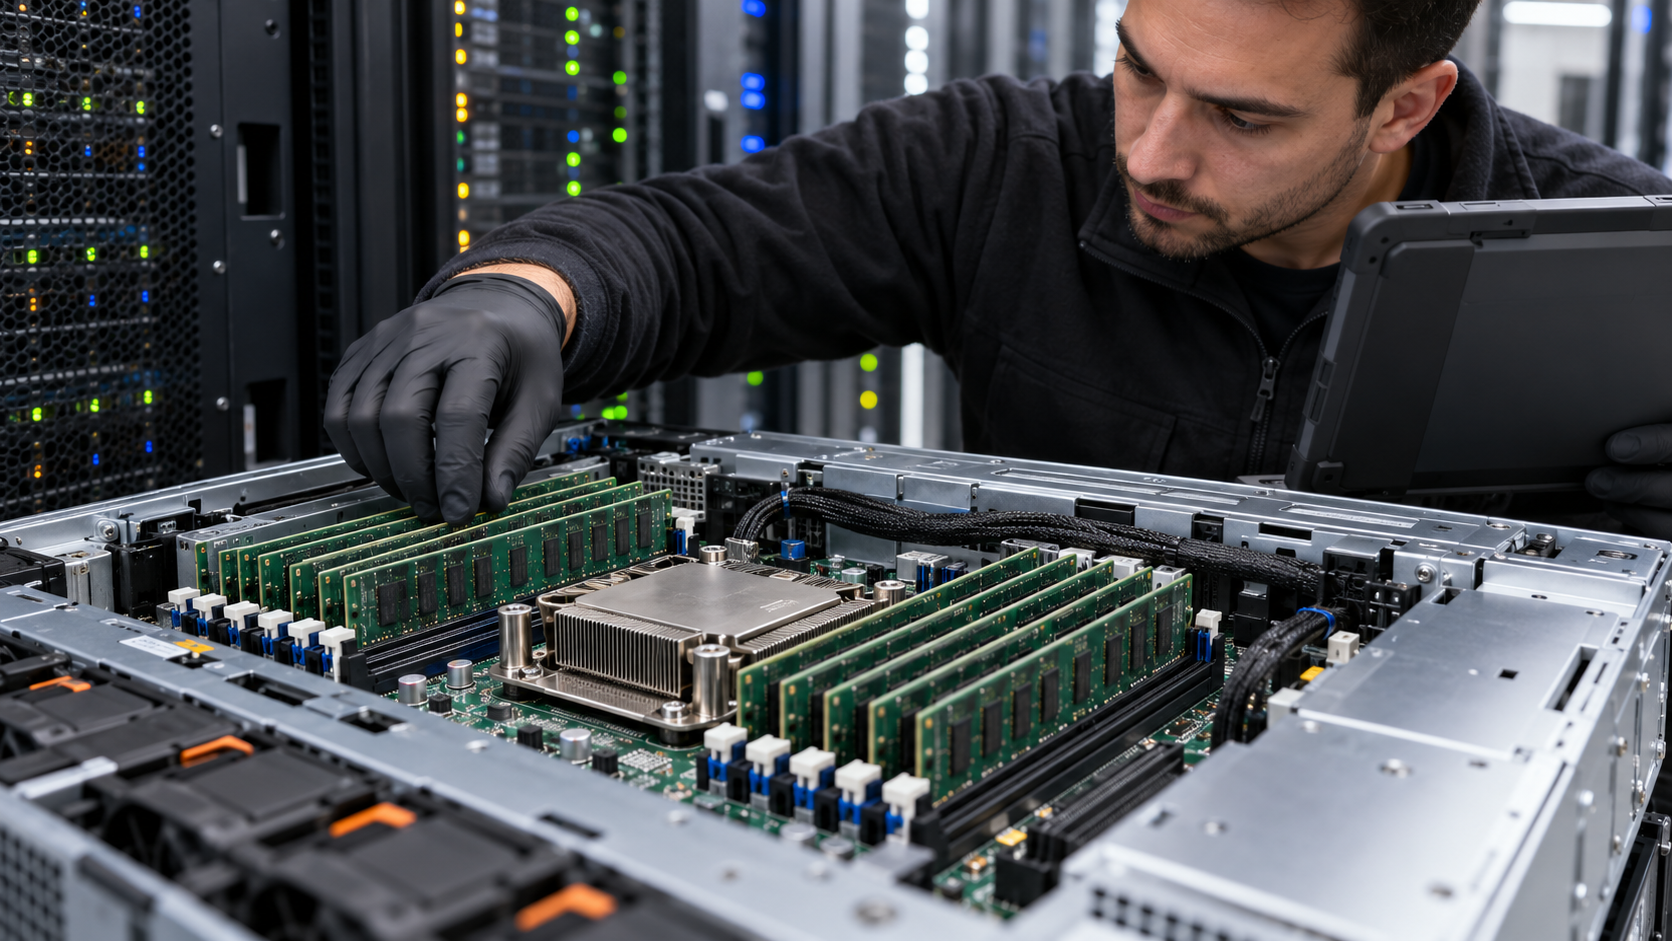
The memory modules, processor, motherboard wiring, firmware, and controller must support the same protection. Adding an ECC module to a system that ignores its check bits provides no benefit. Registered server DIMMs also include buffering for electrical loading, which is a separate feature often found with ECC but not the correction mechanism itself. Capacity labels may include extra memory devices used for redundancy. The operating system can receive machine-check information when the hardware detects an uncorrectable event.
Some systems scrub memory by reading locations in the background, correcting any single-bit error, and writing the clean codeword back. Scrubbing prevents separate errors from accumulating in the same word between ordinary accesses. Patrol rate balances coverage against memory traffic and power. Server platforms may combine ECC with spare rows, memory mirroring, device retirement, address isolation, or lockstep channels. These techniques increase resilience but consume capacity, bandwidth, or hardware.
ECC has limits. The advertised code corrects only specified patterns, and a multi-bit corruption can exceed that ability or, in rare cases, resemble another valid codeword. Faults in address or control paths may affect more than stored data bits. Firmware errors, processor bugs, storage corruption, and application mistakes sit outside basic memory ECC. Data-center reliability therefore uses ECC as one layer alongside testing, thermal management, monitoring, redundancy, and backups.
The practical sequence is automatic: create check bits on write, recompute on read, form a syndrome, correct what the code can identify, and report the event. Software normally receives the intended value without pausing to run a repair algorithm. That silent correction is valuable because memory is accessed billions of times and even rare faults accumulate at scale. ECC memory does not promise that errors never occur; it provides structured redundancy so many of them become visible and recoverable instead of silently contaminating computation.
A CPU cache is a small, fast memory close to a processor core. It keeps copies of recently or frequently used data so the CPU does not have to wait as often for slower main memory.
The cache stores data in fixed-size blocks and relies on patterns such as locality: programs often reuse nearby values soon after accessing them. Hardware replaces older blocks when it needs room for new ones.
Large or irregular data sets can exceed the cache or access memory in patterns the hardware cannot predict well. A cache miss sends the request to a slower level of memory, adding delay.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.