

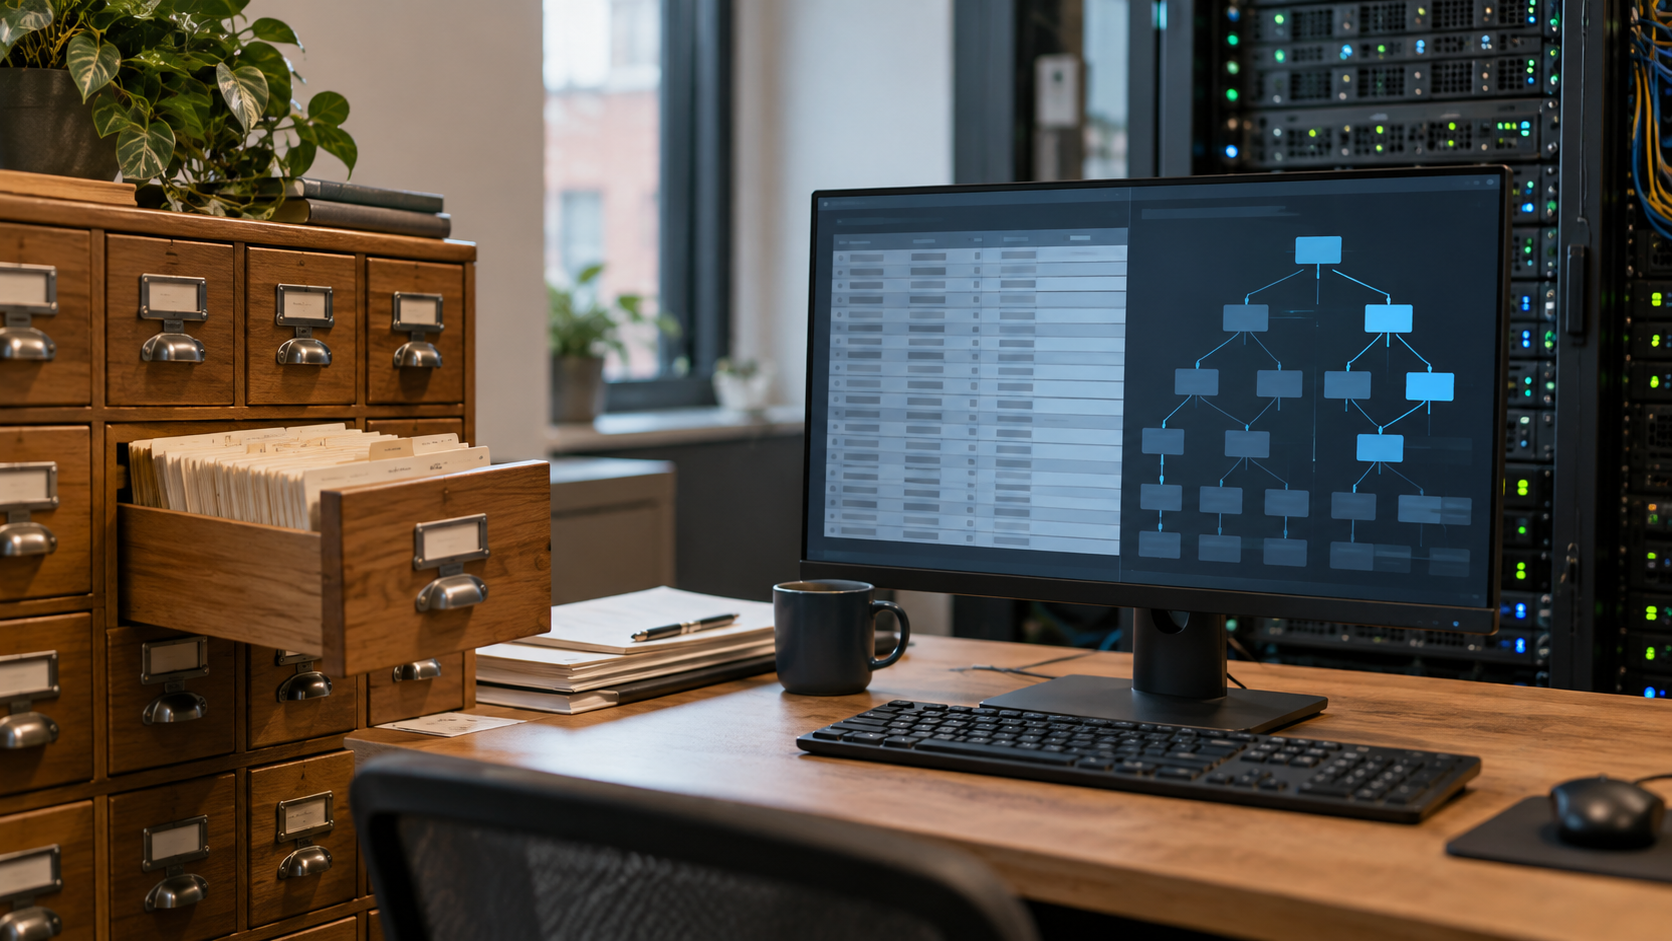
A database index is a separate data structure that helps a database locate rows without checking every row in a table. It serves a role similar to the index in a reference book: an entry for a value points toward the place where matching information can be found. If a table contains millions of orders and a query asks for one order number, an appropriate index may reduce the search to a small path through the index plus a visit to the matching row. The original table remains the authoritative data; the index is an organized guide maintained alongside it.
The most common general-purpose index uses a balanced tree, often a B-tree. Values are kept in sorted order across linked pages. A search compares the requested value with keys near the top of the tree, follows the appropriate branch, and repeats until it reaches entries that identify matching table rows. Because the tree stays shallow as it grows, equality searches and ordered ranges can be efficient. Other structures serve different needs: hash indexes emphasize equality, while specialized indexes can support full-text terms, spatial relationships, arrays, or summaries of naturally ordered blocks.
An index is not used simply because it exists. The query planner estimates the cost of available strategies using information about table size and the distribution of values. If a condition returns most of the table, reading the table sequentially may be cheaper than jumping repeatedly between an index and table pages. An index can also help with joins, sorting, updates, and deletes when their search conditions match its organization. Covering indexes may contain enough requested columns to answer some queries without visiting the main table, although that increases index size.
Column order matters in a multicolumn index. An index arranged by customer and then order date is naturally useful for looking up one customer and a range of that customer’s dates. It may be less helpful for a query that specifies only the second column. Partial indexes store entries for a selected subset, such as unresolved tickets, while expression indexes store a computed form such as a normalized value. Unique indexes do more than improve speed: they can enforce a rule that no two indexed rows share the same key, subject to the database’s treatment of null values.
The tradeoff is ongoing maintenance. Inserts may add index entries, deletes remove or mark them, and updates can change one or more structures. Each index consumes storage and can increase write time. Building an index on a large live table may also require careful operational planning because creation uses processor, memory, and input-output capacity; some database systems offer concurrent methods with their own limitations. Statistics must stay representative so the planner can make reasonable choices, and fragmented or bloated structures may eventually need maintenance.
More indexes are therefore not automatically better. Designers start with real query patterns, measure execution plans, and choose structures that support frequent or expensive searches without burdening every write. A slow query may come from missing filters, stale statistics, poor joins, or retrieving too much data rather than a missing index. An index also cannot repair an unclear data model. Used thoughtfully, it trades extra storage and update work for faster access. Its value comes from matching the organization of the index to the questions the database is repeatedly asked. Index design should also account for how values change over time. A key that constantly increases may concentrate new writes in one area, while random keys spread activity differently and can affect cache behavior. Database engines use pages, fill factors, locking, and background maintenance to manage these patterns. Testing with production-like data is important because a plan that works for a small development table may change once the table, value distribution, and concurrent workload become much larger.
No. The query planner may choose a table scan when it estimates that using the index would cost more.
Each index consumes storage and must be maintained during writes, so unnecessary indexes can slow changes without helping important queries.
It organizes lookups and enforces that indexed keys do not duplicate, according to the databases rules for values such as nulls.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.