

Vision Transformer Explainer
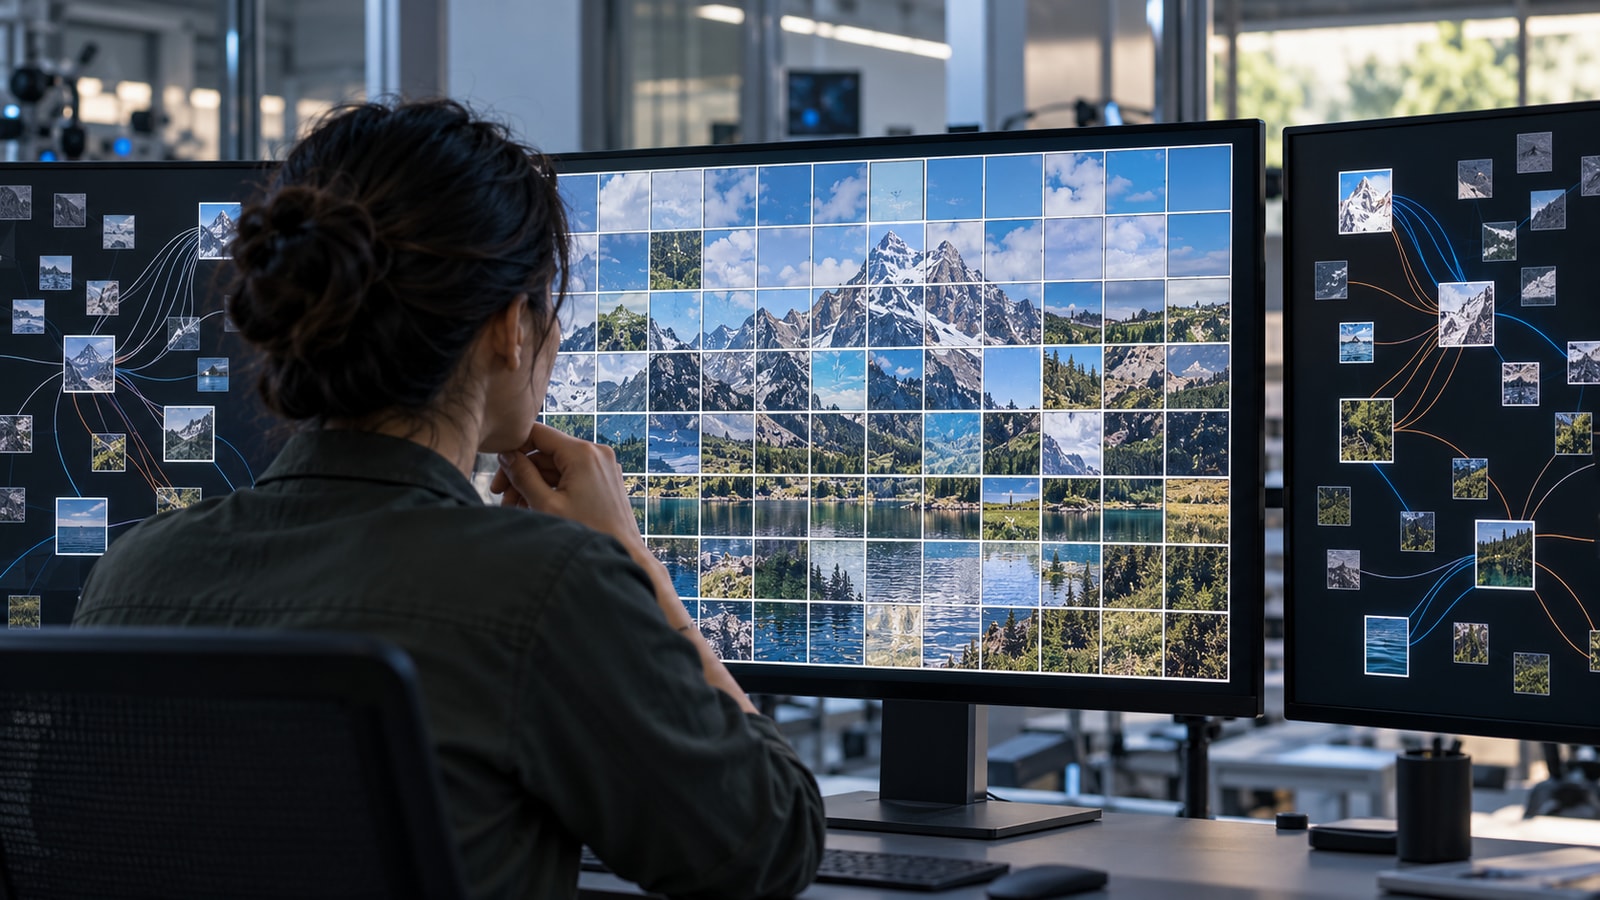
A vision transformer, or ViT, adapts the transformer architecture to images. It divides an image into patches, converts each patch into a vector representation, adds position information, and processes the resulting sequence with transformer layers.
Self-attention allows each patch representation to interact with patches elsewhere in the image. That global interaction differs from the local receptive fields built into standard convolutions, although modern vision systems often combine ideas from both approaches.
Vision transformers can perform image classification and serve as backbones for detection, segmentation, and multimodal systems. Their performance depends strongly on training data, augmentation, architecture scale, pretraining, and the resolution and patch size used.
The method is not automatically more efficient than a convolutional network. Attention cost grows with the number of patches, and smaller patches create longer sequences. Model choice should consider accuracy, latency, memory, data volume, and the target hardware.
A vision transformer represents an image as a sequence of patches and processes those patch representations with transformer layers.
Key terms include image patch, patch embedding, visual token, self-attention, position encoding, transformer block, classification token, resolution and backbone.
Each patch is flattened or projected into an embedding, then combined with position information so the model can distinguish locations.
Transformer blocks update the patch representations through attention and feedforward layers.
Finer patches preserve more spatial detail but lengthen the sequence and increase attention cost.
Pretraining and augmentation can be crucial, so comparisons should include data scale, resolution, latency, and hardware rather than accuracy alone.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.