

One-Hot Encoding Explainer
One-hot encoding converts a categorical variable into separate indicator columns. Each known category receives a position, and an observation activates the position corresponding to its category while leaving the others inactive.
This representation avoids implying that arbitrary category codes have a meaningful order or distance. It is useful for many linear models and other algorithms that expect numeric input but do not interpret raw category labels directly.
The method can create very wide data when a field has many distinct values. Rare categories, unseen categories, memory use, and whether to group values therefore need explicit handling in the preprocessing pipeline.
The category vocabulary must be learned from training data and applied consistently later. One-hot encoding is not always necessary: tree implementations may support categories directly, while learned embeddings can represent high-cardinality values more compactly.
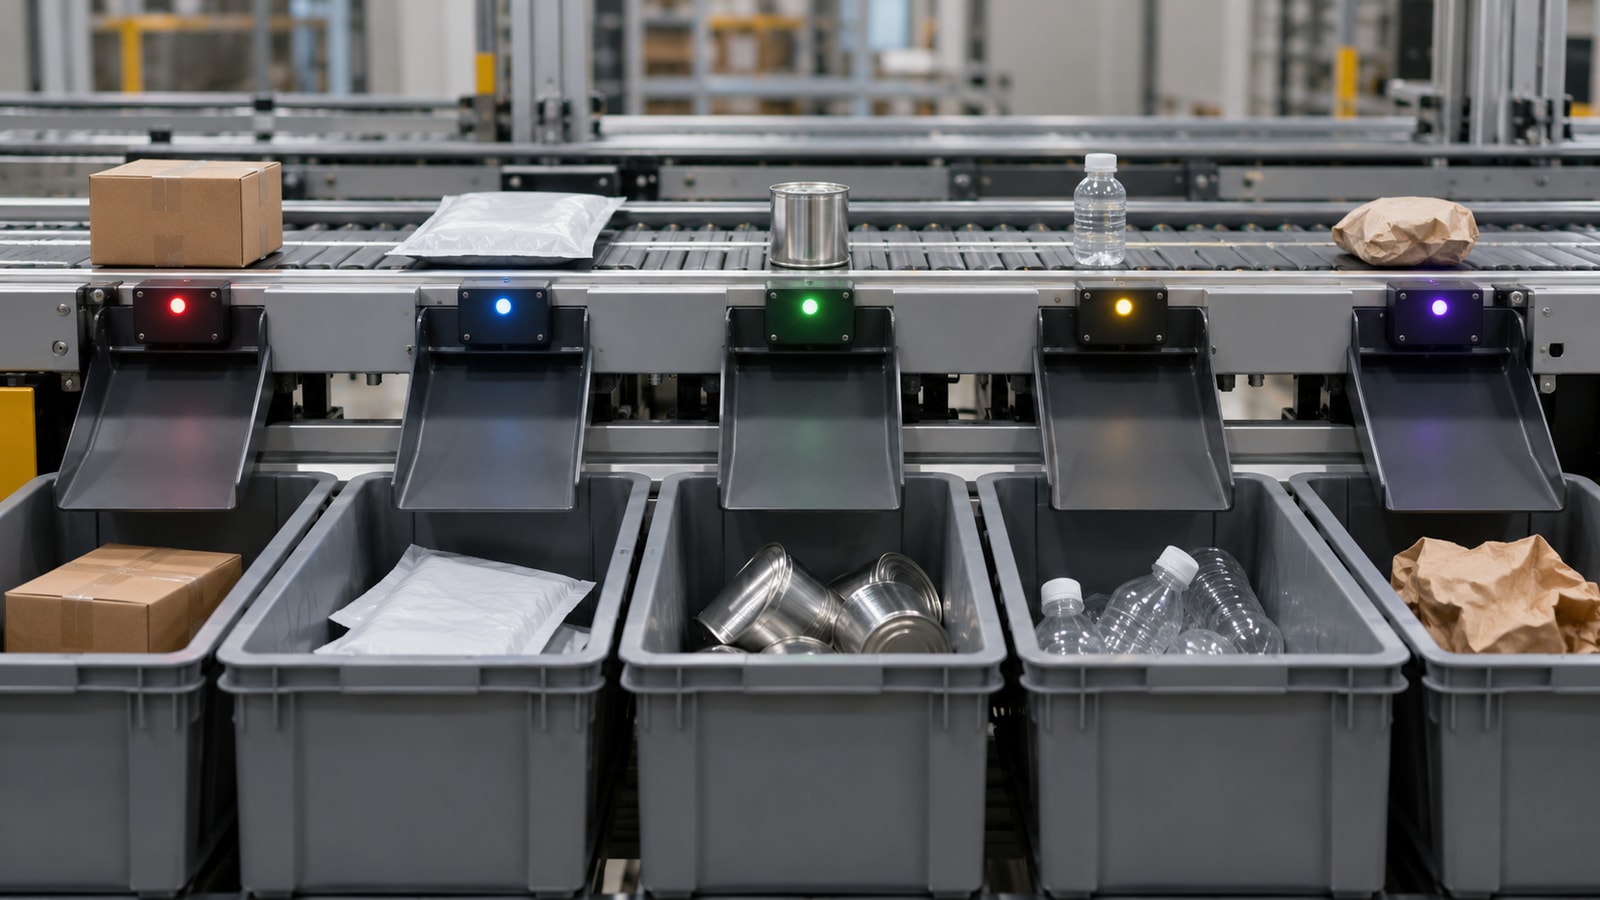
One-hot encoding represents each category with its own binary indicator instead of assigning categories an artificial numeric order.
Key terms include categorical variable, binary indicator, category vocabulary, unknown category, high cardinality, sparse matrix and embedding.
Separate indicators prevent arbitrary category codes from being treated as ordered measurements.
The encoded columns can be sparse because each observation activates only a small portion of them.
Production data may contain a category that never appeared during fitting.
The pipeline should define whether to ignore, group, reject, or otherwise represent unknown and rare values.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.