

Multi-Task Learning Explainer
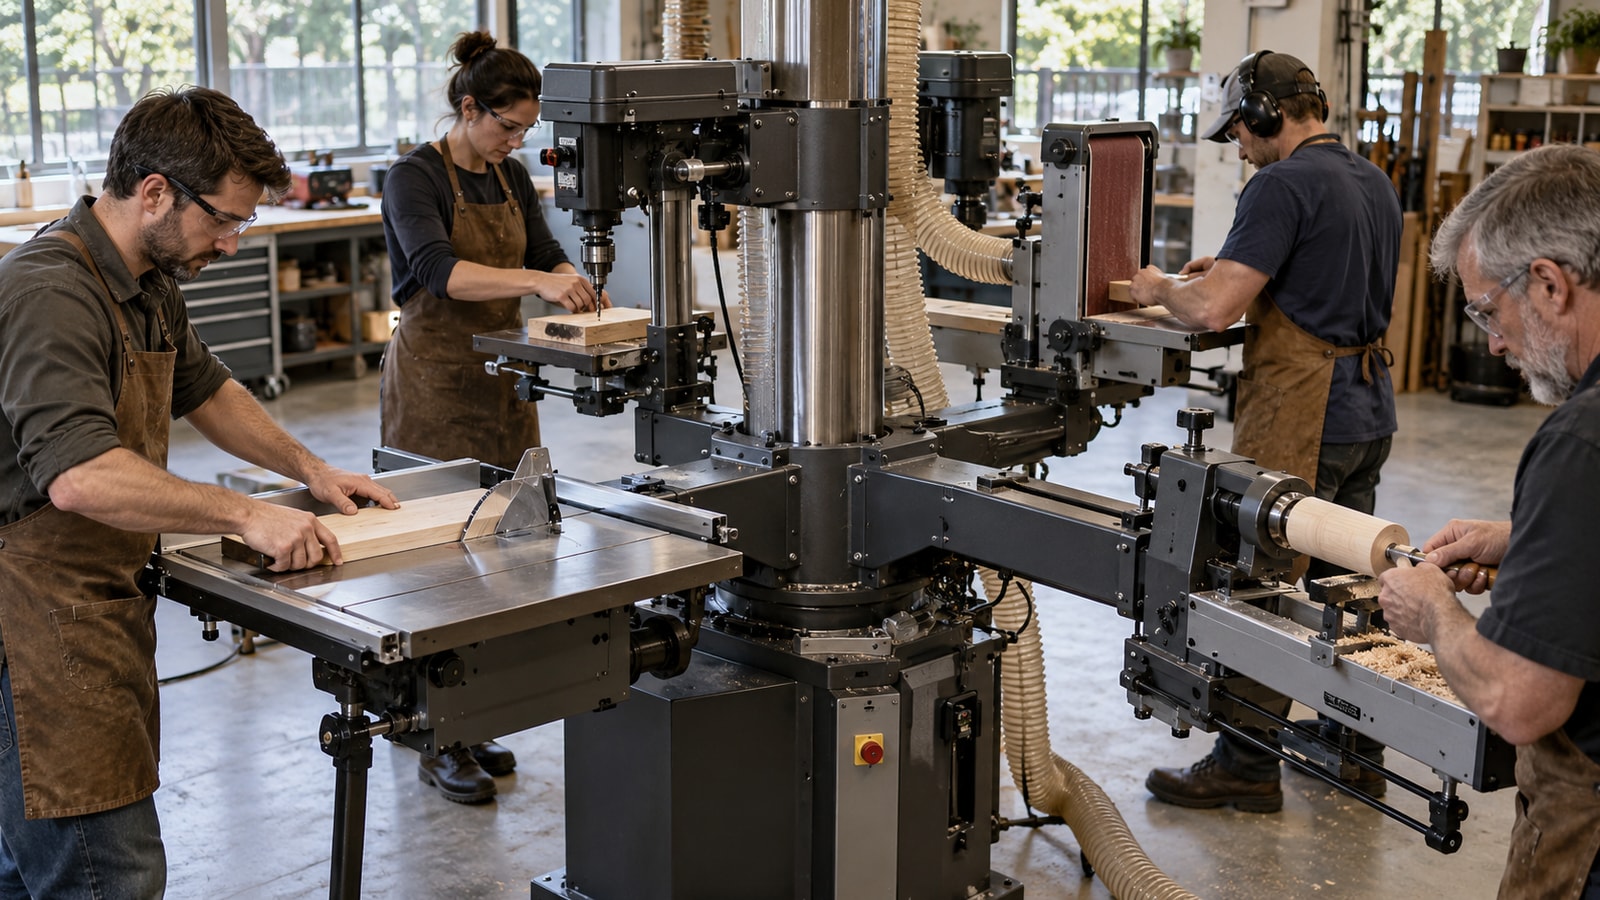
Multi-task learning trains a model on several related objectives at the same time. The tasks may share a backbone or selected parameters while keeping separate output heads, allowing evidence from one objective to influence representations used by others.
Shared learning can act as a form of regularization and provide additional supervision. A vision system, for example, might learn object categories, depth, and boundaries together when those signals describe complementary aspects of the same scene.
The method can improve data efficiency, reduce deployment complexity, and produce features useful across tasks. Designers choose which components to share and how to weight losses so large or easy tasks do not dominate training.
Relatedness is not guaranteed. Conflicting gradients or imbalanced data can cause negative transfer, improving one task while damaging another. Evaluation must report every task, compare single-task baselines, and examine whether shared errors affect safety.
Multi-task learning trains related tasks together so shared representations can transfer useful information among them.
Key terms include multi-task learning, shared representation, task head, loss weighting, inductive transfer, gradient conflict, negative transfer and backbone.
A common backbone can learn features useful to several related objectives.
Separate heads preserve task-specific outputs while joint losses shape the shared representation.
One task may dominate optimization or push shared parameters in a harmful direction.
Per-task metrics and single-task comparisons reveal whether sharing actually helps.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.