

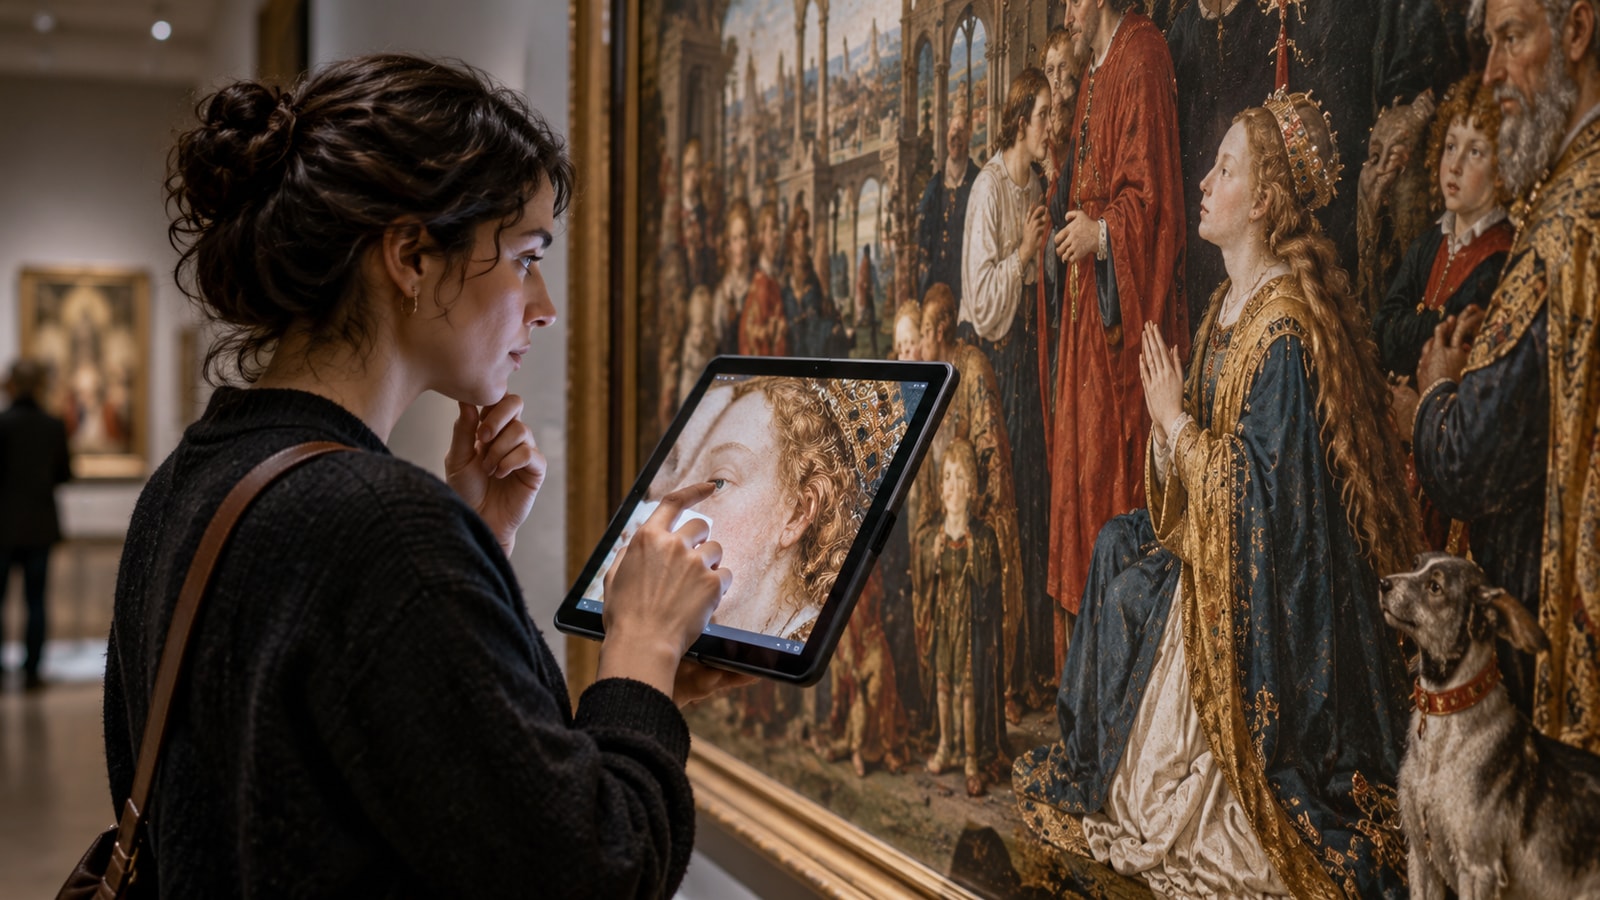
Visual Question Answering Explainer
Visual question answering, or VQA, gives a model an image and a written question, then asks for an answer grounded in the picture. Questions may concern objects, counts, colors, actions, spatial relationships, or outside knowledge linked to visible evidence.
The system encodes the image and question, combines their representations, and either selects an answer from a vocabulary or generates one. Attention can connect words in the question with relevant image regions.
VQA is used to study multimodal reasoning and can support accessible interfaces, visual search, education, and assistants that discuss photographs or documents. Benchmarks vary in whether they emphasize recognition, reading, common sense, or compositional reasoning.
Models can exploit language patterns without looking carefully at the image. Ambiguous questions and subjective annotations also complicate scoring. Strong evaluation uses balanced questions, counterexamples, explanations or evidence, and tests on unfamiliar combinations and scenes.
Visual question answering asks a model to answer a natural-language question using evidence from an image.
Key terms include VQA, multimodal reasoning, image encoder, question encoder, attention, answer vocabulary, grounding and dataset bias.
Words specify which part of the image and which relationship matter for the answer.
The model combines visual evidence with the question representation before predicting a response.
Dataset patterns may let a system guess frequent answers without inspecting the scene.
Balanced counterexamples and evidence checks reveal whether answers are truly image-grounded.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.