

Topic Modeling Explainer
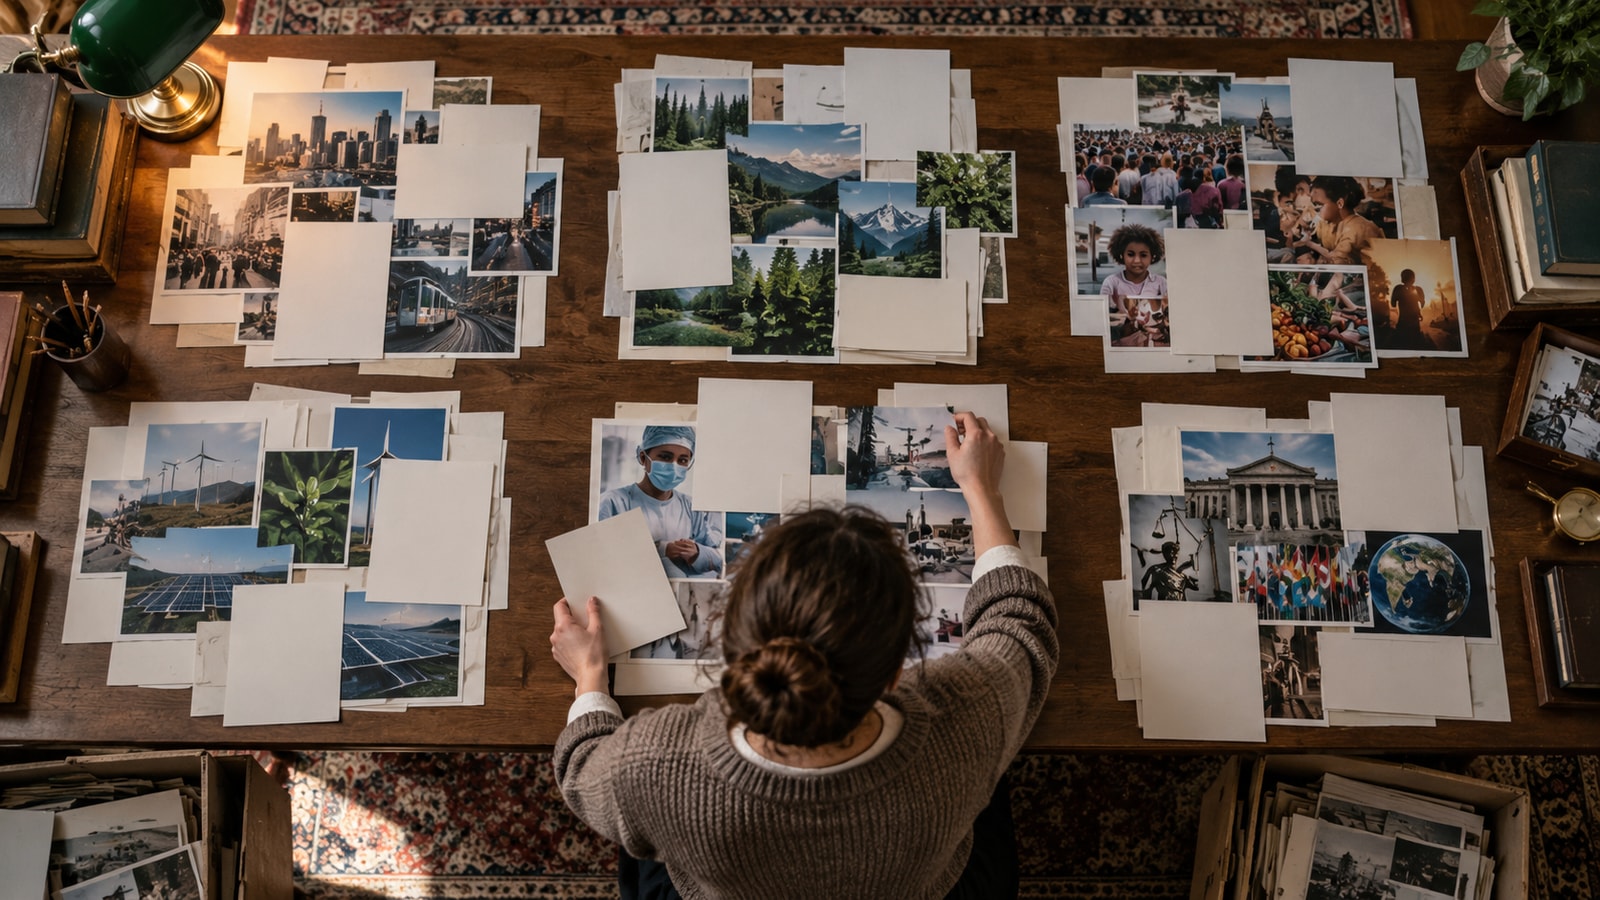
Topic modeling is a family of methods for discovering recurring patterns in a collection of documents without requiring a category label for each one. A topic is usually represented as a probability distribution over words, and a document can contain several topics in different proportions.
Latent Dirichlet allocation, or LDA, is a well-known probabilistic model that treats each word as arising from a hidden topic assignment. Neural topic models use learned representations and different inference techniques but pursue a similar organizing goal.
Topic models help explore archives, research literature, customer feedback, public comments, and news collections. They can reveal broad structure, support browsing, and suggest questions for closer qualitative analysis.
A word cluster is not automatically a coherent or objective theme. Results change with preprocessing, topic count, random initialization, time period, and corpus composition. Human experts should inspect representative documents, label cautiously, and avoid treating topics as facts about individuals.
Topic modeling discovers recurring word patterns in a document collection and represents documents as mixtures of latent themes.
Key terms include topic model, latent topic, word distribution, document mixture, LDA, corpus, coherence and preprocessing.
The model describes each topic through words that often appear in related contexts.
Each document receives proportions rather than one mandatory category.
Statistical word patterns may be vague, redundant, or shaped by formatting artifacts.
Representative documents and domain knowledge are essential when naming a topic.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.