

Inverted Index Explainer
An inverted index is a search structure that maps terms to the documents in which they appear. Instead of opening every document for a query, the engine looks up the query terms and combines their posting lists.
A posting can store a document identifier, term frequency, positions, field information, and other data used for scoring or phrase matching. Lists are usually sorted and compressed so intersections and skips are efficient.
Inverted indexes power web, enterprise, legal, library, and product search. They also support learned sparse retrieval because a sparse model can assign weights to vocabulary terms that fit the same basic structure.
Index quality depends on tokenization, language handling, field design, freshness, and document permissions. Common terms create long lists, while misspellings and unseen vocabulary reduce matching. Updates and deletions must stay synchronized with source content.
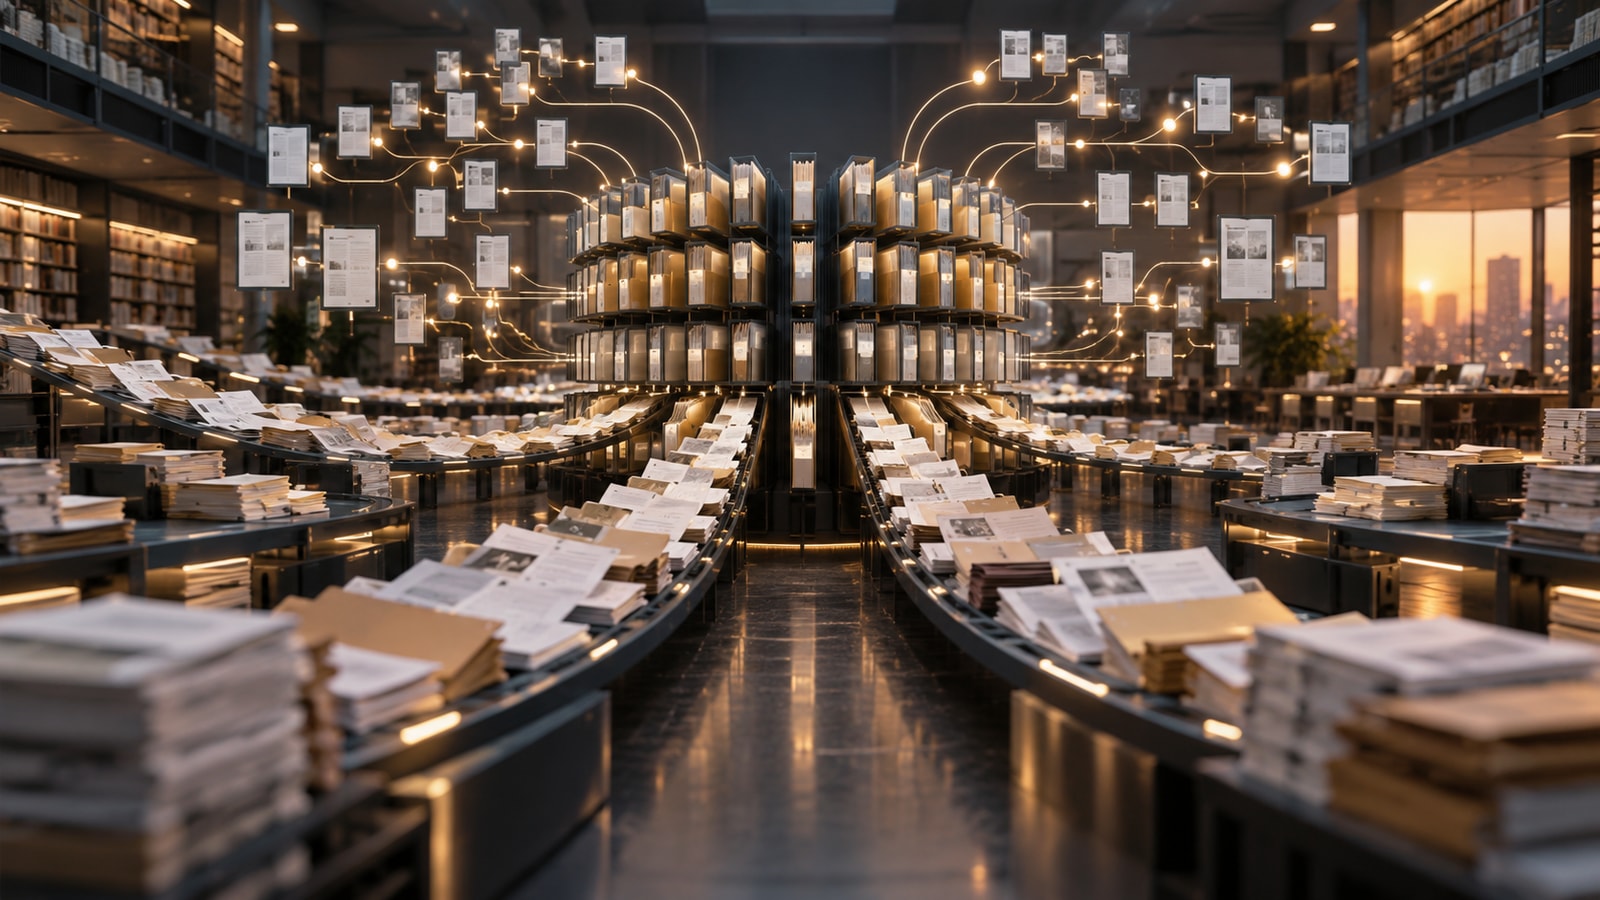
An inverted index maps each term or feature to the documents that contain it, allowing search to avoid reading every document.
Key terms include inverted index, term, posting list, document identifier, term frequency, position, tokenization, compression and query.
Each indexed term owns a list of documents and optional positions or weights.
Query processing intersects, unions, or scores those lists instead of scanning the collection.
Tokenization, stemming, fields, and language rules decide which terms enter the index.
Freshness and access controls must remain correct as documents change.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.