

Retrieval Evaluation Explainer
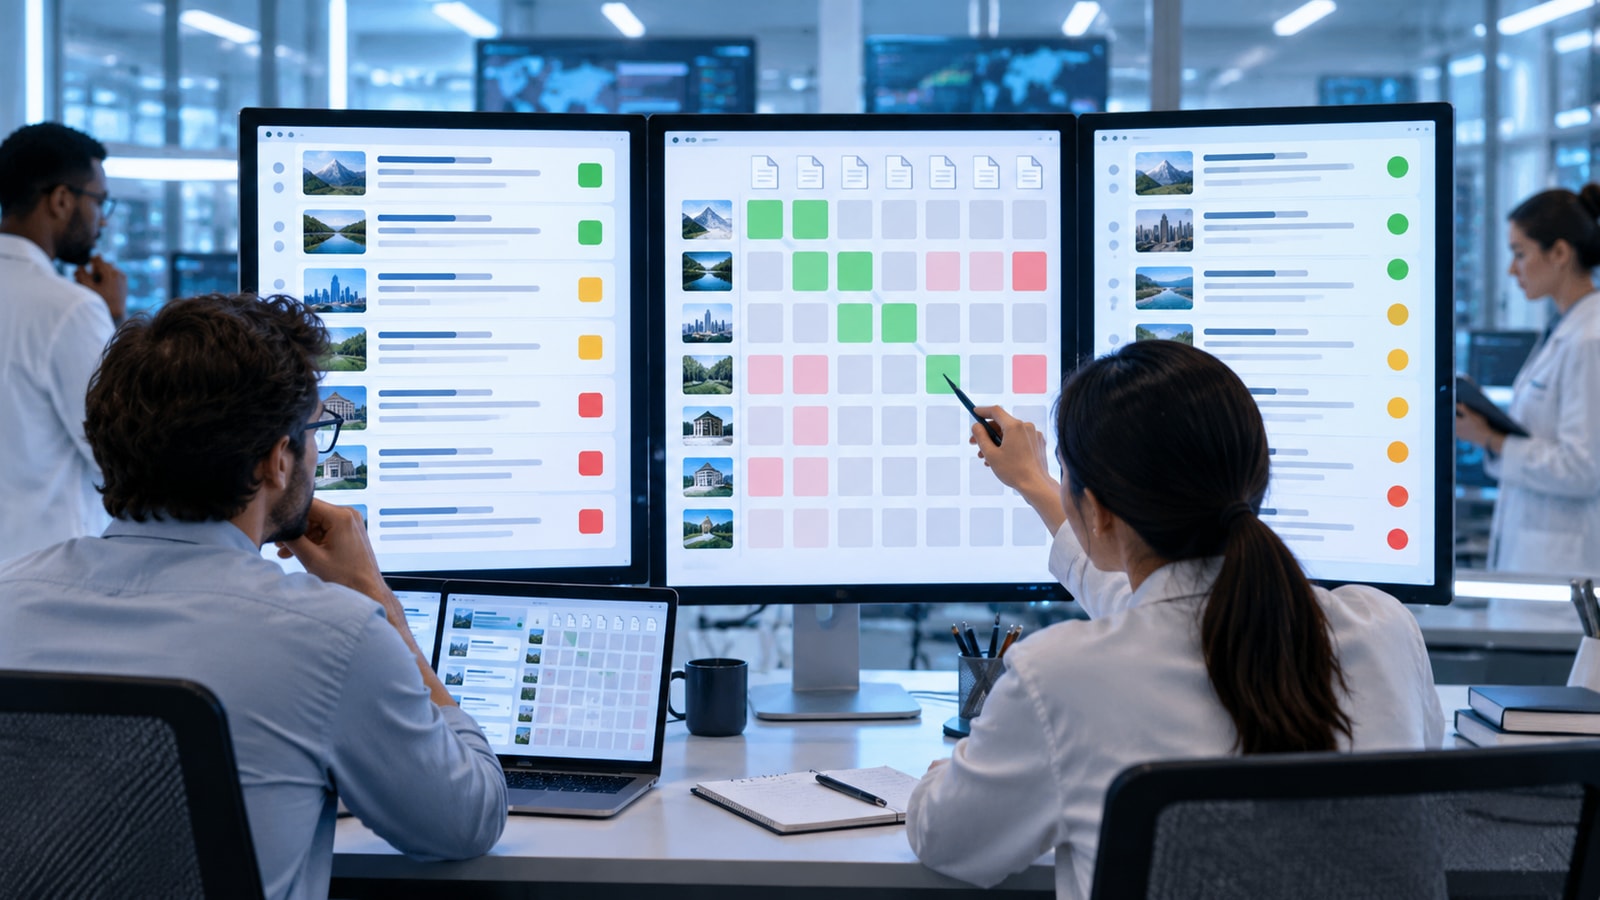
Retrieval evaluation measures whether a search system returns relevant items and places the most useful ones near the top. It starts with a set of queries and relevance judgments connecting each query to useful documents or passages.
Recall measures how much relevant material was found. Precision measures how much returned material was relevant. Ranking metrics such as mean reciprocal rank, average precision, and normalized discounted cumulative gain emphasize positions in different ways.
Offline evaluation supports repeatable comparison before a system reaches users. Online experiments and satisfaction research add evidence about real behavior and outcomes.
Judgments can be incomplete or subjective, and popular benchmark queries may not reflect current traffic. A single average hides rare, difficult, multilingual, or high-stakes needs. Teams should report multiple metrics, query slices, latency, freshness, and failure examples.
Retrieval evaluation measures how well a search system finds and orders relevant items for representative queries.
Key terms include retrieval evaluation, relevance judgment, precision, recall, mean reciprocal rank, average precision, NDCG, test collection and query slice.
Metrics differ in how they reward finding all relevant items versus placing one answer first.
A test collection makes comparisons repeatable across system versions.
Rare names, ambiguous requests, and underserved languages may disappear inside an overall score.
Query slices and qualitative error review reveal where the system fails.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.