

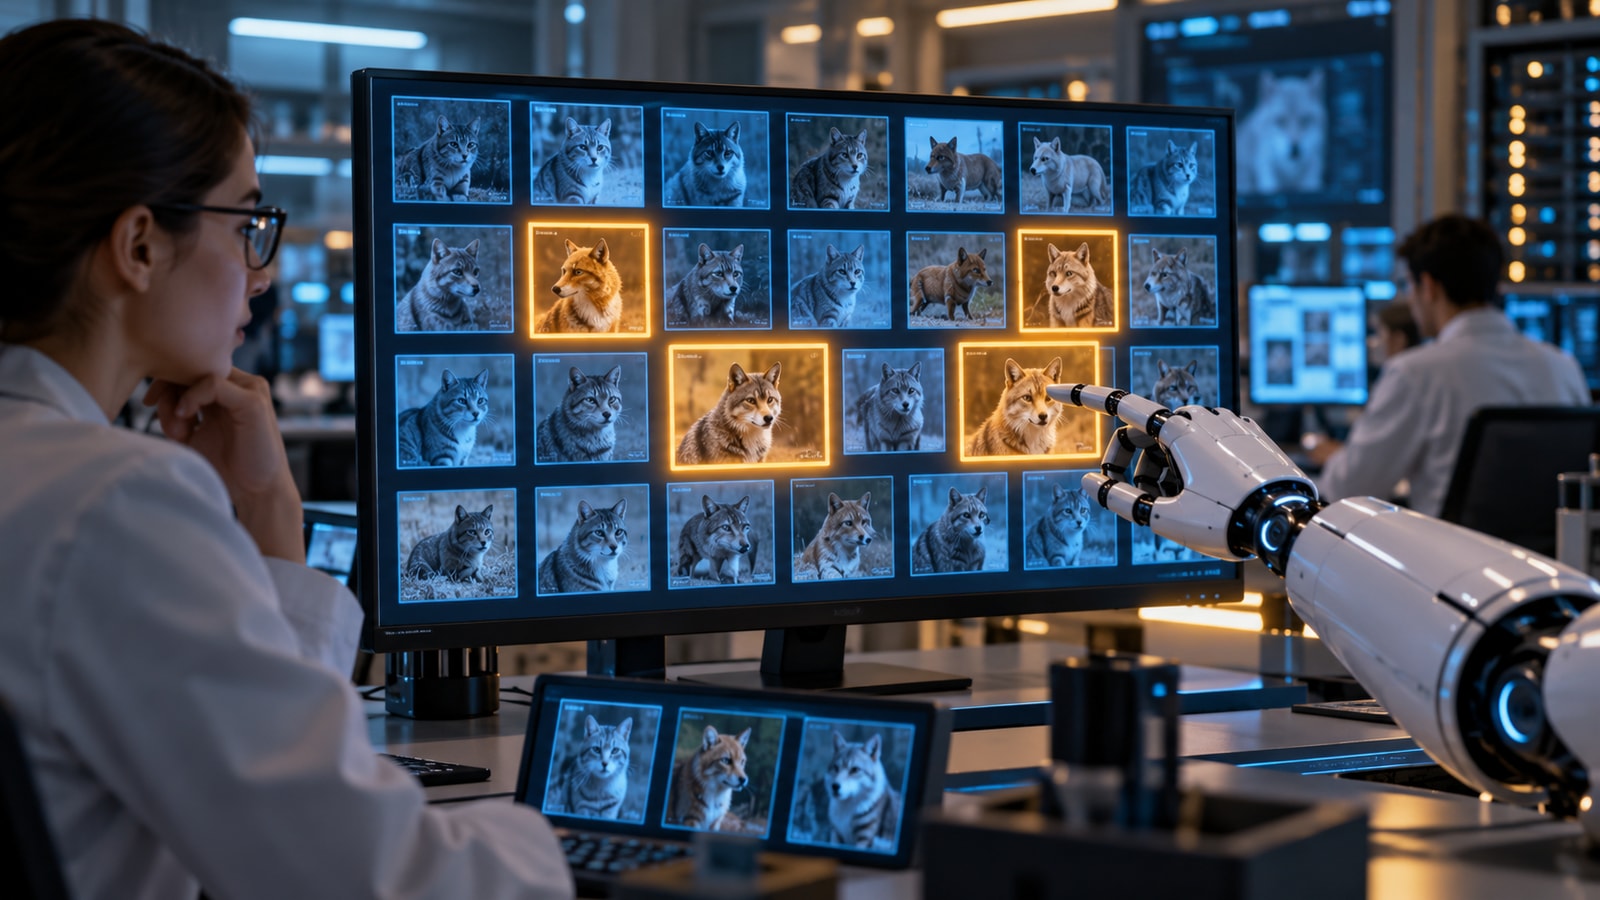
Hard Negative Mining Explainer
Hard negative mining finds training examples that are incorrect matches but look deceptively similar to the correct answer. These examples create a stronger learning signal than negatives the model already separates easily.
A retrieval model may search its current index for high-scoring nonrelevant passages, or select difficult examples within a training batch. The loss then pushes those negatives away from the query while pulling the positive closer.
The method is used in dense retrieval, face and product matching, contrastive learning, detection, and recommendation. It helps a model learn boundaries among easily confused cases.
A supposed negative may actually be relevant but unlabeled, creating a false negative. The hardest examples can also be outliers or annotation errors. Mining should combine data cleaning, diversity, curriculum, and evaluation on new queries.
Hard negative mining selects incorrect examples that closely resemble correct matches so a model learns finer distinctions.
Key terms include hard negative, positive example, false negative, contrastive loss, in-batch negative, mining, similarity and curriculum.
The model focuses on nonmatches it currently scores too highly.
Training contrasts those examples with genuine positives to refine the representation.
Incomplete relevance labels can turn a valid answer into a damaging false negative.
Filtering, diversity, and gradual difficulty reduce unstable training.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.