

Grouped-Query Attention Explainer
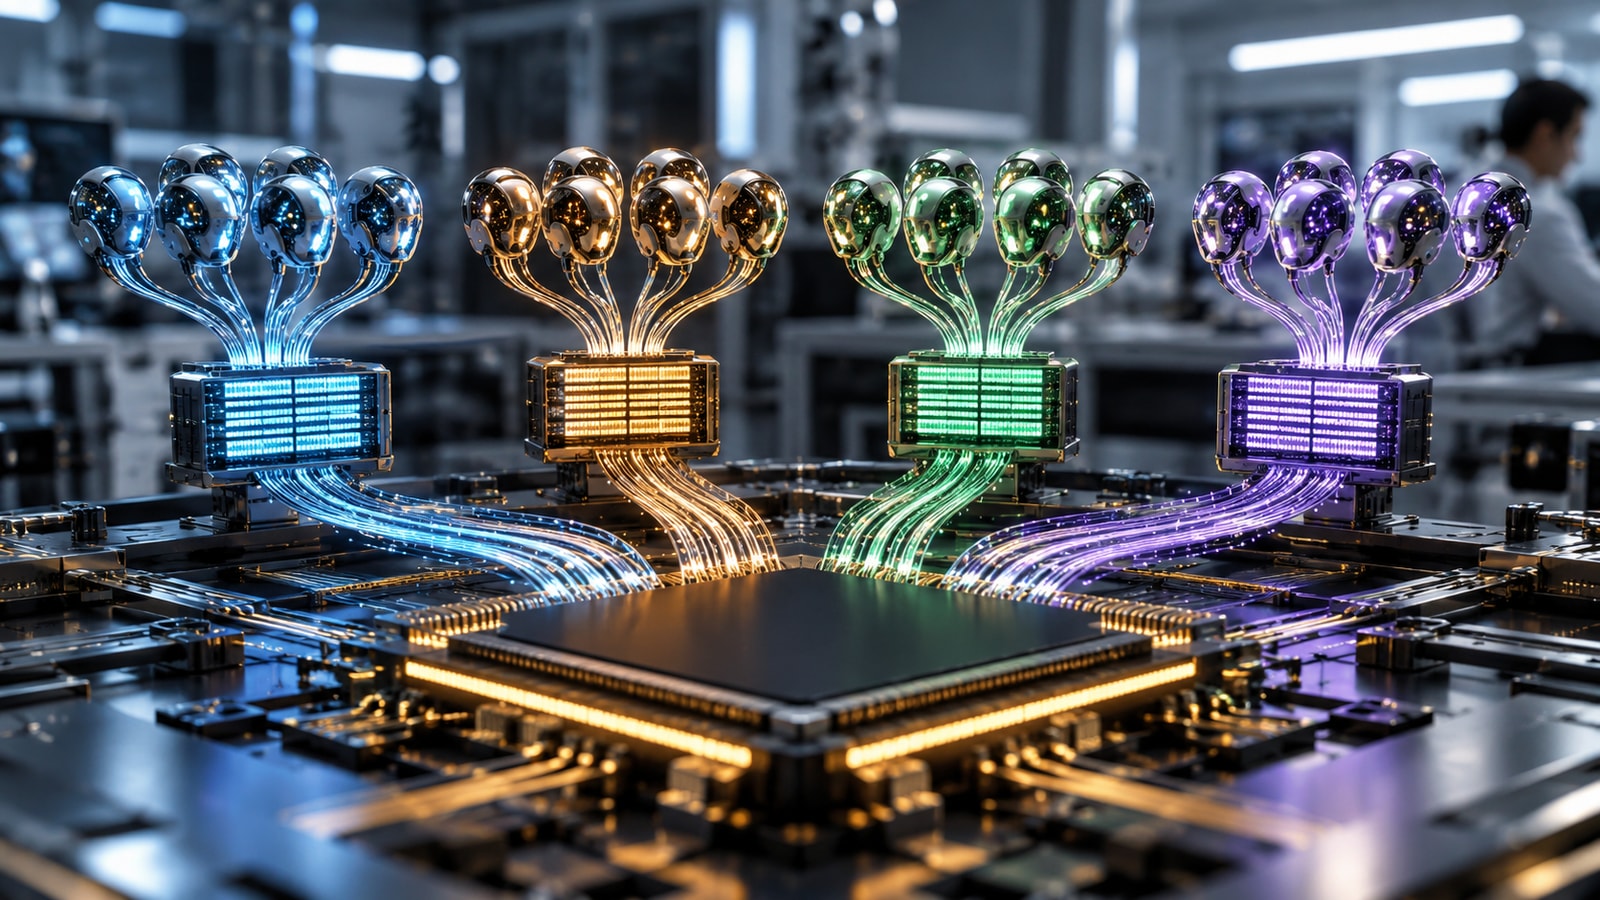
Grouped-query attention, or GQA, divides query heads into groups. Every group shares one key head and one value head. It sits between full multi-head attention, where each query head has its own keys and values, and multi-query attention, where all share one pair.
The number of key-value groups controls the tradeoff. Fewer groups shrink the key-value cache and reduce memory bandwidth; more groups give the model additional representational capacity.
GQA is used in large language models to improve inference efficiency without the full quality cost that multi-query attention can introduce. Existing multi-head models can sometimes be converted with additional training.
There is no universally best group count. Hardware, model width, context length, batch size, and training recipe all matter. Evaluation should pair generation quality with cache memory, latency, throughput, and conversion cost.
Grouped-query attention places query heads into groups that share key and value heads, balancing multi-head quality with multi-query efficiency.
Key terms include grouped-query attention, GQA, query head, key-value head, group, KV cache, memory bandwidth, latency and throughput.
Several query heads read from one key-value head instead of each owning a separate copy.
The group count provides a tunable middle ground between two attention designs.
More sharing saves cache memory, while less sharing preserves capacity.
End-to-end tests must include the intended hardware and workload.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.