

Federated Averaging Explainer
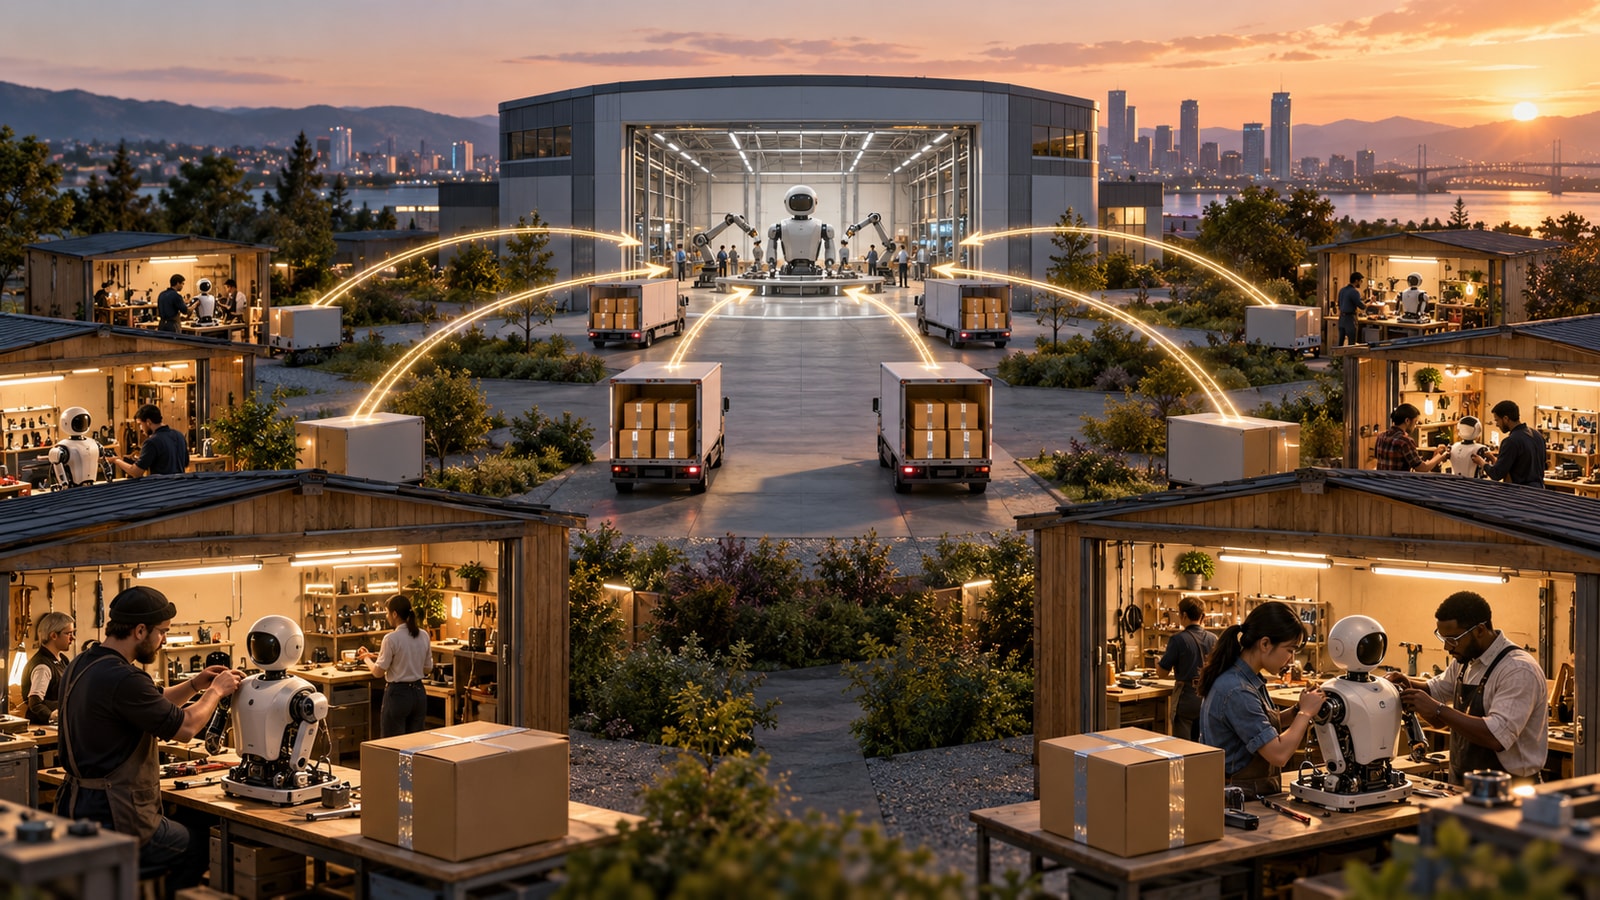
Federated averaging, often called FedAvg, is an algorithm for federated learning. A server sends a current model to selected clients, and each client trains it for several local steps using data stored on that device or organization.
Clients send model updates back rather than raw examples. The server combines those updates, commonly with weights based on local data volume, to produce the next global model. The process repeats over many communication rounds.
Local computation reduces how often clients must communicate and allows training across data that cannot be easily centralized. The method helped establish the practical pattern used by many federated-learning systems.
Client data is usually non-identically distributed, devices vary in speed, and only some clients participate in each round. FedAvg alone is not a privacy guarantee: updates can leak information, so secure aggregation, clipping, and differential privacy may be needed.
Federated averaging trains a shared model by aggregating updates produced locally on many clients rather than centralizing their raw training data.
Key terms include federated averaging, FedAvg, client, server, local training, model update, communication round, non-IID data and aggregation.
Selected clients train copies of the current model on their own local examples.
The server averages returned updates to form the next global checkpoint.
Model updates may reveal information even when raw examples never leave a client.
Secure aggregation and privacy mechanisms address risks that averaging alone does not solve.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.