

Data Poisoning in AI Explainer
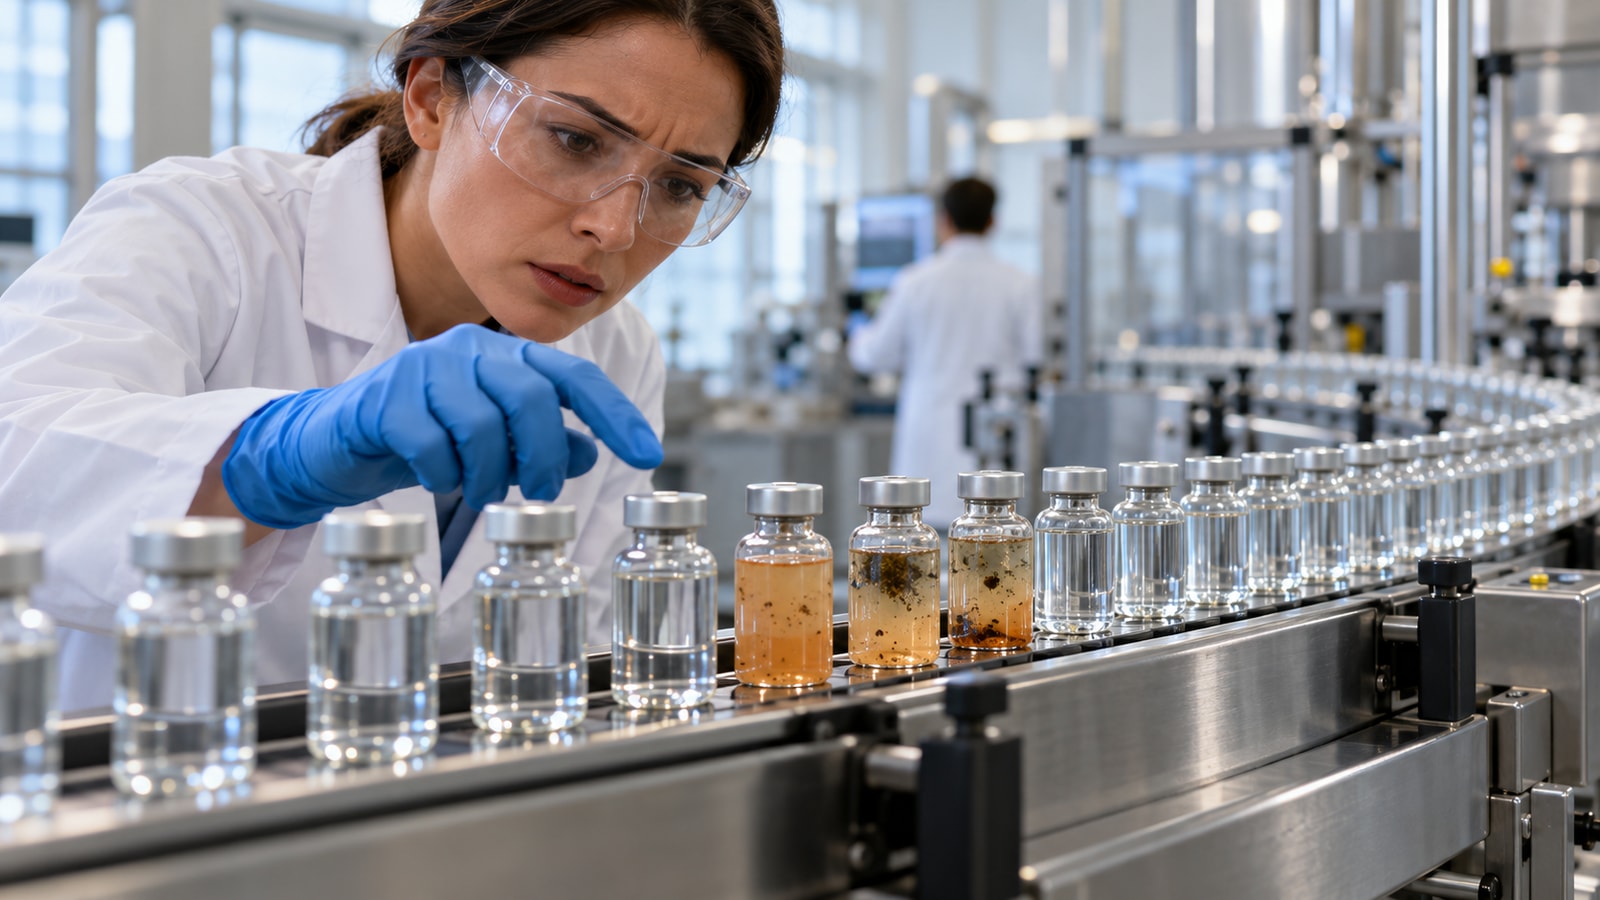
Data poisoning is an attack on the information used to train or update a machine-learning model. An attacker adds, removes, relabels, or modifies examples so the learning process produces a harmful or unreliable result.
Some poisoning attacks reduce overall accuracy, while targeted attacks try to change predictions for particular inputs. The attacker may influence a public dataset, a feedback channel, a federated-learning client, or another source that feeds training data.
The danger comes from persistence: once a poisoned pattern is learned, the model can appear normal during ordinary testing yet fail under selected conditions. Large datasets make a small number of malicious records difficult to notice.
Defenses include tracking data provenance, limiting who can contribute, screening for unusual clusters, comparing trusted validation sets, and monitoring model changes. No single filter catches every attack, so controls should cover the full data pipeline.
Data poisoning deliberately contaminates training data so an AI model learns distorted patterns, weaker performance, or attacker-chosen behavior.
Key terms include poisoned sample, training set, target, relabeling, provenance, validation, anomaly, pipeline and threat model.
Poisoned records influence the model during training or updating.
The resulting behavior may persist across many later predictions.
A harmful example may look plausible when reviewed by itself.
Provenance, trusted tests, statistical screening, and access controls must work together.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.