

AI Data Provenance Explainer
AI data provenance is the documented history of data used to train, evaluate, or operate an AI system. It records origins, responsible people or organizations, transformations, derived versions, and movement through the pipeline.
A provenance trail might connect a raw source to filtering, annotation, deduplication, feature generation, dataset releases, and model runs. It can also record licenses, permissions, timestamps, hashes, and tools used along the way.
This history supports reproducibility and investigation. When a model behaves unexpectedly, teams can trace which data version was involved, identify where a questionable record entered, and assess which downstream artifacts may be affected.
Provenance is not the same as ordinary metadata. File size is metadata; the source and processing history are provenance. Useful records must be durable, queryable, and protected from silent alteration or incomplete handoffs.
AI data provenance is the recorded history of where data originated, who or what changed it, and how it moved through a system.
Key terms include provenance, origin, entity, activity, actor, derivation, revision, lineage, hash and reproducibility.
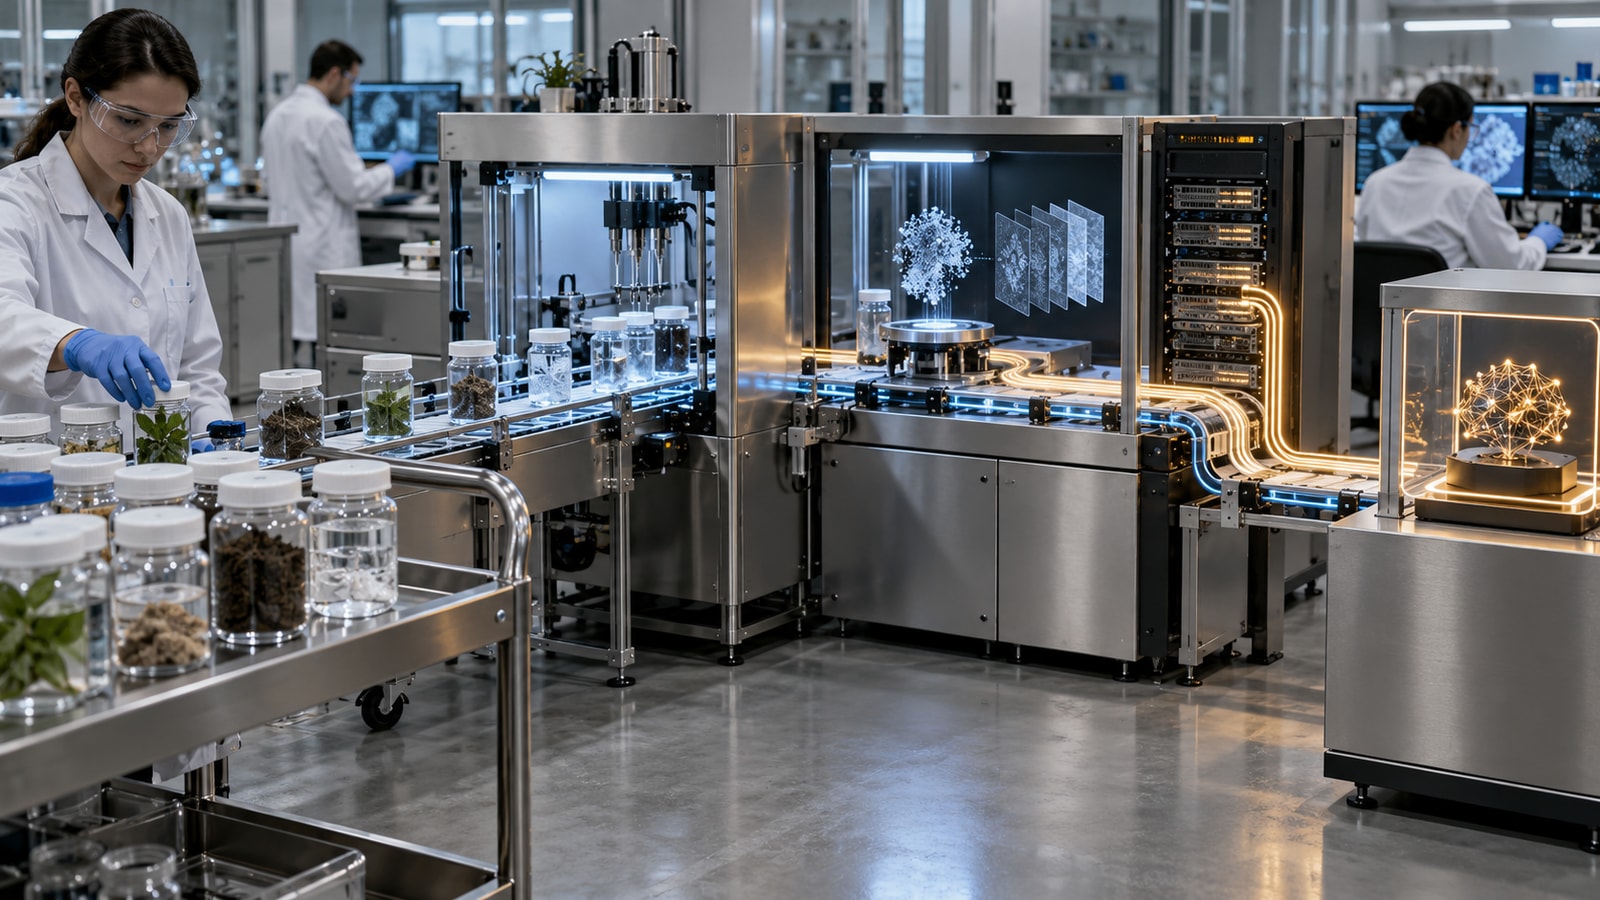
Each transformation creates another link between raw material and a deployed artifact.
The links help teams reproduce work and locate the source of a problem.
A record is useful only if it stays attached across tools, teams, and versions.
Stable identifiers and protected logs reduce gaps in the chain of custody.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.