

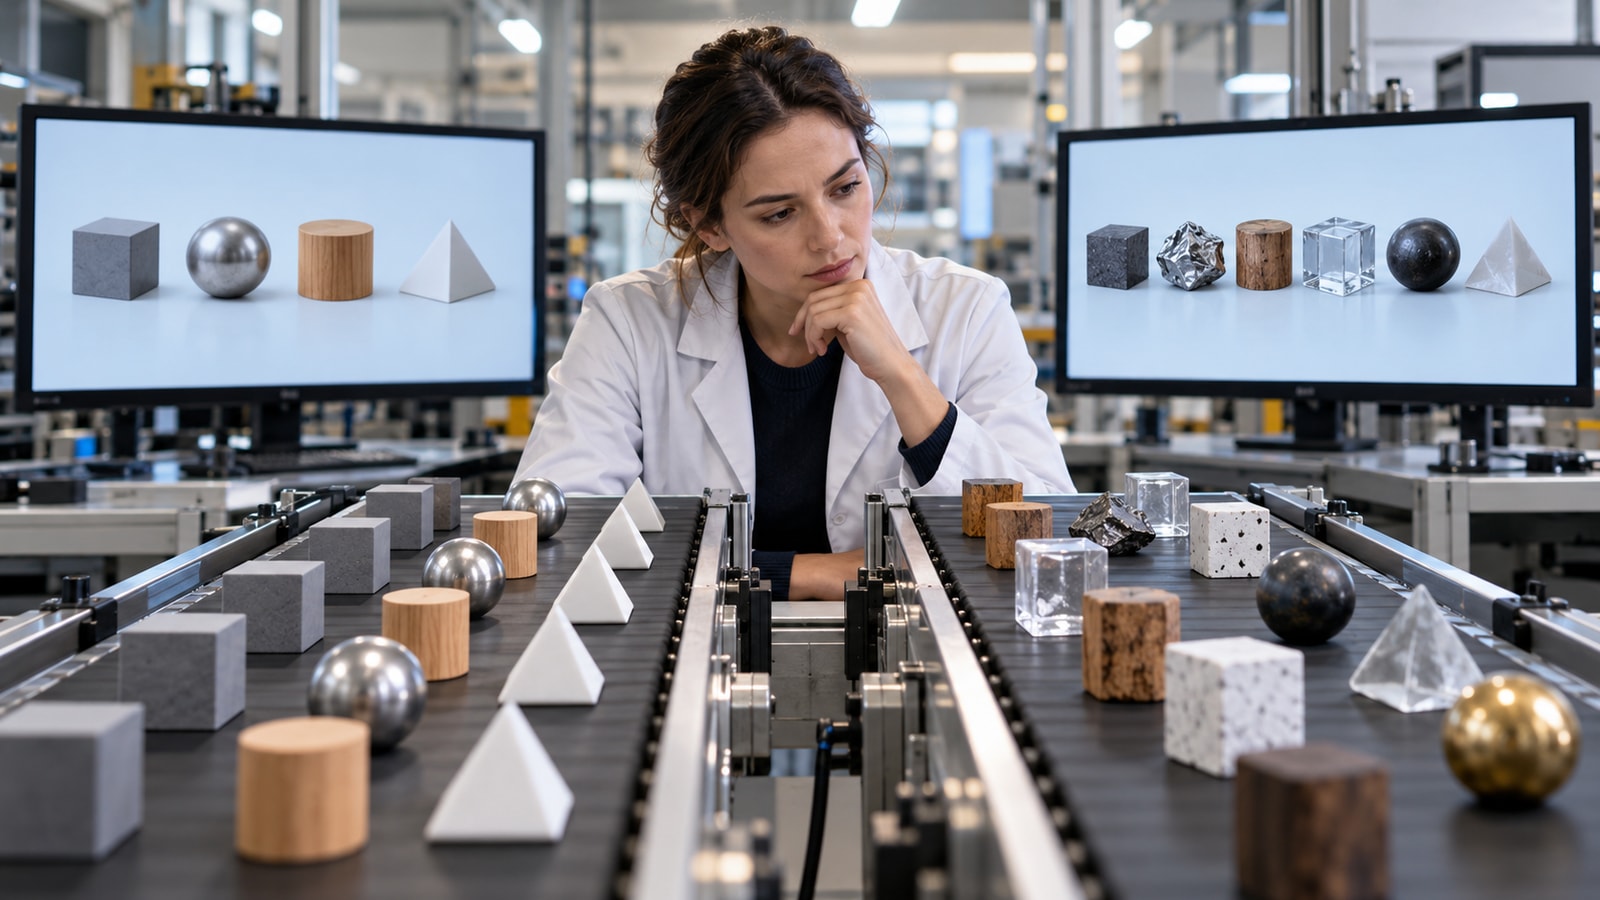
Data Drift Explainer
Data drift is a measurable change in the distribution of data reaching an AI system. Teams compare recent inputs, features, or outputs with a baseline such as training data or an earlier production period.
The change may involve averages, ranges, categories, correlations, missing values, or rare events. A new user population, season, sensor, interface, supplier, or data pipeline can all alter what the model receives.
Drift is an early warning, not proof that predictions are wrong. Some distribution changes do not affect performance, while serious performance loss can occur without an obvious shift in the monitored features.
Teams choose statistical tests or distance measures, thresholds, windows, and important features. They investigate alerts with context and outcome data before deciding whether to retrain, repair a pipeline, change a baseline, or accept the variation.
Data drift is a change in the statistical distribution of data seen in production compared with a chosen reference period or training set.
Key terms include data drift, distribution, baseline, feature, reference window, distance measure, threshold, alert and investigation.
The result depends on which reference data and time window are selected.
A poor baseline can make normal seasonality look like a serious anomaly.
A distribution shift may be harmless, beneficial, or operationally expected.
Performance evidence and domain context determine whether the model needs intervention.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.