

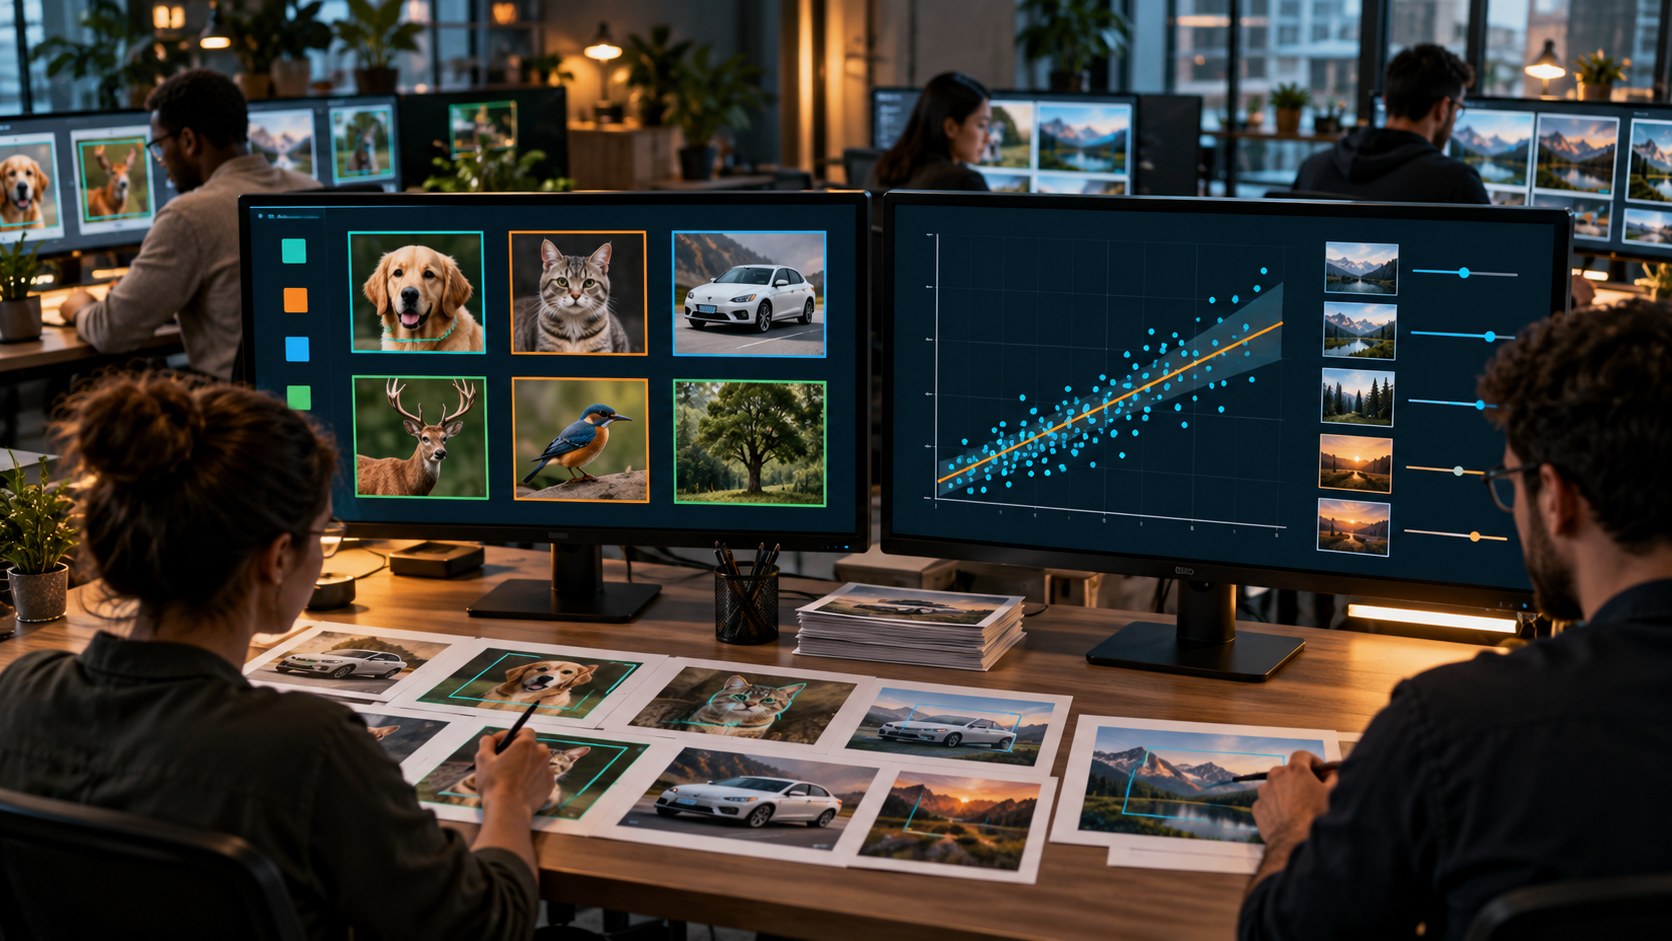
Supervised Learning Explainer
Supervised learning trains a model with examples that include both an input and a desired output. The desired output is called a label or target. A spam filter learns from messages labeled spam or not spam, while a price model learns from properties paired with recorded sale values.
Classification predicts categories; regression predicts numerical values. During training, a loss function measures the difference between the model’s prediction and the target. An optimization method adjusts parameters to reduce that loss across many examples.
Data is usually divided into training, validation, and test sets. The training set teaches the model, validation guides design choices, and the test set estimates performance on unseen cases. Cross-validation can provide a more stable estimate when data is limited.
Labels are not neutral ground truth simply because they are in a spreadsheet. They can contain mistakes, inconsistent judgments, outdated definitions, or historic discrimination. Leakage can also give the model information it would not have in real use. Strong projects document labels, examine subgroup errors, and test the full deployment process.
Supervised learning trains a model on examples paired with labels or target values so it can predict outcomes for new inputs.
Key terms include supervised learning, label, target, feature, classification, regression, loss, training set, validation set and test set.
<a href="https://developers.google.com/machine-learning/crash-course/" target="_blank" rel="noopener noreferrer">Google Machine Learning Crash Course</a> and <a href="https://scikit-learn.org/stable/supervised_learning.html" target="_blank" rel="noopener noreferrer">scikit-learn: Supervised Learning</a> provide the primary references for this explainer.
Classification chooses among categories, often with probabilities. Regression estimates a continuous value such as demand, temperature, or price.
Both learn from labeled examples, but they use different outputs, loss functions, and evaluation metrics.
Inaccurate, inconsistent, or unrepresentative labels teach the model the wrong task. Historic labels may encode decisions that should not be repeated.
Audit label creation, prevent data leakage, measure subgroup performance, and keep a genuinely unseen test set.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.