

AI Safety Guardrails Explainer
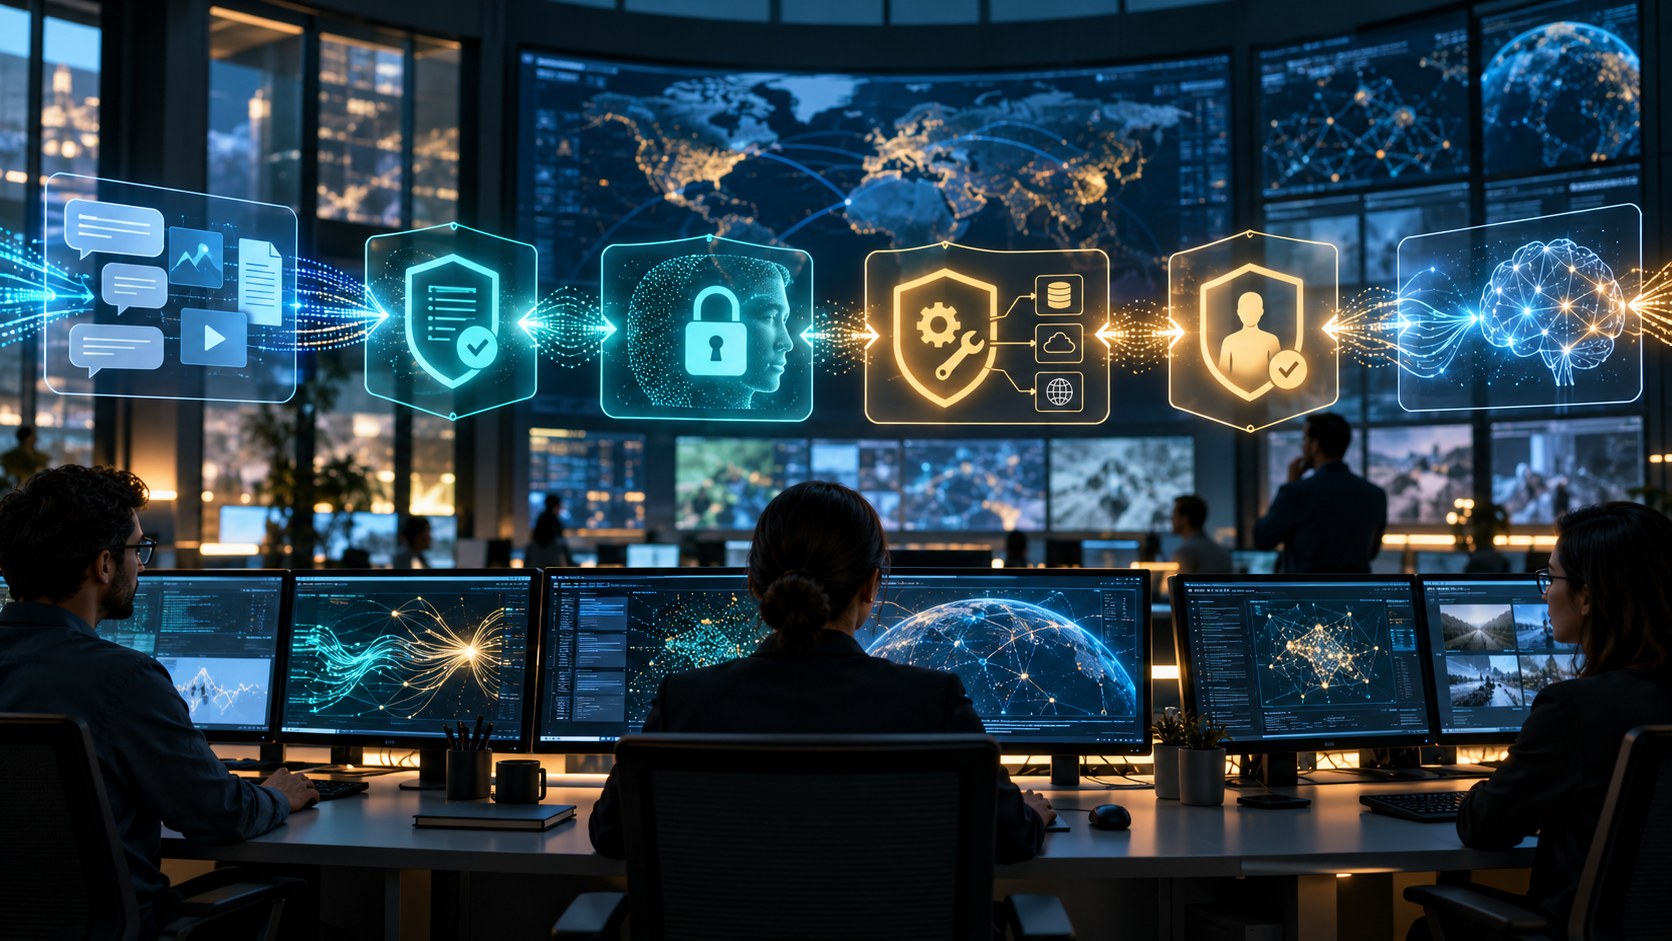
AI safety guardrails are rules, models, checks, and operational controls designed to keep an AI application within acceptable boundaries. They can inspect user input, restrict topics, validate model output, protect private data, limit tool permissions, or require human approval before a consequential action.
Guardrails can operate at several layers. A policy may define prohibited behavior; classifiers can detect harmful content; structured validators can reject malformed output; allowlists can constrain tools; and monitoring can flag unusual patterns after deployment. Strong systems combine controls instead of relying on one filter.
Guardrails help translate risk decisions into technical and organizational practice. They are especially important when a model can access private information, write code, make transactions, or communicate externally. Logs and evaluations show whether controls work under realistic and adversarial conditions.
No guardrail is perfect. Attackers can rephrase requests, benign content can be blocked, context can confuse classifiers, and a model may find a path the designer did not anticipate. Guardrails should be treated as defense in depth, supported by least-privilege access, red teaming, incident response, and human accountability.
AI safety guardrails are layered rules, models, checks, and controls intended to limit harmful or unauthorized system behavior.
Key terms include guardrail, input rail, output rail, policy, content filter, validator, allowlist, least privilege, red team and defense in depth.
<a href="https://docs.nvidia.com/nemo-guardrails/" target="_blank" rel="noopener noreferrer">NVIDIA NeMo Guardrails Documentation</a> and <a href="https://nvlpubs.nist.gov/nistpubs/ai/NIST.AI.600-1.pdf" target="_blank" rel="noopener noreferrer">NIST Generative AI Profile</a> provide the primary references for this explainer.
Input checks can detect risky requests; output checks can block or revise responses; tool controls can limit which actions the system may take.
Policy, product design, permissions, monitoring, and incident response are also guardrails even when they are not part of the model.
Filters can be bypassed or over-block harmless use, and model-based safeguards can share weaknesses with the systems they monitor.
Evaluate adversarially, keep privileges narrow, log decisions, support appeals, and plan for failures instead of claiming perfect prevention.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.