

AI Model Distillation Explainer
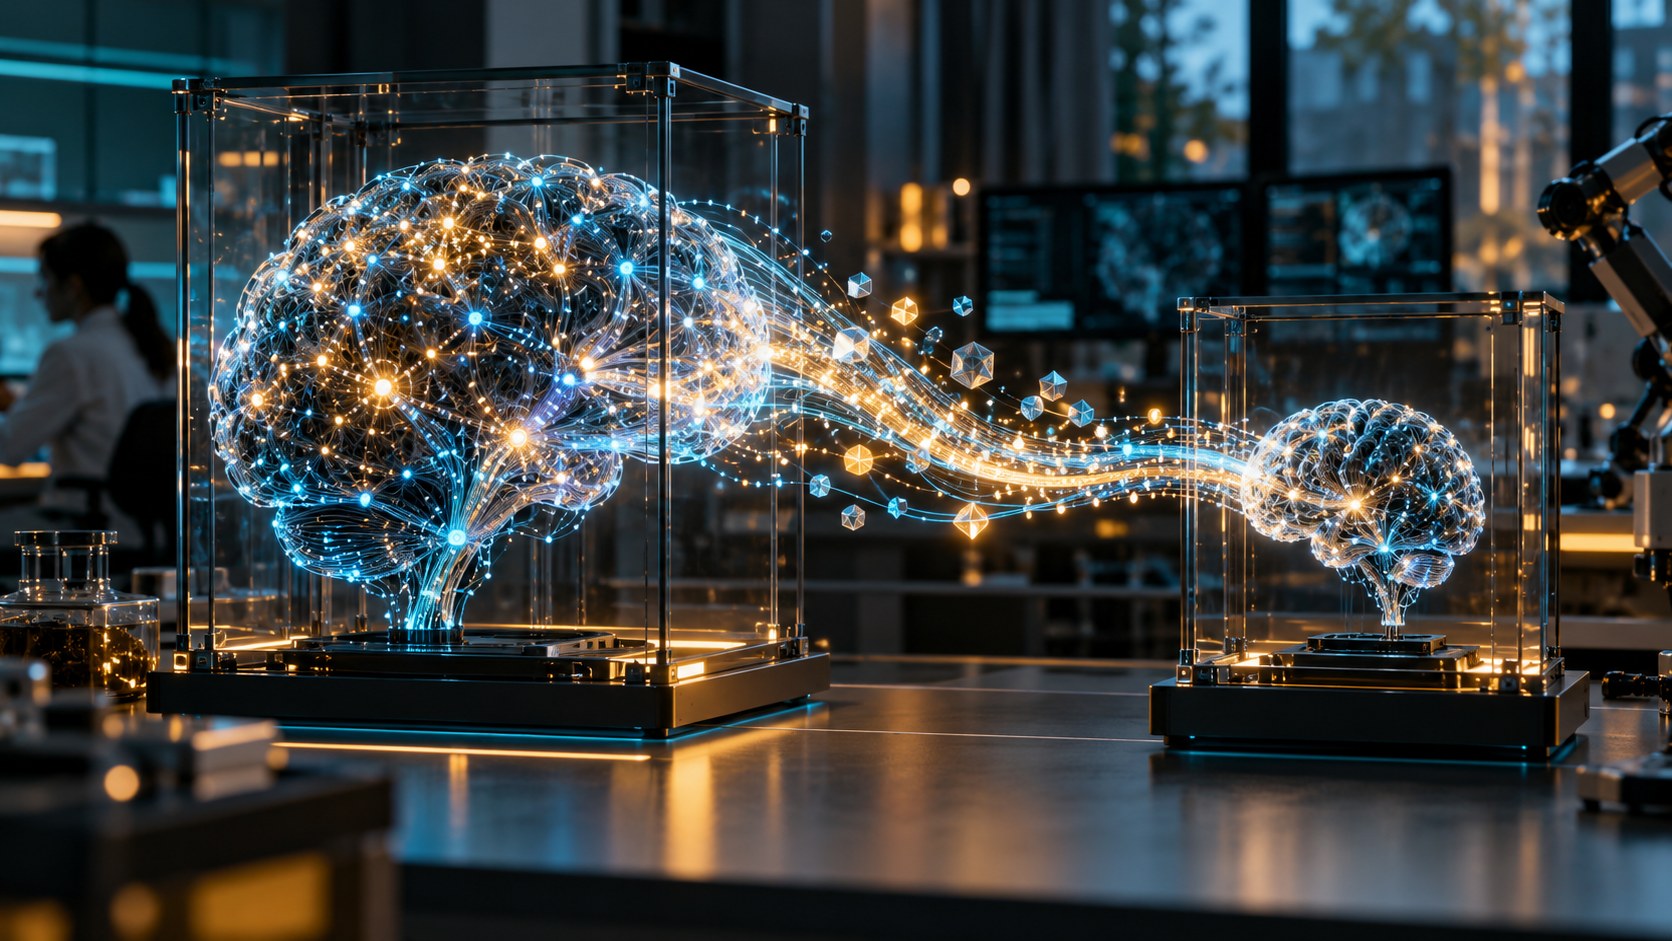
AI model distillation is a training technique that transfers useful behavior from a larger or more complex teacher model into a smaller student model. Instead of learning only from hard labels, the student can learn from the teacher’s probability distribution, generated examples, intermediate representations, or structured feedback.
The teacher’s softer outputs reveal relationships that a single correct label may hide. For example, the teacher may consider several classes plausible with different probabilities. A training objective balances imitation of the teacher with the original task labels or other quality signals.
Distillation can reduce model size, memory use, latency, and serving cost while preserving much of the teacher’s performance. It helps deploy models on edge devices, handle high request volumes, or create specialized students for narrower tasks.
A student does not inherit only strengths. It can reproduce the teacher’s bias, unsafe behavior, and systematic errors, and may lose rare capabilities that average tests miss. Teams should compare teacher and student across representative, adversarial, subgroup, and safety evaluations, then decide whether the efficiency gain justifies the quality change.
Model distillation trains a smaller student model to reproduce useful behavior learned by a larger teacher model.
Key terms include knowledge distillation, teacher model, student model, soft target, probability distribution, imitation, compression, latency and evaluation.
<a href="https://arxiv.org/abs/1503.02531" target="_blank" rel="noopener noreferrer">Distilling the Knowledge in a Neural Network</a> and <a href="https://huggingface.co/docs/transformers/tasks/knowledge_distillation_for_image_classification" target="_blank" rel="noopener noreferrer">Hugging Face: Knowledge Distillation for Computer Vision</a> provide the primary references for this explainer.
The teacher produces targets richer than a single label, and the student is trained to approximate those outputs with fewer parameters or a simpler architecture.
Distillation may use logits, generated examples, hidden representations, or task-specific feedback depending on the models and objective.
A smaller student may preserve average benchmark performance while losing robustness, rare knowledge, calibration, or safety behavior.
Evaluate the deployed student directly; do not assume the teacher's documentation or safeguards automatically transfer.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.