

Large Language Models Explainer
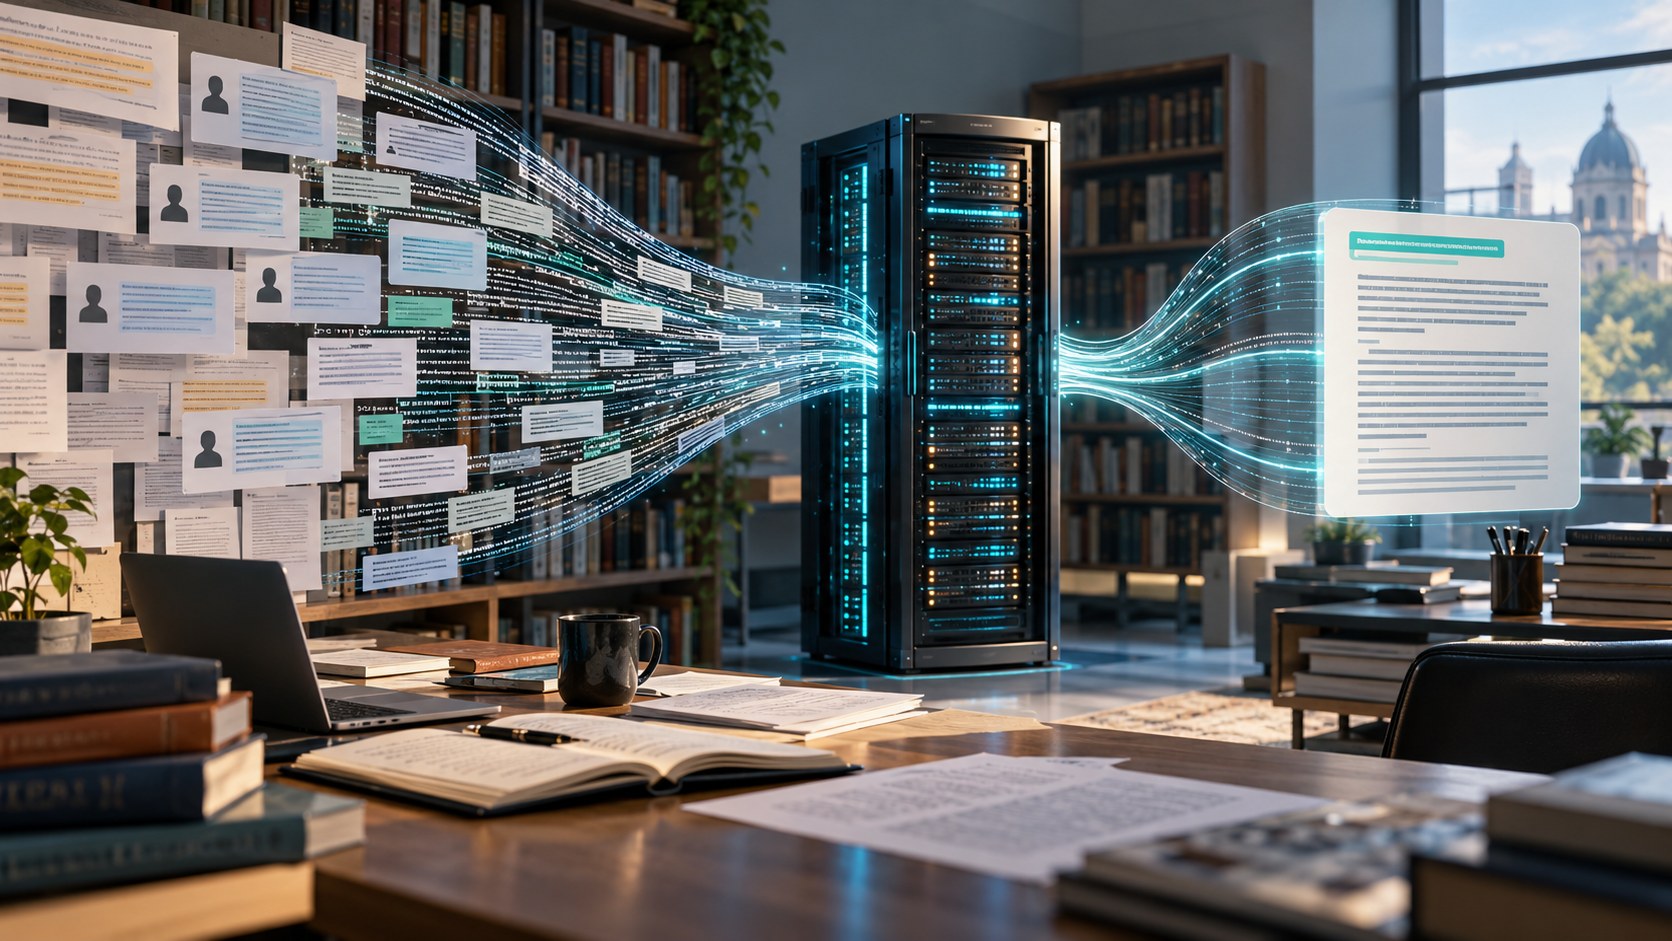
A large language model, or LLM, is a neural network trained to model patterns in language at very large scale. Most modern LLMs receive text as tokens and learn to predict a missing or next token from the surrounding sequence. Repeating that objective across huge datasets creates a flexible language generator.
The word large can describe the number of parameters, the amount of training data, the computing used, or all three. Transformer architectures let models connect information across a sequence, while pretraining builds general representations that can later be adapted through prompting, fine-tuning, retrieval, or other methods.
An LLM can summarize, translate, classify, draft, answer questions, and assist with code because many tasks can be expressed in language. These abilities are learned statistically rather than installed as a database of verified facts or a humanlike understanding of every subject.
Fluent output can conceal hallucinations, bias, security weaknesses, or outdated knowledge. Model size alone does not establish quality. Reliable use requires task-specific evaluation, grounding, privacy controls, monitoring, and human judgment when an error could materially affect people.
A large language model is a neural network trained on extensive text data to predict and generate sequences of language.
Key terms include token, parameter, transformer, pretraining, next-token prediction, context, fine-tuning and evaluation.
Pretraining adjusts billions of numerical parameters so the model becomes better at predicting tokens across many examples. Post-training can refine instruction following or specialized behavior.
At inference time, the model repeatedly estimates a probability distribution for the next token and selects tokens according to decoding settings until the response is complete.
Broad language skill does not mean the model possesses a verified world model, stable reasoning process, or guaranteed access to current information.
Evaluators should measure accuracy, calibration, robustness, harmful bias, privacy, latency, and cost in the exact setting where the model will be used.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.