

“The intelligence of a system is a measure of its skill-acquisition efficiency over a scope of tasks.”
François Chollet’s 2019 paper “On the Measure of Intelligence” argues that task performance alone is a poor measure of intelligence. A system can achieve high skill through enormous training data, specialized priors, or direct exposure to similar examples. Chollet instead focuses on how efficiently a system acquires new skills across a defined scope, accounting for prior knowledge, experience, and the difficulty of generalization. The line has lasted because it captures a research turning point without pretending that one paper settled every scientific or social question around it.
The definition separates skill from intelligence. Skill is demonstrated performance on a task; intelligence concerns the process that turns limited information into new capability. Two systems can reach the same score while differing greatly in the data and built-in assumptions they required. A meaningful comparison must therefore disclose experience and priors rather than presenting the final benchmark result as though it appeared from nowhere. The sentence also shows why definitions matter. When researchers specify what they are measuring, disagreement can become an experiment instead of a contest between impressions.
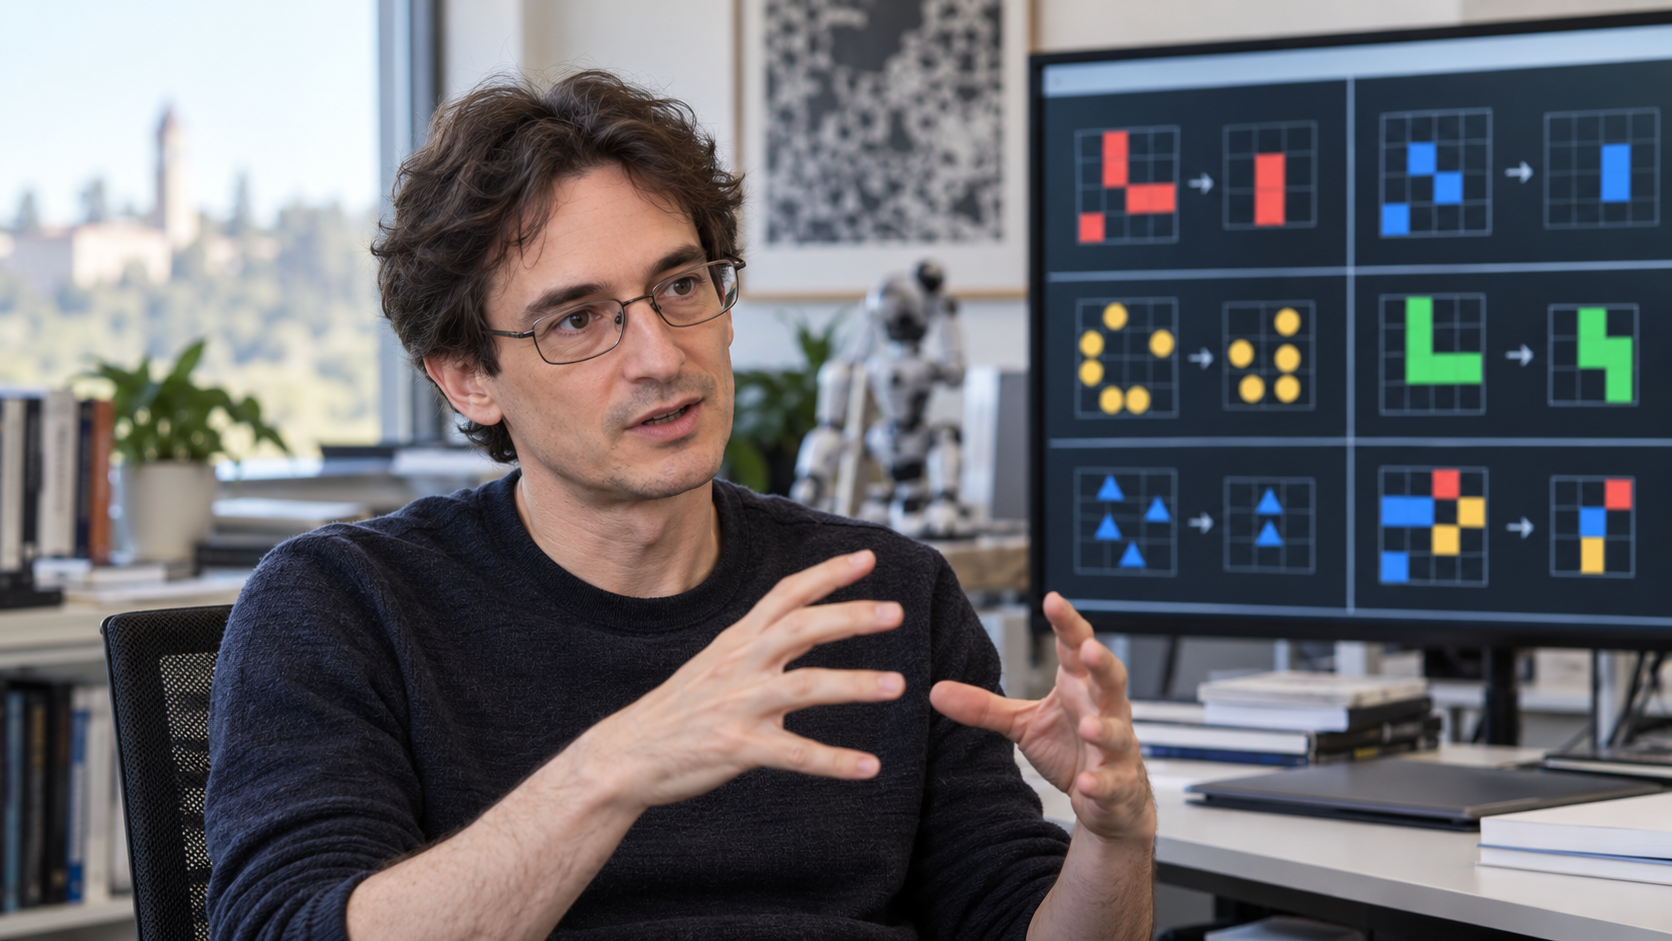
The argument motivated the Abstraction and Reasoning Corpus, a set of tasks designed to emphasize flexible inference from a few examples. It also informs debates about benchmark contamination and whether large models generalize or retrieve familiar patterns. Evaluators should use novel tasks, control exposure, vary surface details, and examine the sample efficiency of adaptation. No single benchmark can represent every legitimate scope of intelligence. For present-day teams, the lesson is to translate broad enthusiasm into observable outcomes. A strong deployment plan names users, failure modes, review points, and the evidence that would justify changing course.
Human-like generalization is not the only useful form of computation, and narrow systems can create substantial value. Problems arise when specialized competence is marketed as broad intelligence or when benchmark success is mistaken for readiness in the world. Definitions should match the claim, and deployment should be based on the actual capabilities and limitations relevant to the task. The most durable response is neither reflexive celebration nor blanket rejection. It is disciplined adoption: verify the benefit, disclose the limitation, and preserve a workable human alternative. Chollet’s formulation makes efficiency and novelty central. It asks not only what a system can do, but how much prior structure and experience it needed to learn to do it. Responsible progress depends on maintaining that distinction. Technical possibility opens a door, while public value depends on careful implementation, meaningful oversight, and the ability to learn from failure. The work continues with care.
Skill is performance on a task, while intelligence concerns efficient acquisition of new skills under uncertainty.
A system can display high skill through extensive training or specialized priors without strong generalization.
Fair comparisons should account for training exposure, built-in knowledge, data volume, and similarity to evaluation tasks.
Otherwise a benchmark may reward memorization or engineering resources while being described as a measure of intelligence.
Intelligence measures always depend on a chosen scope of tasks, values, and assumptions about generalization.
Novel evaluations, contamination controls, and transparent claims help keep results proportional to the evidence.
Explore more "Quotes of The Day"
Continue exploring how writers, thinkers, artists, and advocates have described the choices that shape an everyday life.