

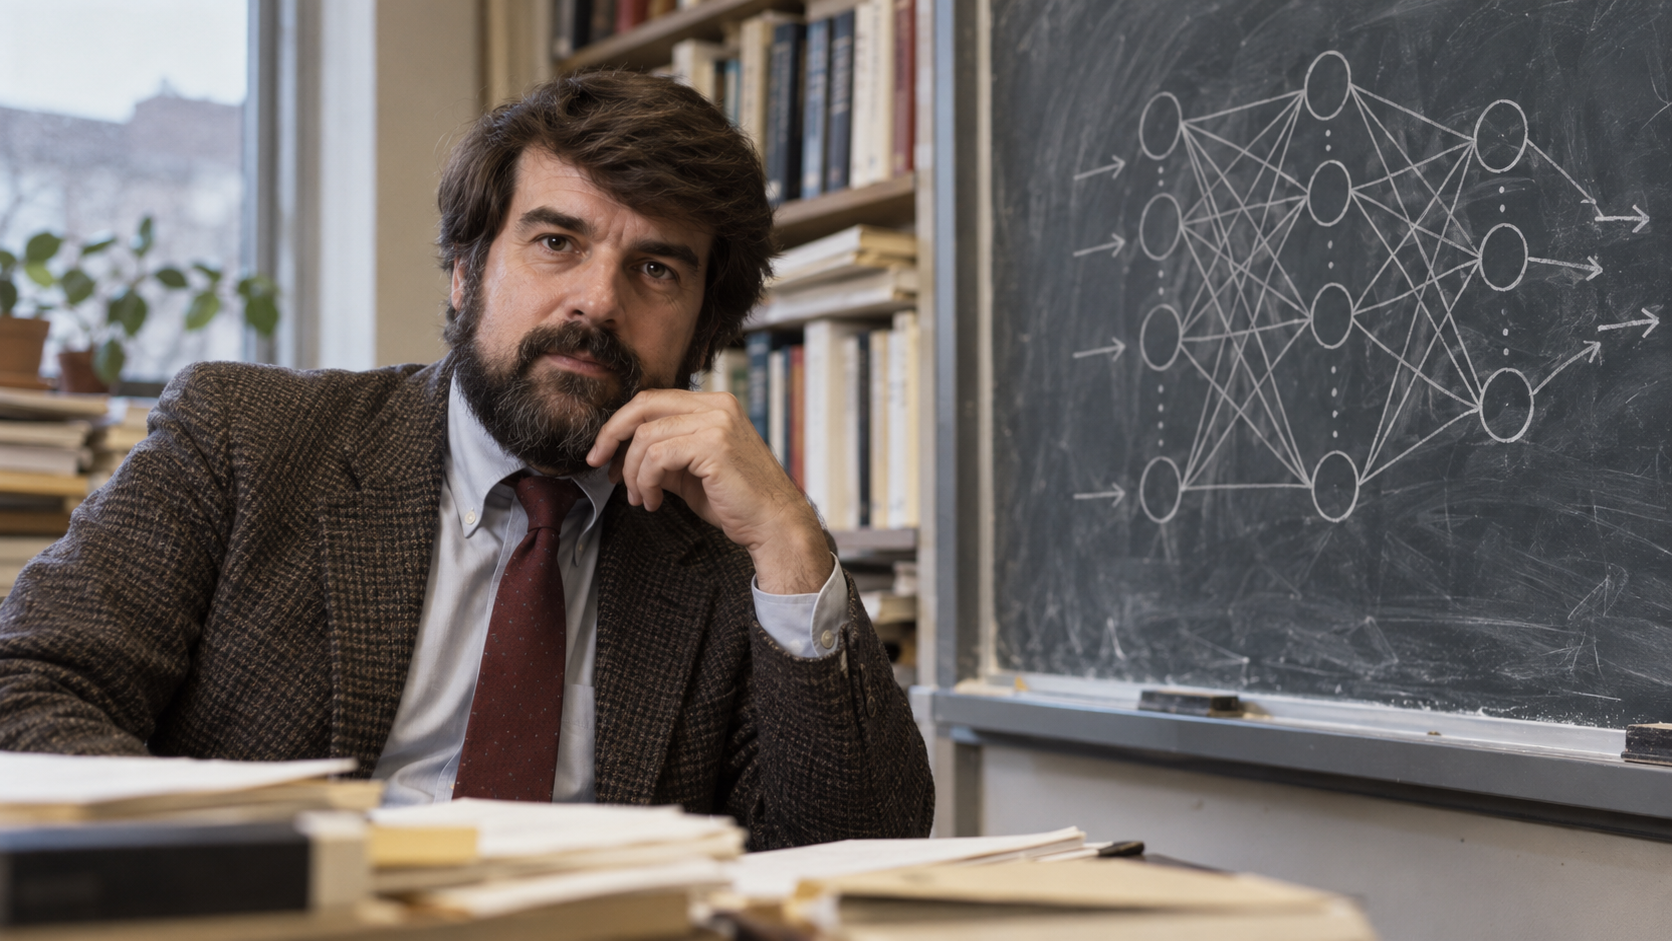
“We describe a new learning procedure, back-propagation, for networks of neurone-like units.”
David Rumelhart, Geoffrey Hinton, and Ronald Williams presented back-propagation as a practical way to adjust connections inside layered networks. The procedure measures how an output differs from a target and propagates information about that error backward through the layers. Earlier researchers knew related calculus, but the 1986 paper demonstrated how the method could learn internal representations that made difficult mappings tractable and renewed interest in connectionist approaches. Placed back in its source, the sentence reads as a testable research claim, not a prediction that every related problem has been solved.
The crucial idea is credit assignment. When many hidden units contribute to one prediction, a learning system needs a principled way to estimate how each connection affected the error. Back-propagation applies the chain rule to compute those contributions efficiently. Hidden layers can then organize features that were never labeled directly. The network is not given a symbolic description of every useful concept; structure develops because it helps reduce the training objective. This also shows why benchmark performance and real-world value are different questions. Each depends on assumptions that must be made visible before trust is earned.
Variants of back-propagation remain central to training deep networks for language, vision, speech, and scientific modeling. Automatic differentiation makes the calculation routine, while specialized hardware performs it at enormous scale. Yet the original logic is still visible: define an objective, run examples forward, measure error, and send corrective information backward. Practitioners should inspect each part, because a poor target or unrepresentative dataset can be optimized just as efficiently as a good one. Organizations should pair technical measures with outcome measures: who benefits, who absorbs errors, how quickly failures are detected, and whether a workable appeal process exists.
Optimization does not guarantee understanding, truth, or social value. A network may minimize its loss by exploiting shortcuts in the data, memorizing sensitive information, or improving an average while harming a subgroup. The gradient only reflects the objective it receives. Responsible teams therefore need thoughtful target design, representative evaluation, privacy protections, and tests for behavior that a single score can conceal. Teams should be ready to learn from failure. Clear incident reporting, redress, and periodic reassessment turn responsible use from a promise into an operating practice. The 1986 paper made multilayer learning practical enough to inspire generations of experiments. Its deeper lesson is that an efficient learning rule is powerful only when paired with an objective worth learning. That balance allows the field to honor a real breakthrough without turning it into a shortcut around evidence, oversight, or human judgment. The research becomes more valuable when later users preserve its conditions, test competing explanations, and connect technical performance to the outcomes people actually experience.
A forward pass produces an output and a loss measures the difference from the target.
A backward pass uses derivatives to assign portions of that error to connections throughout the network.
Hidden units can learn intermediate features that make a complex input-output relationship easier to represent.
Those representations emerge from training rather than from a person labeling every internal concept.
Back-propagation efficiently follows the objective supplied by designers and data.
Teams must still verify that the objective reflects real needs and does not reward shortcuts, leakage, or unequal harm.
Explore more "Quotes of The Day"
Continue exploring how writers, thinkers, artists, and advocates have described the choices that shape an everyday life.