

“We present a residual learning framework to ease the training of networks that are substantially deeper than those used previously.”
Kaiming He and colleagues introduced residual learning after observing that simply stacking more layers could make even training accuracy worse. Their residual block adds a shortcut path that carries an input forward while the learned layers model a change relative to it. This reformulation improved gradient flow and enabled networks with dozens or hundreds of layers to train successfully, producing landmark results in image recognition. The original wording matters because it fixes the claim to a particular experiment, method, and moment instead of the larger mythology that later formed around it.
A residual connection gives the network an easier option: preserve information through an identity path and learn only the transformation needed on top. If a group of layers is unnecessary, it can approximate zero rather than reconstructing the input from scratch. This simple change alters the optimization landscape without dictating what features must be learned. It became a general pattern for building deep computational systems. Separating the method from the marketing makes the insight stronger, because readers can see exactly which capability improved and which judgments remain human responsibilities.
Residual pathways appear across vision models, language systems, speech networks, and scientific architectures. They support stable training, reuse of representations, and iterative refinement. Yet depth is a design choice, not an automatic virtue. Teams should ask whether additional layers improve relevant outcomes enough to justify added compute, latency, and maintenance. Ablations and smaller baselines help reveal what the complexity is actually buying. The practical test is not whether a demonstration looks impressive, but whether the approach remains reliable under ordinary constraints, unusual cases, and changing environments.
Shortcut connections solve an optimization problem, not the broader reliability problem. A very deep network can still depend on spurious cues, fail under shift, or produce unequal errors. Its scale may make independent evaluation harder and environmental cost higher. Developers should pair architectural advances with transparent testing, robustness analysis, and documentation that communicates where the system should not be trusted. Technical success is incomplete when costs are hidden or errors fall disproportionately on people with the least power to contest them. Governance belongs in the design. Residual learning made extraordinary depth practical by preserving a simple path through the network. It also illustrates how a small structural idea can reshape an entire field. Its legacy is most useful as a standard for careful inquiry: build boldly, measure honestly, and keep the people affected by the system in view. Readers can apply that standard by asking which evidence supports the claim, which conditions bound it, and who remains accountable when a system behaves differently in practice.
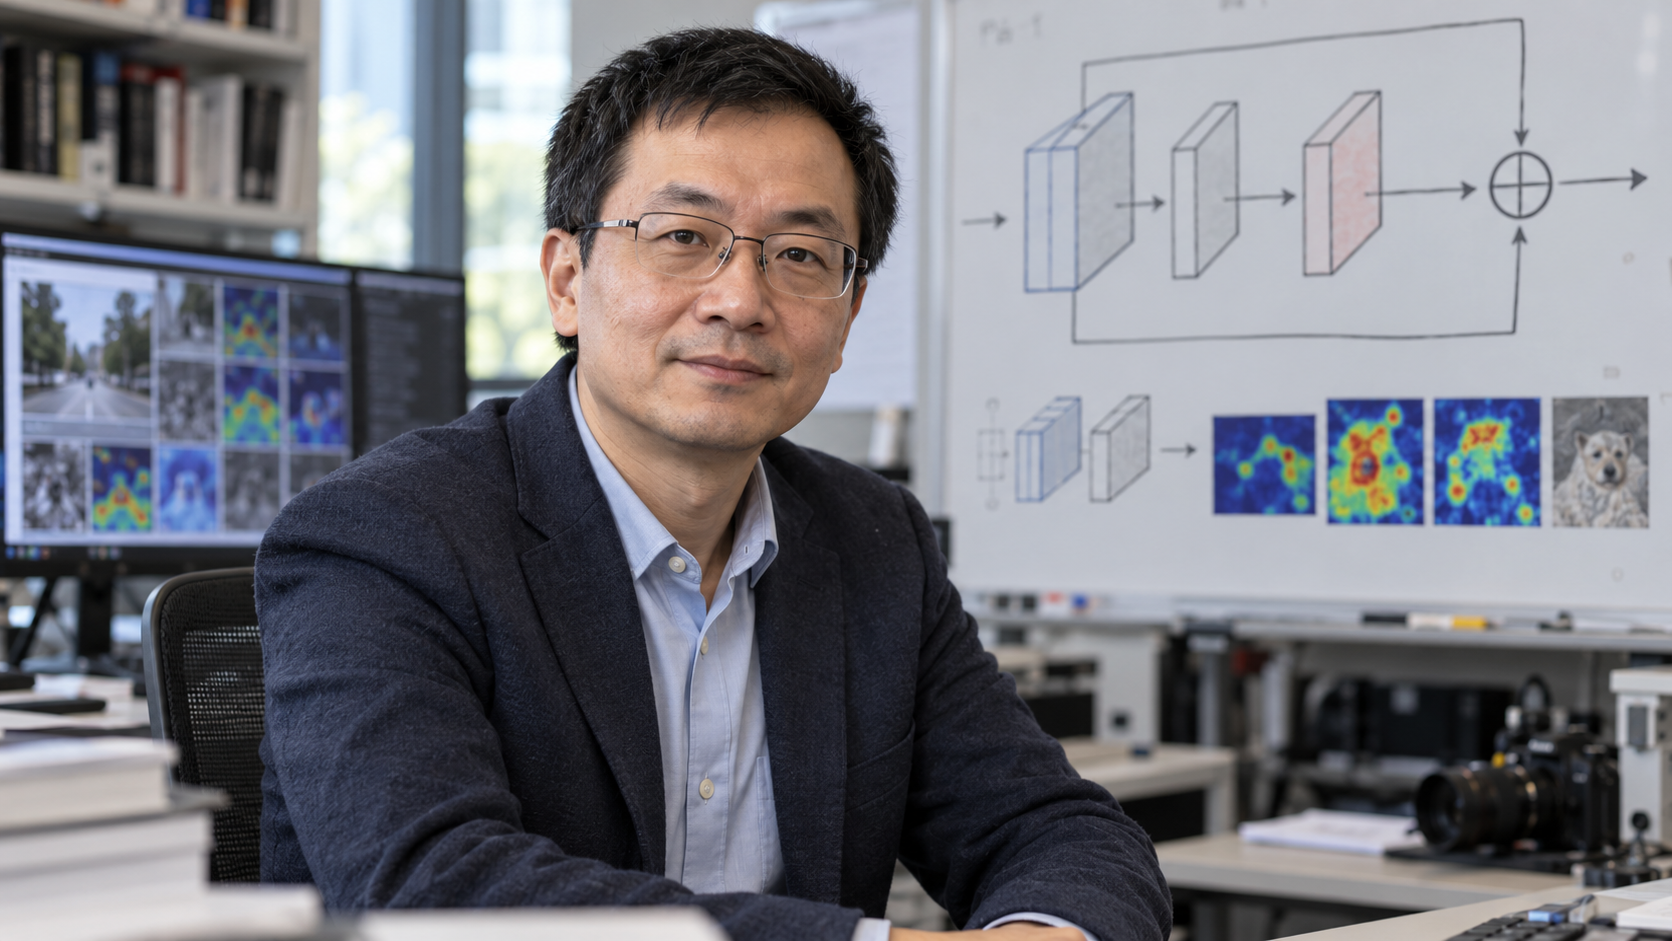
A shortcut carries the input around learned layers, and the block adds the learned residual back to that input.
This creates a direct path for information and gradients through a deep network.
Layers can focus on refining an existing representation rather than recreating it at every stage.
The reformulation reduced the degradation that had appeared when networks were made deeper.
More layers can increase capacity while leaving data bias, brittle features, and distribution shift unresolved.
Teams should justify complexity with relevant outcomes, robust tests, efficiency measures, and clear deployment limits.
Explore more "Quotes of The Day"
Continue exploring how writers, thinkers, artists, and advocates have described the choices that shape an everyday life.