

On This Day in AI: January 27, 2022
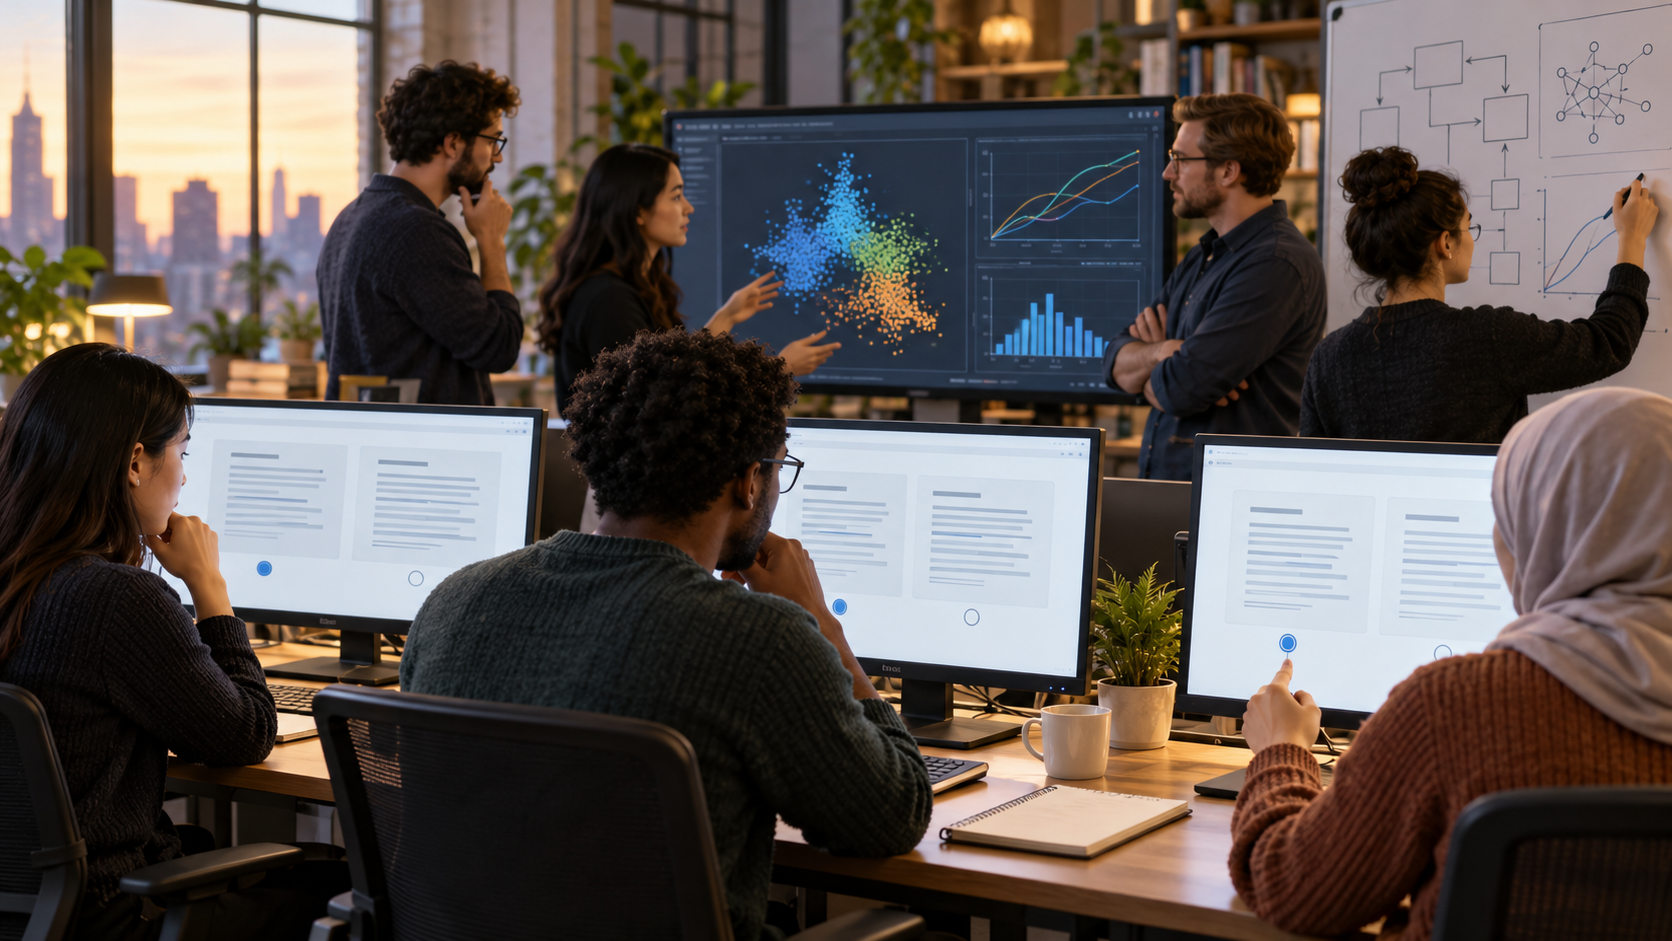
On January 27, 2022, OpenAI published research on InstructGPT, a family of language models trained to follow written instructions using human feedback. The San Francisco laboratory began with GPT-3, collected examples of people demonstrating desired answers, and asked human evaluators to rank alternative model responses. A reward model learned from those preferences, and reinforcement learning then adjusted the language model to produce answers that evaluators preferred. In tests, users often favored outputs from a 1.3-billion-parameter InstructGPT model over those from the much larger 175-billion-parameter GPT-3. The result showed that training objectives could matter as much as raw model size.
Earlier language models learned primarily by predicting the next piece of text from large internet datasets. That objective produced fluent writing, but it did not guarantee that a system would follow a user’s request, acknowledge uncertainty, or avoid harmful directions. OpenAI described this mismatch as an alignment problem: the model optimized prediction while users wanted helpful, honest, and safe assistance. Human feedback supplied a practical signal for those qualities. The method was imperfect because evaluators brought cultural assumptions, instructions could not cover every situation, and optimizing preferences could encourage answers that sounded convincing rather than being true.
The January 27 release did not solve alignment or eliminate toxicity, bias, fabrication, and misuse. OpenAI reported remaining failures and noted that the system sometimes followed dangerous instructions or generated facts it could not support. The work also depended on labor-intensive judgments from people whose working conditions and perspectives shaped the resulting model. Even with those limits, InstructGPT became a foundation for the conversational systems that followed. Its approach, commonly called reinforcement learning from human feedback, helped transform general text predictors into assistants that could respond to requests in a more cooperative format. The research influenced ChatGPT and prompted widespread adoption of preference tuning across the industry. Its lasting importance lies in changing the central development question from simply making a model larger to deciding whose instructions and values it should follow, how feedback should be collected, and how improved behavior should be tested.
The research also changed how model quality was measured. Traditional language-model benchmarks focused on prediction or narrow tasks, while instruction-following required comparisons of usefulness, safety, and adherence to a request. Those judgments were harder to standardize, yet they more closely resembled what users experienced. InstructGPT helped establish side-by-side human evaluation as a central development tool, alongside automated tests, and exposed the need to report who evaluated outputs and what instructions they received.
Evaluators first wrote examples of good answers and then ranked multiple model responses. A reward model learned patterns in those preferences.
Reinforcement learning used the reward signal to adjust the language model toward answers people judged more helpful and appropriate.
Users often preferred the smaller 1.3-billion-parameter InstructGPT over the 175-billion-parameter GPT-3 because it followed requests more reliably.
The comparison showed that a model's objective and post-training could improve usefulness even without increasing its underlying scale.
Human judgments vary across cultures and individuals, and preferred answers can be confident without being factual. Harmful behavior also remained possible.
The method nevertheless became central to conversational AI and made evaluator selection, labor, values, and testing core engineering questions.
Explore more of "On This Day ..."
Discover more events from the same date across news, politics, technology, sports, and other fields. Each link highlights significant moments that shaped history on different fronts.