

AI Benchmarking Explainer
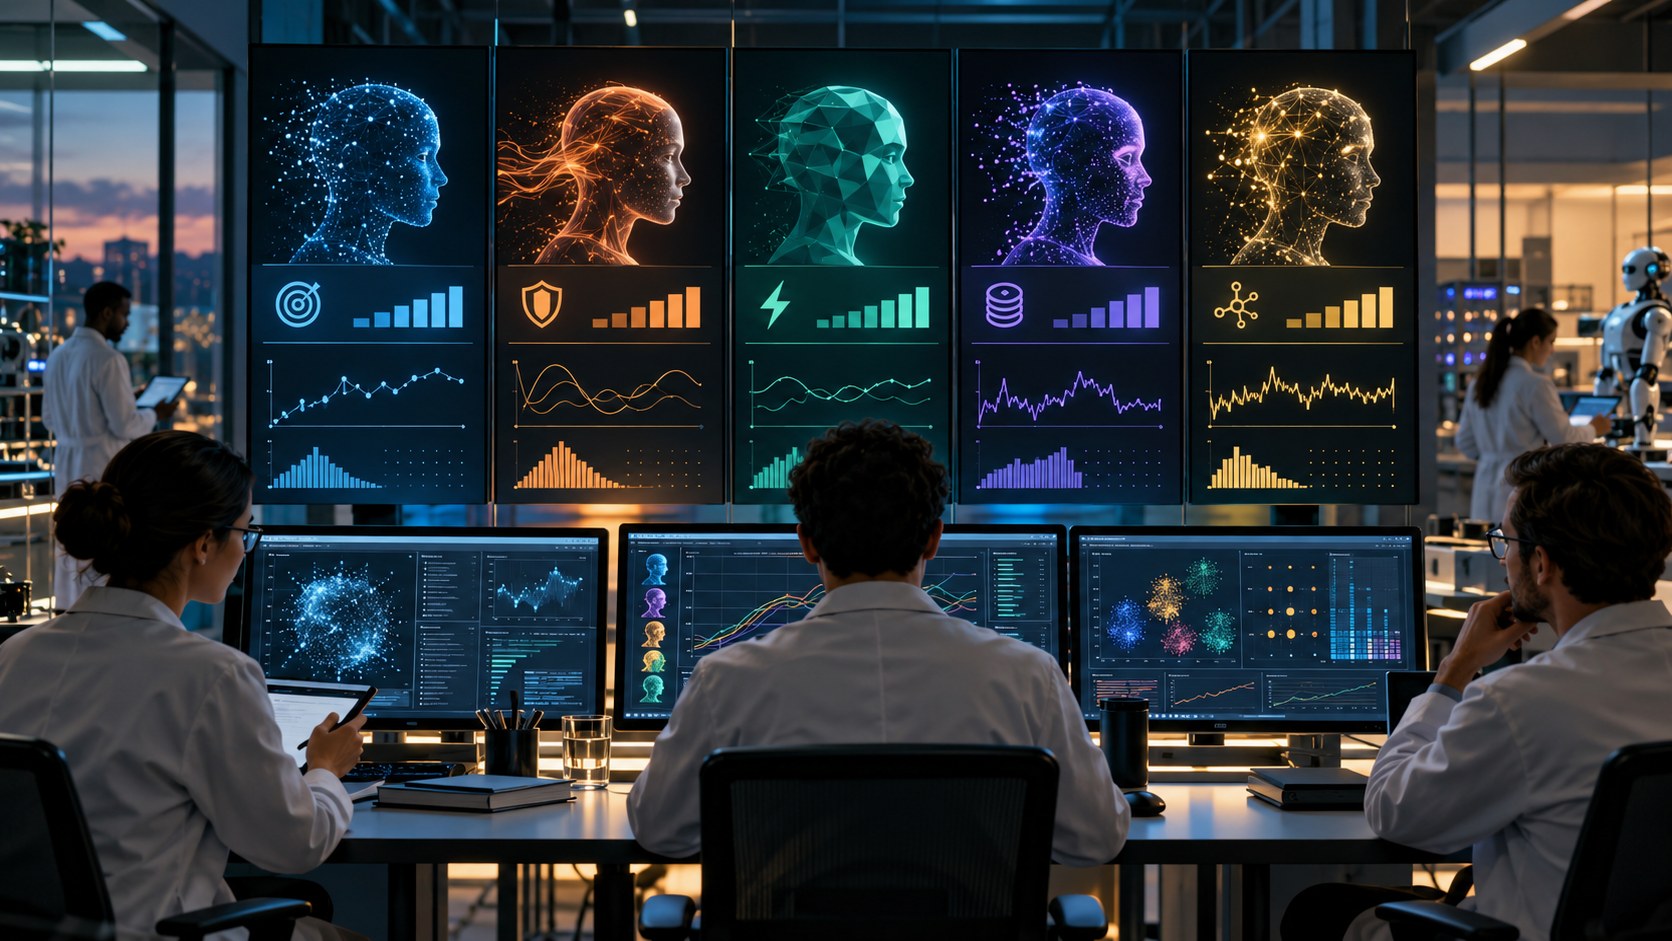
AI benchmarking evaluates a model or system on a defined set of tasks, data, procedures, and metrics. A benchmark may test accuracy, reasoning, coding, safety, fairness, robustness, latency, or cost. Shared benchmarks make comparisons easier because participants are measured under similar rules.
A sound benchmark documents its dataset, prompts, scoring method, model settings, and uncertainty. It separates test data from development data and controls for factors such as tool access or repeated sampling. Broader frameworks evaluate multiple scenarios and metrics rather than reducing quality to one number.
Benchmarks can reveal progress, regression, and tradeoffs, but they are proxies for real goals. A model may be tuned to a popular test, trained on contaminated examples, or strong on average while failing a critical subgroup. Small changes to prompting or grading can also change the result.
Organizations should combine public benchmarks with task-specific evaluations, expert review, red teaming, and monitoring after deployment. Results should include limitations, confidence intervals, operating conditions, and costs. A leaderboard rank is a clue—not a complete judgment about whether a system is fit for use.
AI benchmarking measures model performance on defined tasks and metrics so systems can be compared under stated conditions.
Key terms include benchmark, dataset, task, metric, leaderboard, contamination, validity, robustness, red team and confidence interval.
<a href="https://crfm.stanford.edu/helm/" target="_blank" rel="noopener noreferrer">Stanford CRFM: Holistic Evaluation of Language Models</a> and <a href="https://airc.nist.gov/metrology/" target="_blank" rel="noopener noreferrer">NIST AI Metrology Center</a> provide the primary references for this explainer.
A benchmark pairs tasks with a scoring rule and a repeatable procedure. Useful reports state prompts, tools, model versions, sampling settings, and uncertainty.
Different metrics capture different goals, so speed, cost, safety, and subgroup performance may need separate measurement.
Contamination, overfitting, narrow task selection, unreliable graders, and averaging can produce an impressive but misleading number.
Use domain evaluations and real workflows to confirm whether benchmark improvements translate into better outcomes.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.