

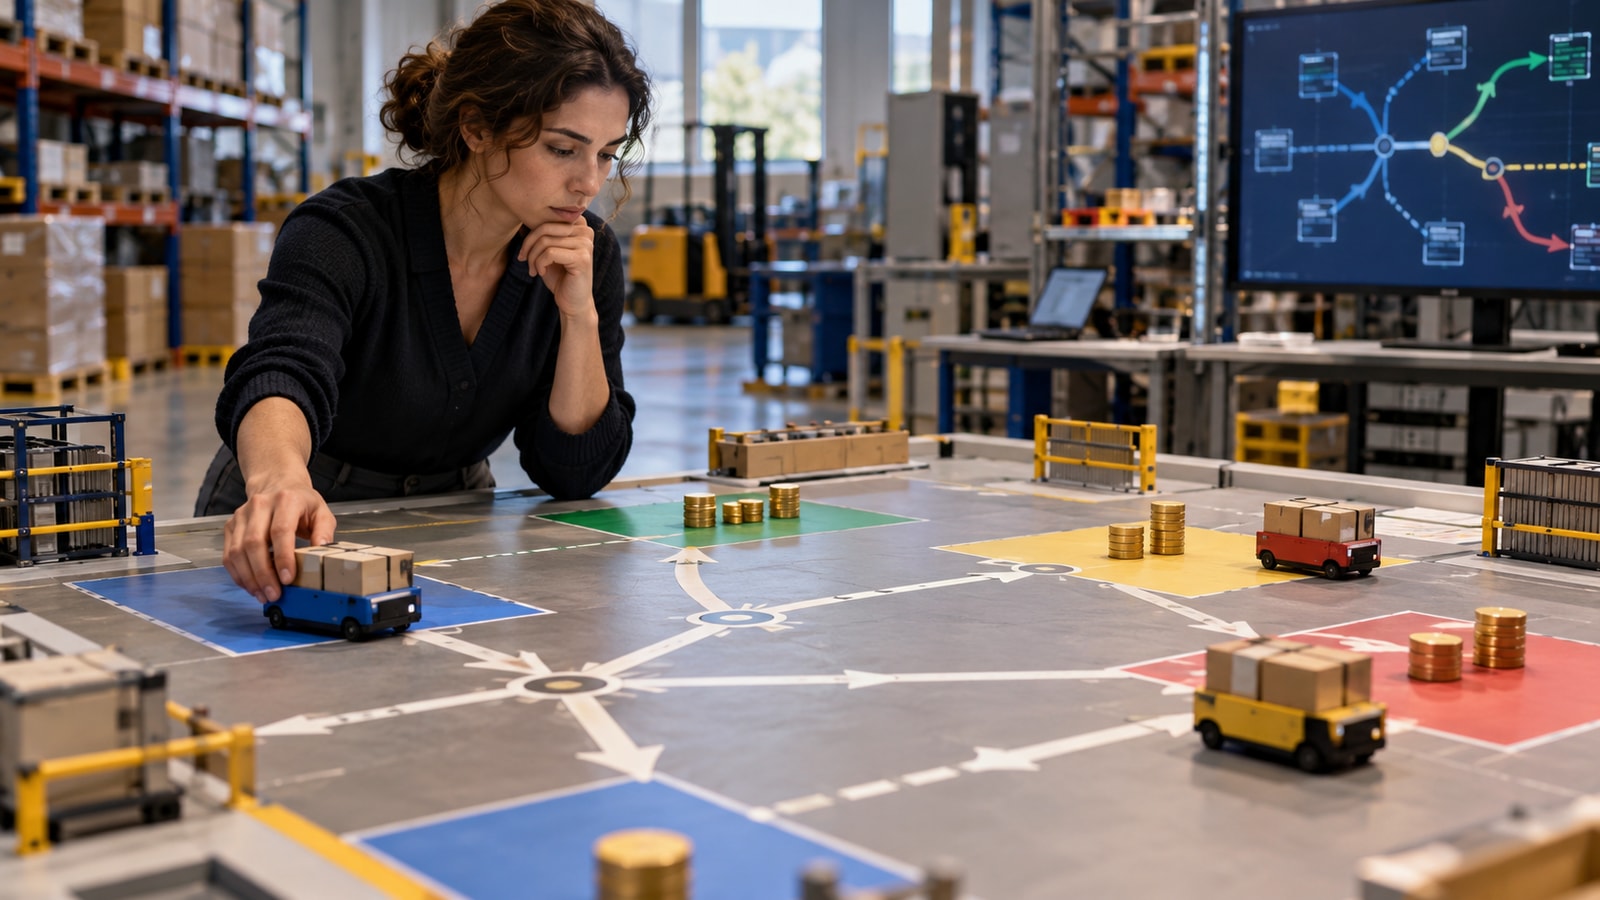
Markov Decision Process Explainer
A Markov decision process, or MDP, is a mathematical model for decisions whose outcomes unfold over time. It defines states, available actions, transition probabilities, rewards, and usually a discount factor that controls the weight of future rewards.
The Markov property says that the current state contains the information needed to predict the next-state distribution given an action. A policy maps states to actions or action probabilities, and a value function summarizes expected future return.
MDPs provide the foundation for many reinforcement-learning and planning methods. When transition and reward models are known, dynamic programming can compute useful policies. When they are unknown, an agent may estimate them or learn directly through interaction.
The model is only as good as its states, actions, rewards, and assumptions. An incomplete state can hide important history, and a poorly designed reward can encourage undesirable behavior even when the optimization succeeds.
A Markov decision process models sequential choices with states, actions, transition probabilities, rewards, and a discount factor.
Key terms include state, action, transition probability, reward, discount factor, Markov property, policy, value function and return.
States describe decision situations, actions change them probabilistically, and rewards score the resulting transitions.
A policy links those pieces by specifying what the agent should do in each state.
If the state omits relevant history, the Markov assumption may fail and the same visible state can require different actions.
Reward design also matters because the agent optimizes the formal signal, not the designer’s unstated intention.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.