

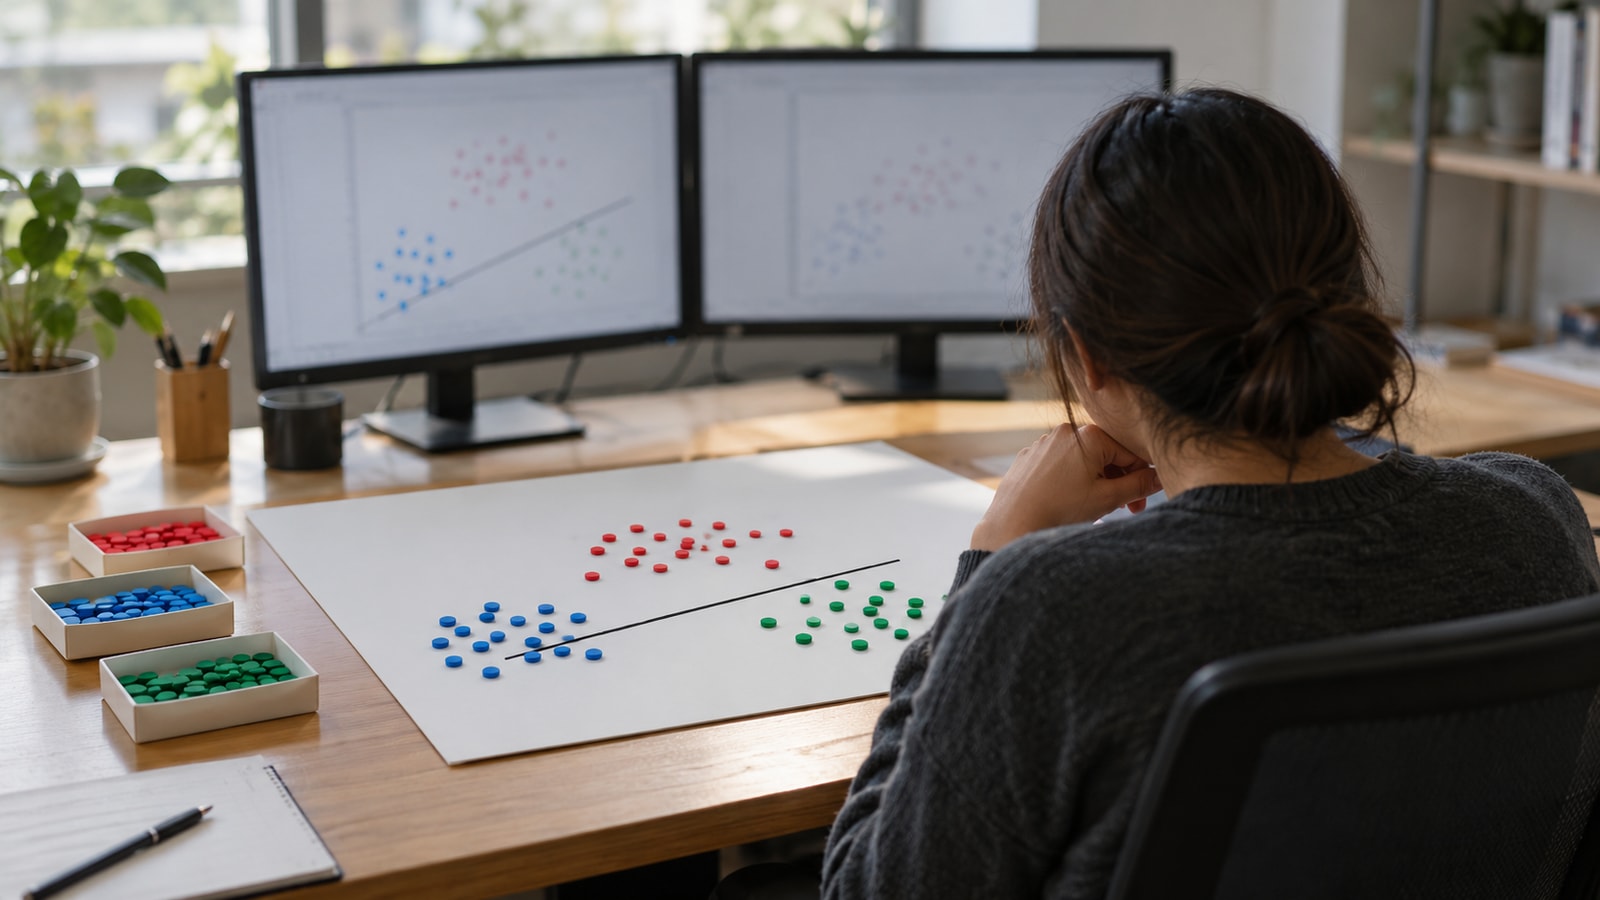
Underfitting in Machine Learning Explainer
Underfitting occurs when a machine-learning model has not learned enough of the relationship between its inputs and target. Its assumptions may be too simple, its useful features too weak, or its training too limited for the task.
An underfit model commonly performs poorly on both training data and new validation data. The exact pattern depends on the metric, but the central clue is that even examples available during training are not modeled well.
Possible remedies include using a more expressive model, adding informative features, reducing excessive regularization, or training longer. Each change should be evaluated on held-out data because extra complexity can eventually produce overfitting instead.
The goal is not the most complicated model. It is enough capacity to represent the durable signal while still generalizing beyond the training set. Learning curves and error analysis help teams distinguish underfitting from noisy labels or an unsuitable metric.
Underfitting happens when a model is too limited or insufficiently trained to capture important patterns in its data.
Key terms include model capacity, training error, validation error, bias, variance, regularization, learning curve and generalization.
Training performance remains weak because the model cannot express or has not learned the main pattern.
Validation performance is also weak, so collecting more similar data alone may not solve the limitation.
More useful features, greater model capacity, lighter regularization, or additional training may help.
Every adjustment should be checked against held-out data so a correction does not swing into overfitting.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.