

Vision-Language Model Explainer
A vision-language model processes visual information and natural language within one learned system. It may align an image with a caption, answer a question about a picture, retrieve matching media, or generate a description.
Some models learn separate image and text encoders whose representations are pulled together for matching pairs. Others combine visual tokens and word tokens through cross-attention or feed them into a generative language model.
Training can use large collections of image-text pairs, followed by task-specific tuning or instruction training. Applications include search, accessibility, content organization, visual assistants, document understanding, and robot interfaces.
Web-scale pairs contain noise, stereotypes, copyrighted material, and missing context. A model may produce confident language that is not grounded in the image, or overlook fine visual details. Evaluation needs image-specific evidence, diverse data, safety testing, and human review.
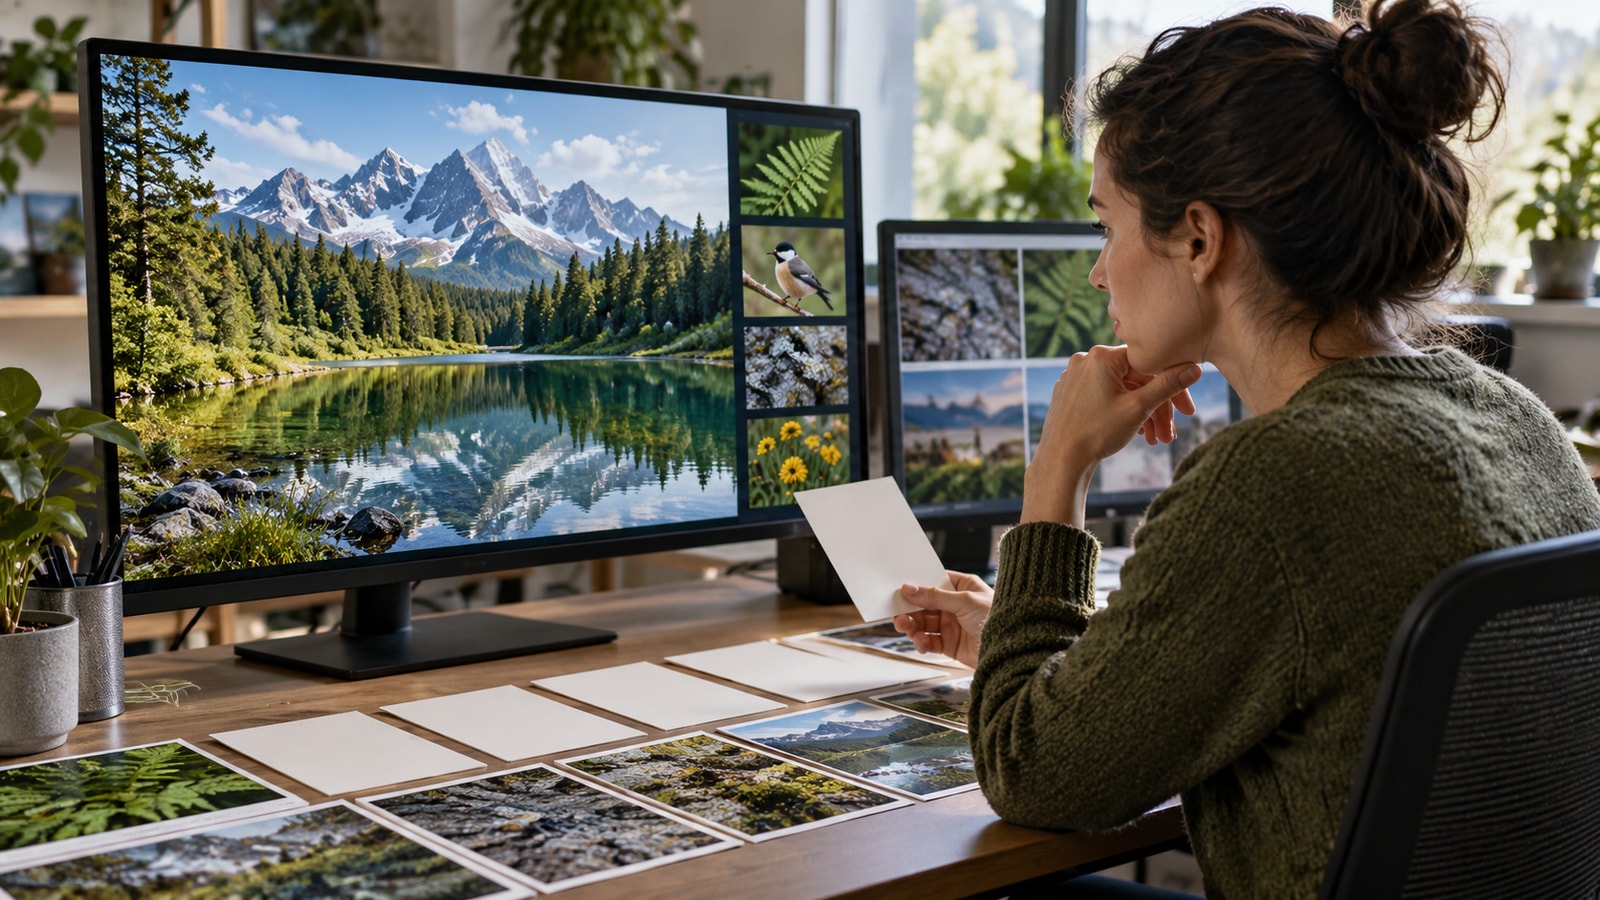
A vision-language model learns relationships between images and natural language so it can compare, describe, or reason across both.
Key terms include vision-language model, image encoder, text encoder, joint embedding, visual token, cross-attention, grounding and image-text pair.
Alignment training places matching visual and textual concepts close together.
Multimodal attention can let language generation refer to visual features.
A model can rely on common associations instead of details present in the image.
Grounding tests should require accurate references to visible objects, relations, and text.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.