

Rotary Positional Embedding Explainer
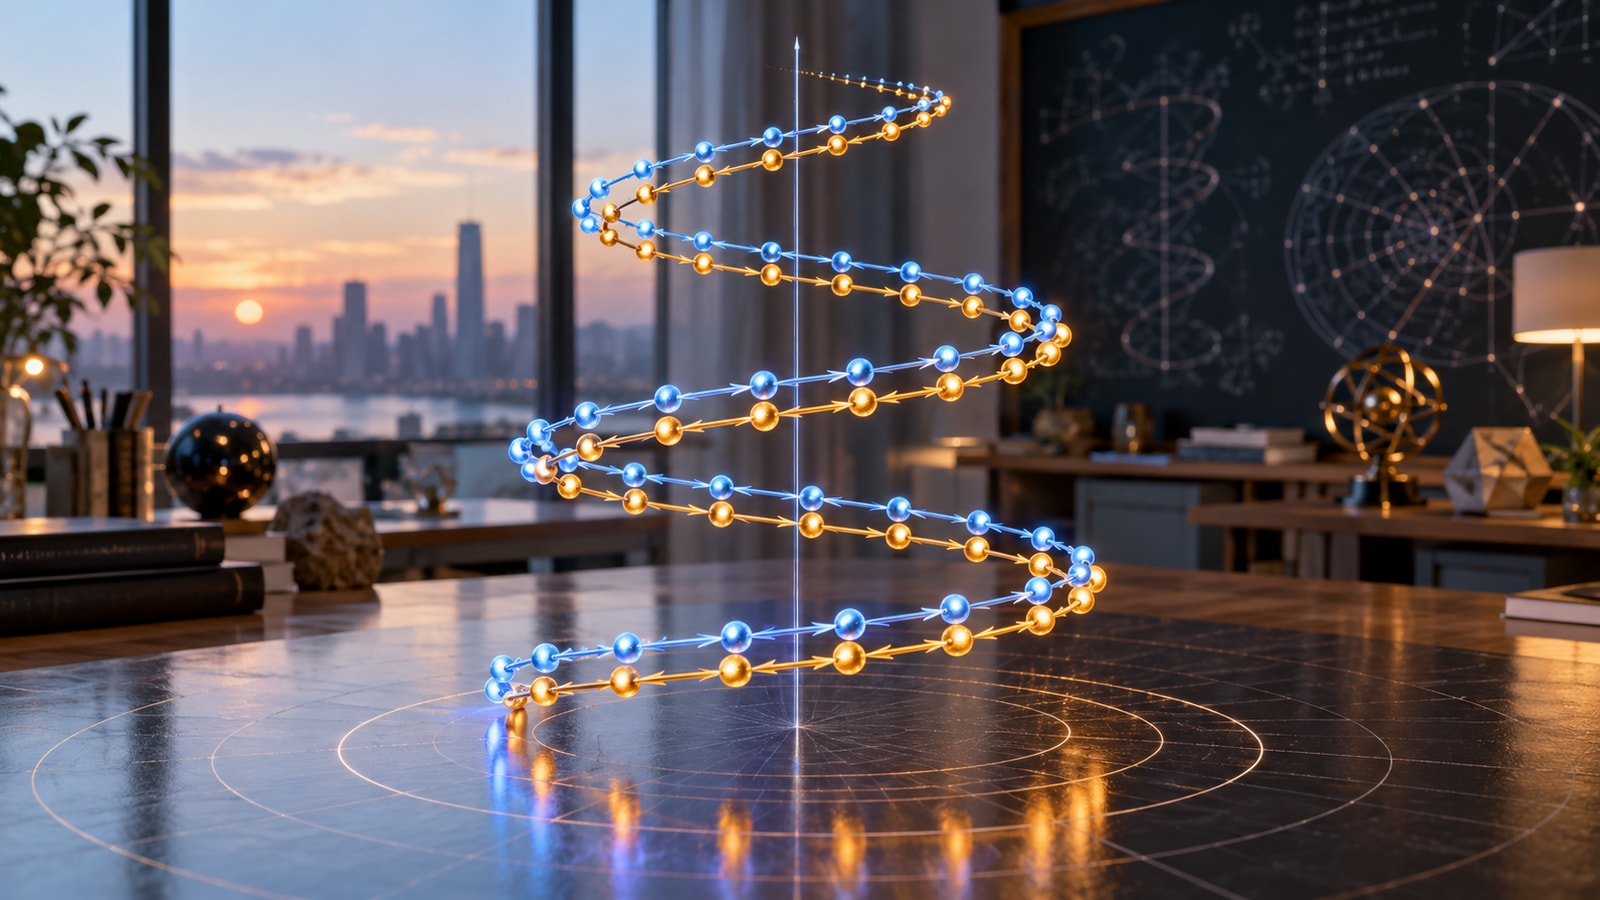
Rotary positional embedding, or RoPE, injects token position into transformer attention by rotating pairs of query and key features. Each position uses a different angle, with several rotation frequencies across the feature dimensions.
When rotated queries and keys are compared, their dot product depends on the relative distance between positions. This lets the model represent order without adding a standalone position vector to the token representation.
RoPE is used in many language models because it works naturally with attention and supports efficient implementation. It can be modified by rescaling frequencies or positions to extend the usable context window.
A model trained on short sequences does not automatically behave well at much longer lengths. Scaling methods can trade local precision for range, and results depend on retraining or fine-tuning. Long-context tests should require actual use of distant evidence.
Rotary positional embedding rotates query and key features by position so their dot product contains relative-distance information.
Key terms include RoPE, position, rotation, query, key, relative distance, frequency, attention, context window and extrapolation.
Feature pairs rotate by angles determined by token position.
Comparing two rotated vectors exposes their relative offset to attention.
Changing position frequencies may extend the range but can alter resolution at shorter distances.
Models must be tested on tasks that truly depend on far-apart information.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.