

Speculative Decoding Explainer
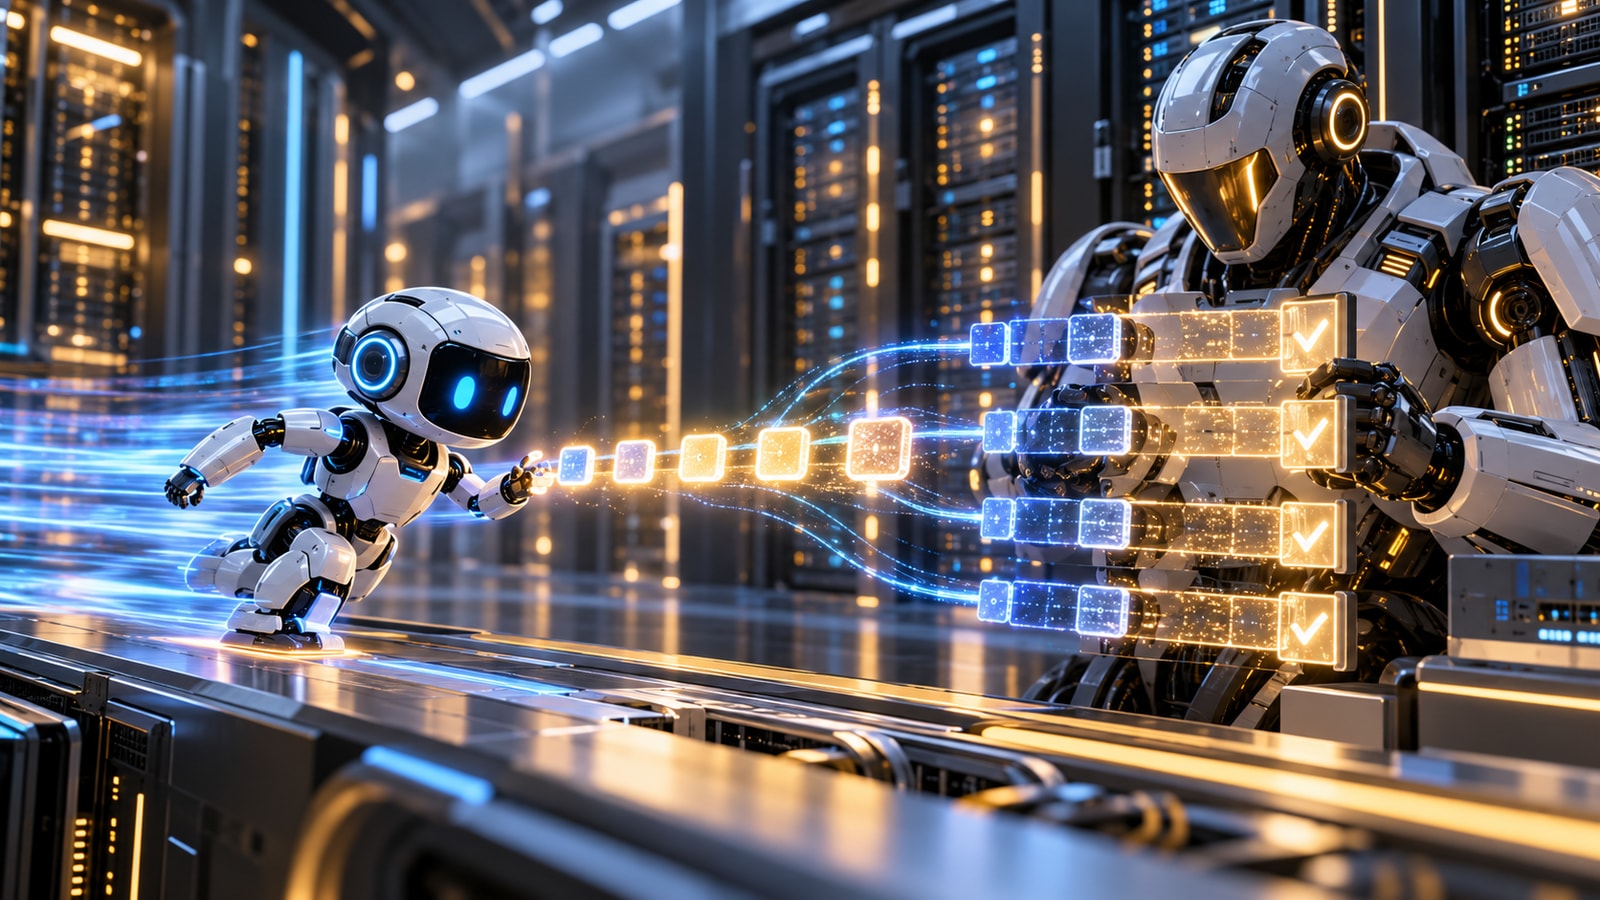
Speculative decoding accelerates language-model generation by pairing a fast draft model with a larger target model. The draft proposes several future tokens, and the target evaluates those positions together instead of producing them one at a time.
A verification rule accepts a prefix of proposals and corrects rejected tokens so the final sampling distribution matches ordinary target-model decoding. The method changes the computation schedule rather than accepting lower-quality output.
Speedup is greatest when the draft is much cheaper and its proposals agree frequently with the target. Variants use smaller models, early-exit heads, retrieved continuations, or multiple candidate branches.
Poor agreement creates wasted drafting and verification. Large batches, short outputs, communication, and target-model efficiency can reduce benefits. Evaluation should measure acceptance rate, end-to-end latency, throughput, memory, and exact output equivalence.
Speculative decoding uses a faster draft model to propose several tokens that a larger model verifies in parallel without changing the output distribution.
Key terms include speculative decoding, draft model, target model, proposal, verification, acceptance rate, sampling distribution and latency.
A lightweight model proposes a short continuation ahead of the target.
The target checks multiple positions in one pass and accepts a valid prefix.
Rejected proposals consume work without advancing generation very far.
Draft cost, target efficiency, batch size, and output length shape real gains.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.