

Tensor Parallelism Explainer
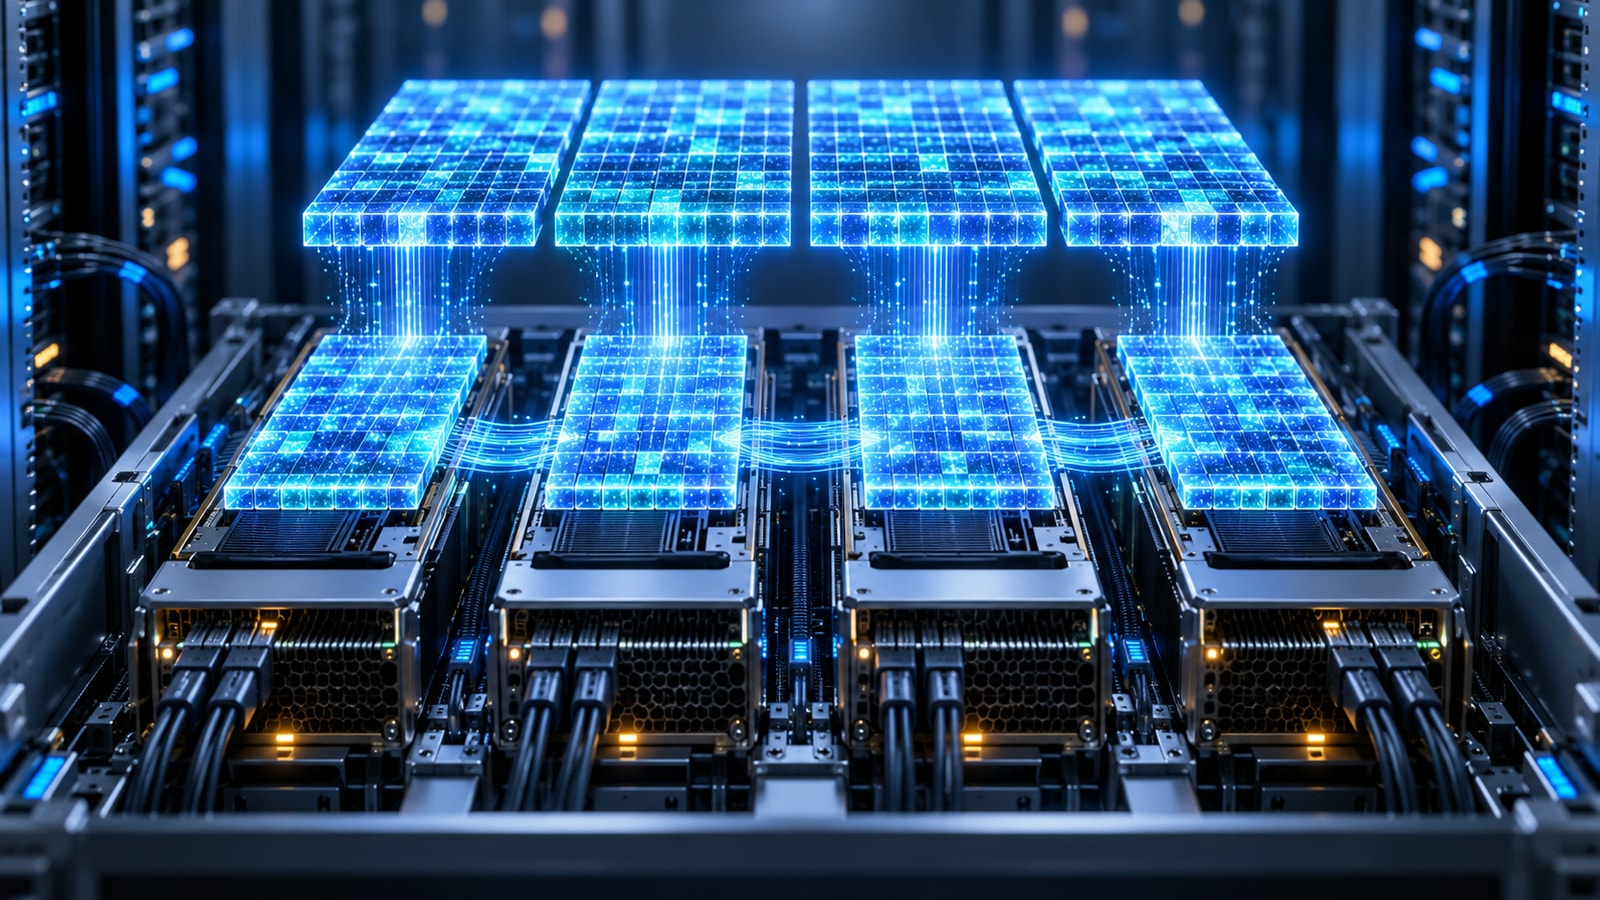
Tensor parallelism divides the tensors and computation inside a neural-network layer across multiple devices. For example, different GPUs can hold different slices of a large weight matrix and compute parts of the same matrix multiplication.
The partial results must be combined through collective communication such as all-reduce or all-gather. Layer designs can arrange row and column partitions to limit how often those transfers occur.
Tensor parallelism allows very wide models to exceed one device’s memory and can reduce computation time when devices have fast links. It is used in both training and inference, often alongside data or pipeline parallelism.
Frequent communication can dominate when links are slow or the shard count is too high. Efficiency depends on tensor shapes, batch size, interconnect topology, kernels, and load balance. Scaling should be measured end to end.
Tensor parallelism splits individual neural-network operations across devices so models or layers too large for one accelerator can run together.
Key terms include tensor parallelism, shard, matrix multiplication, GPU, all-reduce, all-gather, interconnect, model parallelism and topology.
Each device computes a slice of the same tensor operation.
Collective communication combines partial outputs before the model continues.
More shards reduce local work while increasing synchronization and data movement.
Fast interconnects and hardware-aware partitioning are essential for good scaling.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.