

Retrieval Routing Explainer
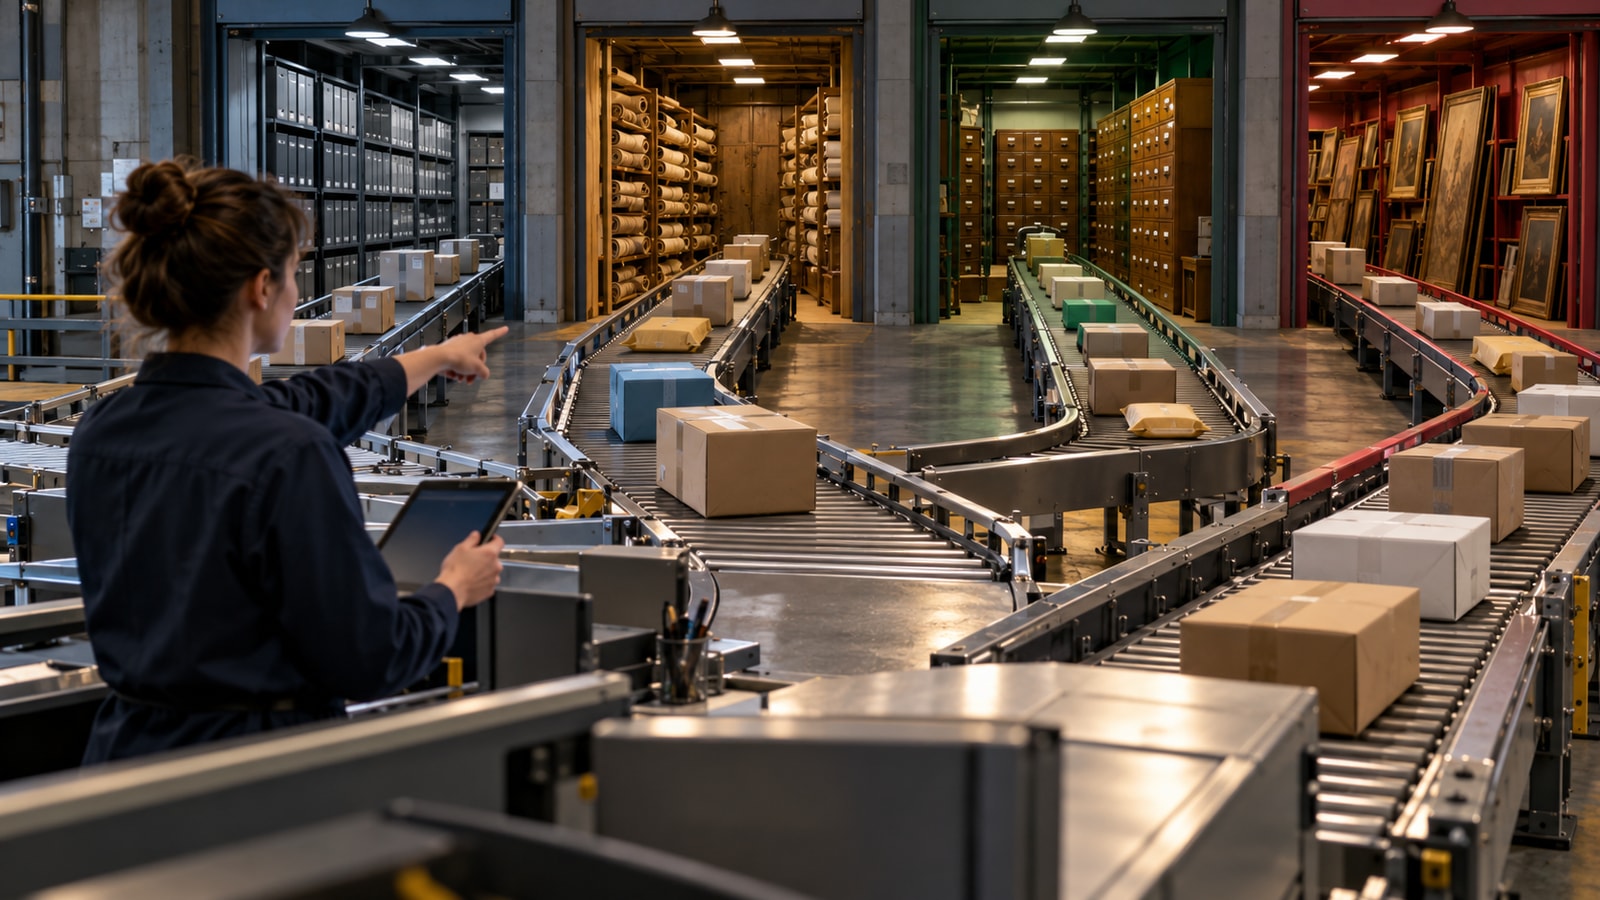
Retrieval routing is the process of deciding where and how a query should be searched. A router can choose among document indexes, databases, web search, APIs, or specialized retrievers before generation begins.
The decision may use rules, metadata, a classifier, embeddings, or a language model. Some systems also choose between lexical, dense, hybrid, or no retrieval based on the question and the available collections.
Good routing reduces irrelevant results, latency, and cost while respecting access boundaries. It is especially valuable when one assistant covers many domains whose information lives in separate systems with different update schedules.
Routing errors can silently hide the best evidence or expose a source that should not be used. Evaluation should test ambiguous queries, permissions, empty results, fallbacks, and whether the chosen route actually improves supported answers.
Retrieval routing directs a query to the search source or retrieval method most likely to contain useful, permitted evidence.
Key terms include router, query, retriever, index, database, classifier, metadata, fallback and access control.
A router maps the query to one or more collections and retrieval methods.
Rules and learned signals can consider topic, freshness, permissions, and expected answer type.
Relevant evidence remains invisible when the router selects the wrong collection.
Fallbacks and route-level evaluation are needed for ambiguous or changing requests.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.