

Model Inversion Attack Explainer
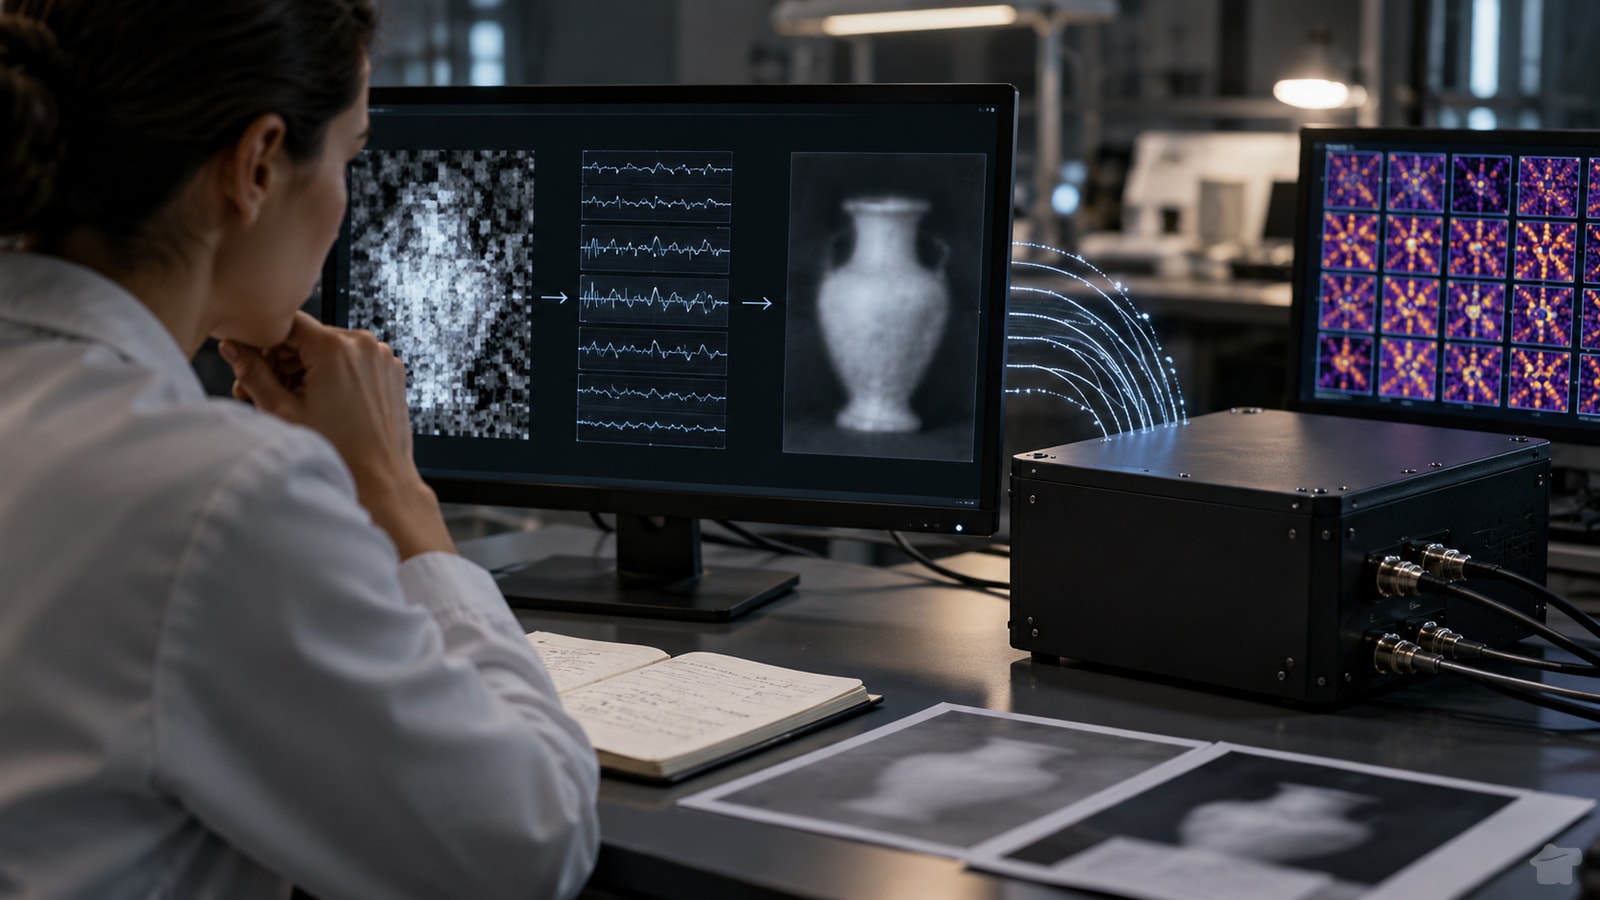
A model inversion attack tries to reconstruct information about inputs or training data from a model’s outputs and behavior. The attacker searches for an input that strongly matches a target prediction, class, or internal representation.
For an image classifier, the result might resemble features the model associates with a person or category. In other settings, inversion may estimate attributes, recover portions of an input, or reveal a representative pattern.
The reconstruction is not automatically an exact copy of a training record. It can be a model-derived prototype, and its fidelity depends on the attacker’s access, auxiliary information, model architecture, and degree of overfitting.
Defenses include minimizing exposed scores, restricting sensitive queries, testing inversion risk, controlling model access, and using privacy-preserving training. Teams should avoid presenting reconstructed outputs as certain evidence about an individual.
A model inversion attack uses access to an AI model to reconstruct features or representative information associated with its training data.
Key terms include inversion, reconstruction, target class, confidence score, representation, auxiliary information, prototype, privacy audit and access.
A target prediction or representation becomes the objective for reconstruction.
Optimization searches for an input that makes the model produce that target.
The output can reflect shared class features rather than one exact record.
Claims about recovered identities require careful evidence and uncertainty reporting.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.