

AI Observability Explainer
AI observability is the ability to investigate what a deployed AI system is doing and why it may be changing. It combines operational signals with model, data, input, output, and user-context information.
Useful signals can include latency, errors, resource use, model version, prompt or feature characteristics, retrieval results, tool calls, output quality, safety events, and human feedback. Privacy limits should shape what is collected and retained.
Monitoring asks whether known conditions crossed thresholds. Observability supports open-ended investigation when the failure is not already defined. Engineers correlate signals across the pipeline to locate a bottleneck, drift, dependency failure, or unexpected behavior.
More telemetry does not automatically create understanding. Teams need stable identifiers, time alignment, meaningful baselines, access controls, and investigation workflows. They should collect the minimum data needed and avoid turning sensitive content into an unmanaged log archive.
AI observability is the ability to understand a deployed AI system's internal and external behavior from logs, traces, metrics, inputs, outputs, and context.
Key terms include observability, metric, log, trace, telemetry, baseline, correlation, model version and investigation.
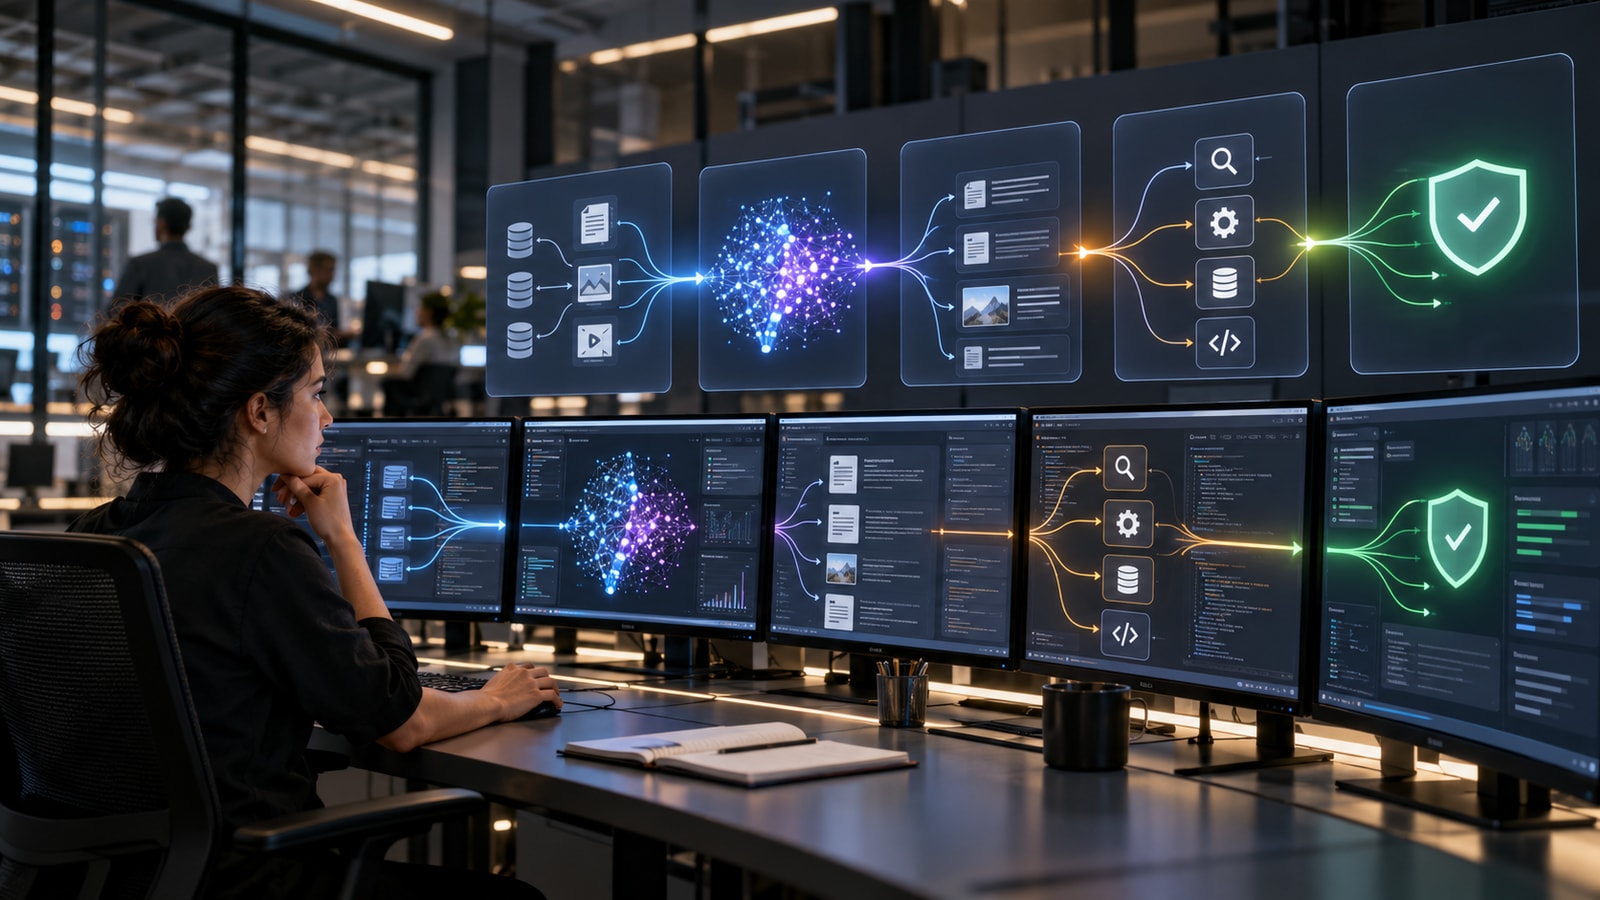
A request may pass through data services, models, retrieval, tools, and policy checks.
Shared identifiers help investigators follow that path without guessing which event belongs where.
Prompts, outputs, and user context can contain sensitive or regulated information.
Collection, retention, access, and redaction rules should be designed with the observability system.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.