

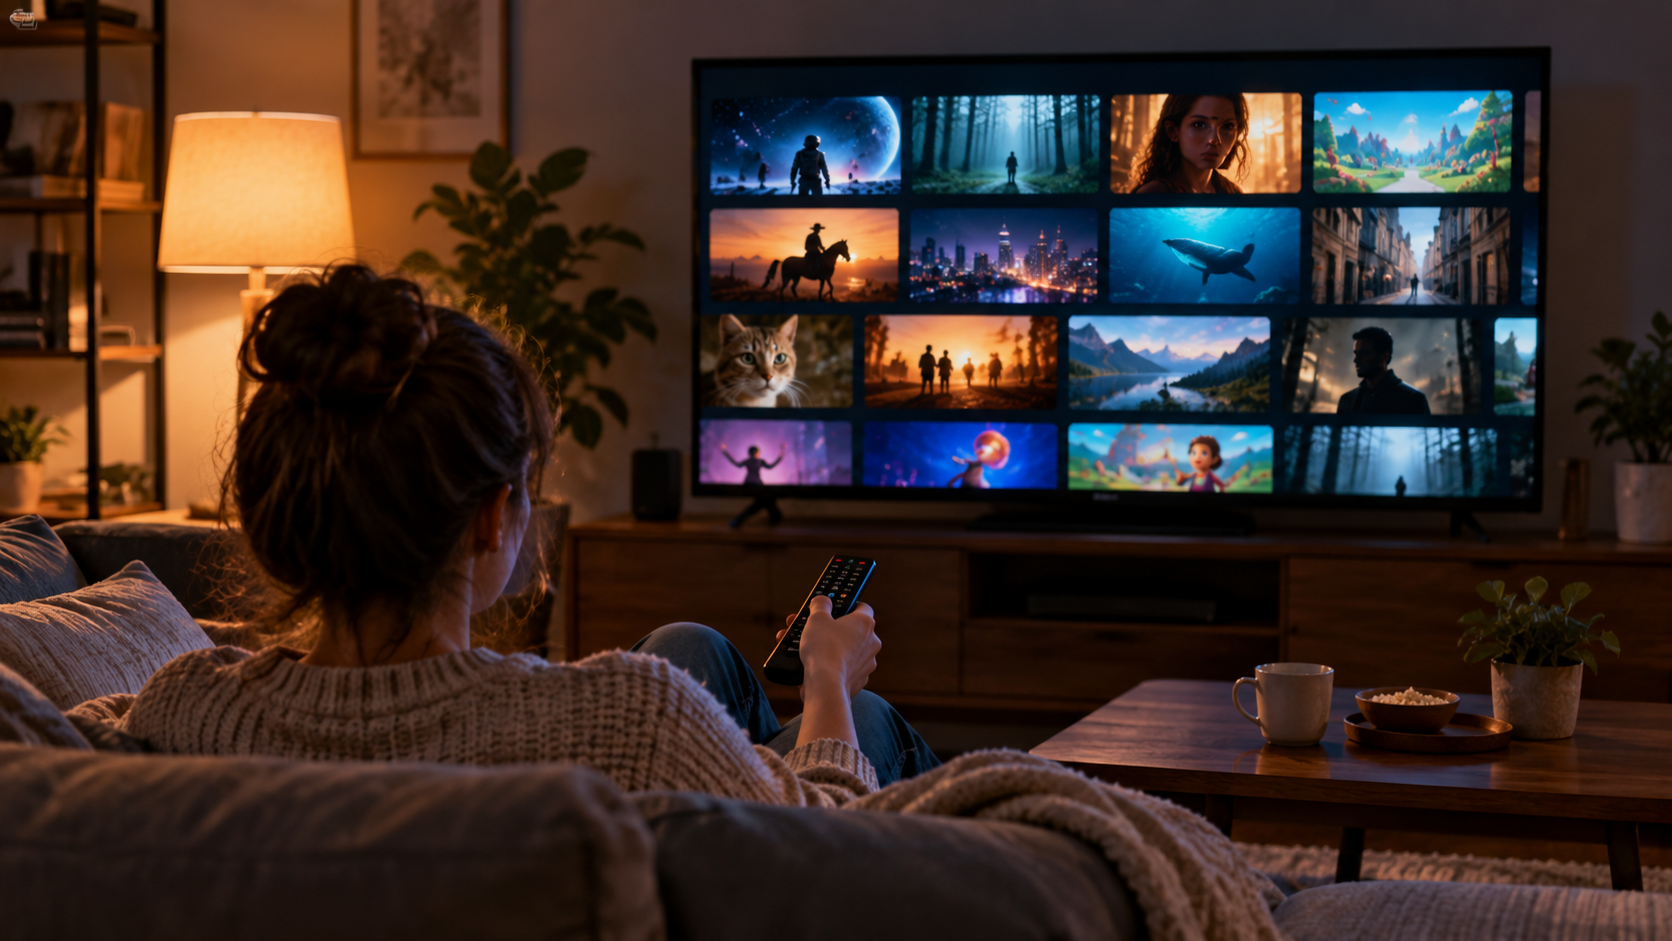
Streaming Recommendations Explainer
A streaming recommendation system estimates which items in a catalog may be useful or enjoyable for a particular viewer, then decides how to present them. It is not one master list of objectively best titles. Systems can rank individual programs, select themed rows, order those rows, choose artwork, and personalize search results. The visible page is therefore the output of several decisions made under limits such as catalog availability, language, device, freshness, and business rules.
Inputs may include what a profile starts, finishes, abandons, searches for, saves, or explicitly rates, along with information about titles such as genre, participants, release year, and language. Patterns from people with similar behavior can also help when an individual has little history. Recent activity may receive more weight than old activity. Demographic attributes are not required for personalization, and an official description of one service should not be assumed to describe every platform.
A typical system first retrieves a manageable set of candidates from a much larger catalog, then scores or ranks them for a context. Different models can specialize in familiar favorites, new releases, similar titles, unfinished viewing, or diversity. Page-generation logic must balance relevance with variety so a screen does not repeat the same idea. The service may also decide how much stability to preserve, because a homepage that changes completely at every visit can be hard to navigate.
Feedback creates a loop. Recommendations influence what a viewer notices; those choices then become new data for later recommendations. This makes interpretation difficult: a highly watched title may have received prominent placement, not simply reflected prior demand. New profiles face a cold-start problem and may begin with selected preferences, popularity, or a broad mix. Households that share one profile can produce noisier signals because several tastes become entangled. Recommendation is prediction, not certainty, and its goal may be engagement, discovery, satisfaction, or a combination defined by the service. Users can often improve results by separating profiles, rating titles, removing unwanted history where tools allow, and using search when the ranked page is too narrow. The most helpful mental model is a continuously updated ordering system, not a gate that determines what exists. Catalog rights and regional availability still set the outer boundary. A practical way to read or discuss Streaming Recommendations is to begin with the basic definition and then identify the choices made in a particular example. Recommendation systems rank available items for a context; they do not calculate one universal measure of artistic quality. Next, ask who sets the relevant rules, who performs the work, and which results follow from creative judgment, law, contracts, technology, budget, or production limits. Similar-looking examples can operate differently because their audience, market, format, timing, and agreements are different. Diversity and stability matter because perfectly similar suggestions can feel repetitive and constantly changing pages can feel disorienting. It also helps to distinguish a formal industry category from an informal critical label or one organization's current practice. That separation keeps a memorable anecdote from becoming a false universal rule. Dates and territories matter: tools, distribution systems, audience behavior, and standard agreements change, while older examples can preserve assumptions that no longer apply everywhere. When a claim sounds absolute, compare it with a second kind of source and look for the conditions under which the claim is true. Then trace the process from the visible result back through the less visible decisions, handoffs, and quality checks that produced it. Profiles, ratings, history controls, and direct search give users partial influence, while rights and regional catalog limits remain outside the model. Finally, compare the example with a contrasting case and note which part of the definition still holds. This method keeps the explanation grounded, highlights the people and systems behind the outcome, and leaves room for reasonable disagreement about hybrid or borderline cases.
Recommendation systems rank available items for a context; they do not calculate one universal measure of artistic quality.
Viewing history, completion, explicit ratings, searches, language, device, time, and title attributes can serve as signals, depending on the service.
Candidate retrieval narrows a large catalog before ranking models and page logic decide which titles and rows appear first.
Diversity and stability matter because perfectly similar suggestions can feel repetitive and constantly changing pages can feel disorienting.
Placement creates feedback: prominent recommendations attract attention, and the resulting behavior may reinforce later ranking decisions.
Profiles, ratings, history controls, and direct search give users partial influence, while rights and regional catalog limits remain outside the model.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.