

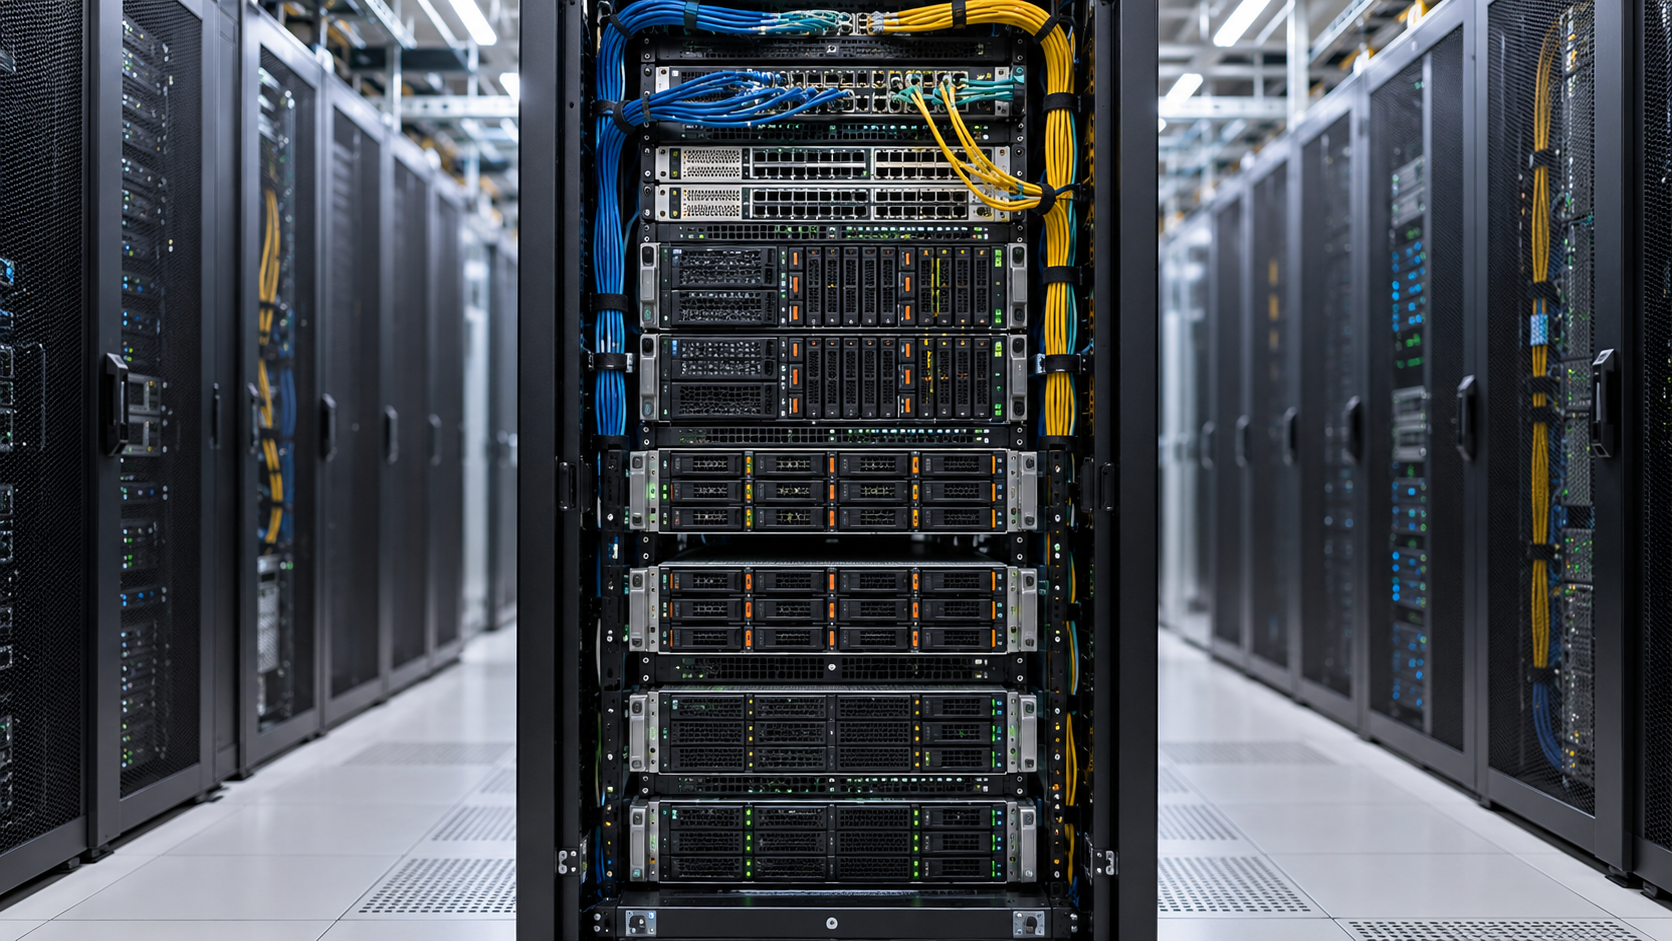
Distributed Online Storage Explainer
Distributed online storage is the infrastructure that lets applications read and update operational data across many machines, databases, and geographic regions. “Online” means the data is needed in the path of live user requests, such as signing in or loading a conversation. “Distributed” means no single computer holds or serves everything.
A storage platform typically gives applications a controlled interface, then handles routing, authorization, caching, data placement, rate limits, and failover. Replicas can improve availability and place information closer to users, but they also create coordination problems. Engineers must decide how quickly copies become consistent and what happens when a region or dependency fails.
Scale makes tail latency especially important. One page load may trigger many database calls, so the slowest call can determine what a user feels. Platforms therefore limit unpredictable queries, isolate heavy workloads, cache common reads, monitor downstream health, and use techniques such as hedging or load balancing.
OpenAI recently described Habitat, an online storage platform handling more than 70 million requests per second and more than 500 petabytes of data for products used by over one billion people weekly. The example shows why storage at scale is a service-design problem as much as a database problem.
Distributed online storage keeps live application data available across multiple resources and regions. Key terms include replication, consistency, partitioning, caching, routing, failover, and tail latency.
The objective is predictable access under normal load and partial failure, not merely maximum capacity.
Applications send constrained requests to a storage layer. That layer authenticates them, finds the correct data, chooses a healthy backend, and returns a result while recording latency and errors.
Replication and caching can improve speed and resilience, but engineers must manage stale data, hotspots, capacity, and regional rules.
Flexible queries are convenient but can create unpredictable work. Constrained APIs can make isolation and capacity planning easier at very large scale.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.