

RAID Rebuild Explainer
A RAID rebuild restores redundancy after a member drive fails or is replaced. RAID combines multiple drives into one logical storage system using mirroring, striping, parity, or a mixture of those techniques. When a drive becomes unavailable, a redundant layout may continue serving reads and writes in a degraded state. A rebuild reads information from the surviving members, reconstructs what belonged on the missing device, and writes the result to a spare or replacement. The exact calculation depends on the RAID level and the position of each stripe.
In a mirrored array, rebuilding is conceptually straightforward: copy every required block from a surviving mirror to the new member. In a single-parity layout, each stripe contains data blocks and parity calculated from them. If one block is missing, the controller can combine the remaining blocks and parity, commonly using exclusive-or operations, to recover it. Dual-parity layouts retain enough independent information to reconstruct two missing blocks under supported failure combinations. More parity improves fault tolerance but adds capacity and write overhead.
The array needs a map of which regions must be rebuilt. Some systems reconstruct the entire address range because they cannot assume which blocks contain meaningful data. Others use bitmaps, metadata, or cooperation with a file system to limit work. Writes that occur during the rebuild must be coordinated so the replacement does not receive stale content. The controller may reconstruct a stripe from current surviving data, write new application data through the normal redundancy path, and record progress so an interruption can resume safely.
Rebuilding is stressful because all surviving drives may be read extensively while normal workload continues. Performance falls, temperatures and queues may rise, and a latent unreadable sector can appear at the worst time. The process is limited by drive speed, interface bandwidth, controller resources, workload priority, and total capacity. Large modern drives can take many hours, especially when the system deliberately throttles recovery to preserve application service. Faster rebuild is not always safer if it overloads hardware or causes severe production latency.
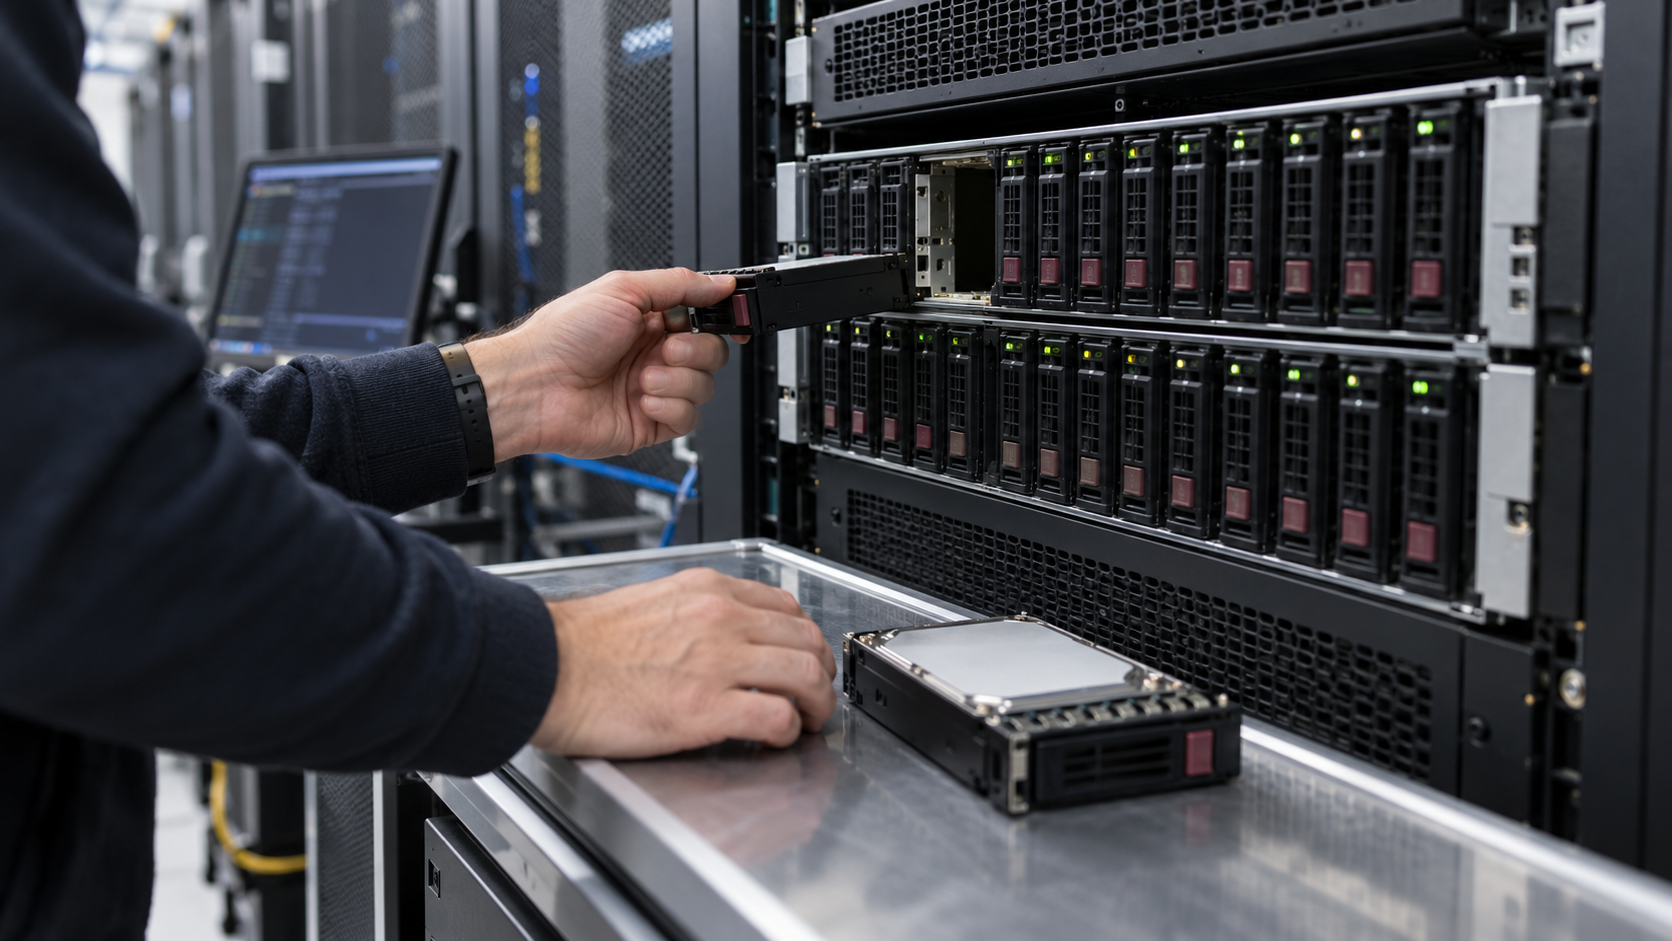
RAID states must be interpreted carefully. A hot spare may begin rebuilding automatically, while a manual replacement requires an operator to identify the correct failed member. Replacing the wrong healthy drive can exceed the array’s remaining tolerance. A drive that briefly disconnected may return with stale data and need resynchronization rather than immediate trust. Monitoring should report degraded status, rebuild progress, read errors, and the identity of each physical device. Backups must remain independent because RAID does not protect against deletion, corruption, malware, controller failure, fire, or a mistake replicated across every member.
After reconstruction, the system verifies membership and returns to a redundant state, but that does not prove every file is healthy. Background scrubbing can read all stripes and compare or repair redundancy before a real failure exposes hidden damage. Operators also investigate why a member failed, confirm backups, and replace other questionable hardware rather than treating a completed percentage as the whole recovery. RAID rebuilding is controlled reconstruction, not magic regeneration: it consumes the surviving redundancy to calculate missing blocks, maintains consistency with new writes, and restores protection only if enough trustworthy information remains throughout the process.
Replacement capacity and geometry must meet the array’s rules. A nominally similar drive can contain slightly fewer usable sectors, preventing it from accepting the member layout. Sector size, error behavior, firmware, and interface compatibility also affect recovery. Some arrays support replacing a still-readable drive proactively by copying directly before removal, which avoids reconstructing every block from parity. Others reshape or expand while rebuilding, adding additional failure modes and time. Maintenance records should capture serial numbers and bay locations so a logical member maps unambiguously to the physical device an operator touches.
A RAID rebuild reconstructs a missing member from surviving mirrors, data blocks, and parity, then writes the result to a replacement. Key terms include array, member, degraded, stripe, mirror, parity, spare, resynchronization, bitmap, scrub, and redundancy.
The array may need to read and reconstruct a very large address range while serving ordinary I/O. Drive speed, capacity, controller resources, error recovery, and workload throttling all affect the duration.
No. RAID can preserve service through certain device failures, but it can replicate deletion or corruption and does not cover theft, fire, ransomware, or every hardware fault. Independent tested backups are still required.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.