

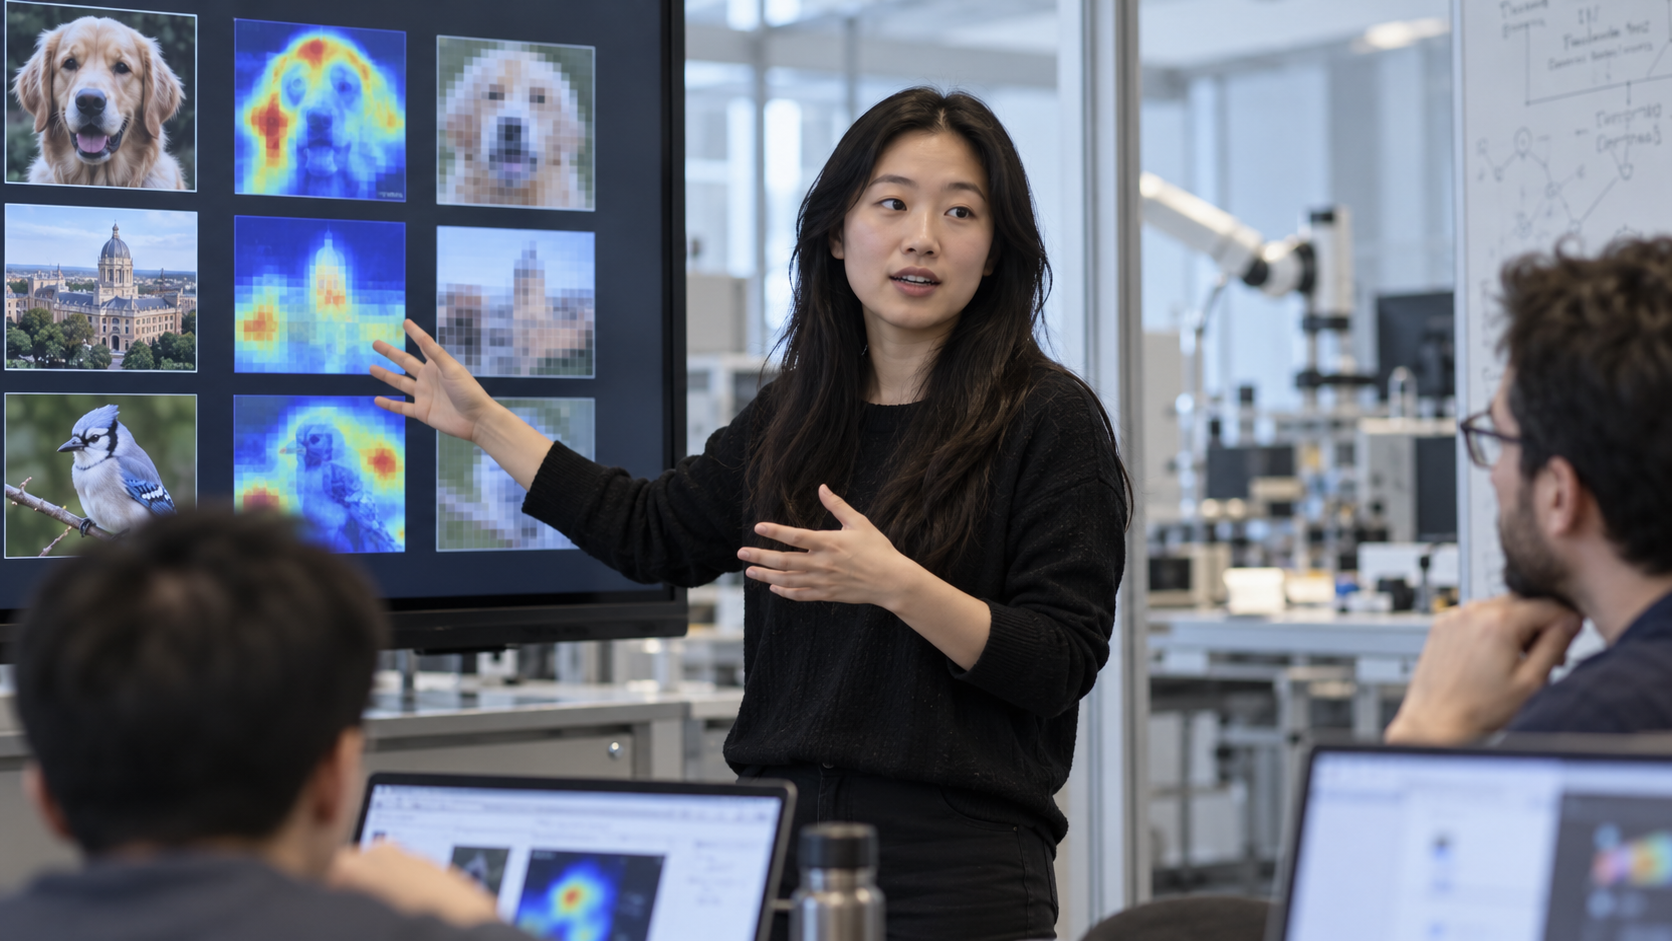
“TCAV uses directional derivatives to compute models’ conceptual sensitivity across entire classes of inputs.”
Been Kim and colleagues introduced Testing with Concept Activation Vectors, or TCAV, to make neural-network explanations more aligned with concepts people use. Instead of asking only which individual pixels influenced one prediction, a researcher can define a concept through examples—such as stripes—and test whether movement in that concept’s learned direction affects predictions across a class. The line has lasted because it captures a research turning point without pretending that one paper settled every scientific or social question around it.
TCAV treats a concept as a direction in a model’s internal activation space. Directional derivatives measure how sensitive an output is to movement along that direction, and a class-level score summarizes the pattern across many examples. This design supports questions that are closer to human reasoning: whether a model uses a medical texture, a visual style, or another meaningful idea when making decisions. The sentence also shows why definitions matter. When researchers specify what they are measuring, disagreement can become an experiment instead of a contest between impressions.
Concept-based interpretation can help developers compare models, detect unwanted shortcuts, and communicate with domain experts. A clinician or scientist may find a concept more actionable than a heat map of thousands of features. Teams should define concepts with representative positive and negative examples, repeat tests across layers and random controls, and involve subject-matter experts in deciding whether the concept itself is valid. For present-day teams, the lesson is to translate broad enthusiasm into observable outcomes. A strong deployment plan names users, failure modes, review points, and the evidence that would justify changing course.
An explanation method can create false confidence if its concept set is incomplete or the learned direction is unstable. TCAV measures association within a model, not necessarily causal importance in the world. A reassuring score does not prove that the model is fair, safe, or robust. Interpretability should support broader evaluation and debugging, not become a certificate that replaces outcome testing. The most durable response is neither reflexive celebration nor blanket rejection. It is disciplined adoption: verify the benefit, disclose the limitation, and preserve a workable human alternative. Kim’s work moves explanation toward the language of human inquiry. Its greatest value comes when concepts become testable hypotheses rather than decorative stories about a model. Responsible progress depends on maintaining that distinction. Technical possibility opens a door, while public value depends on careful implementation, meaningful oversight, and the ability to learn from failure. The work continues with care.
Users provide examples of a concept, and TCAV learns a direction that represents it in the model’s activation space.
The method then tests how moving in that direction changes outputs across many examples of a target class.
A single saliency map can be unstable or too local to reveal a model’s broader strategy.
Aggregating conceptual sensitivity supports questions about patterns the model uses consistently across a category.
Concept choices, example quality, model layers, and statistical controls influence the result.
TCAV can reveal clues and test hypotheses, but fairness, safety, causality, and robustness require additional evidence.
Explore more "Quotes of The Day"
Continue exploring how writers, thinkers, artists, and advocates have described the choices that shape an everyday life.