

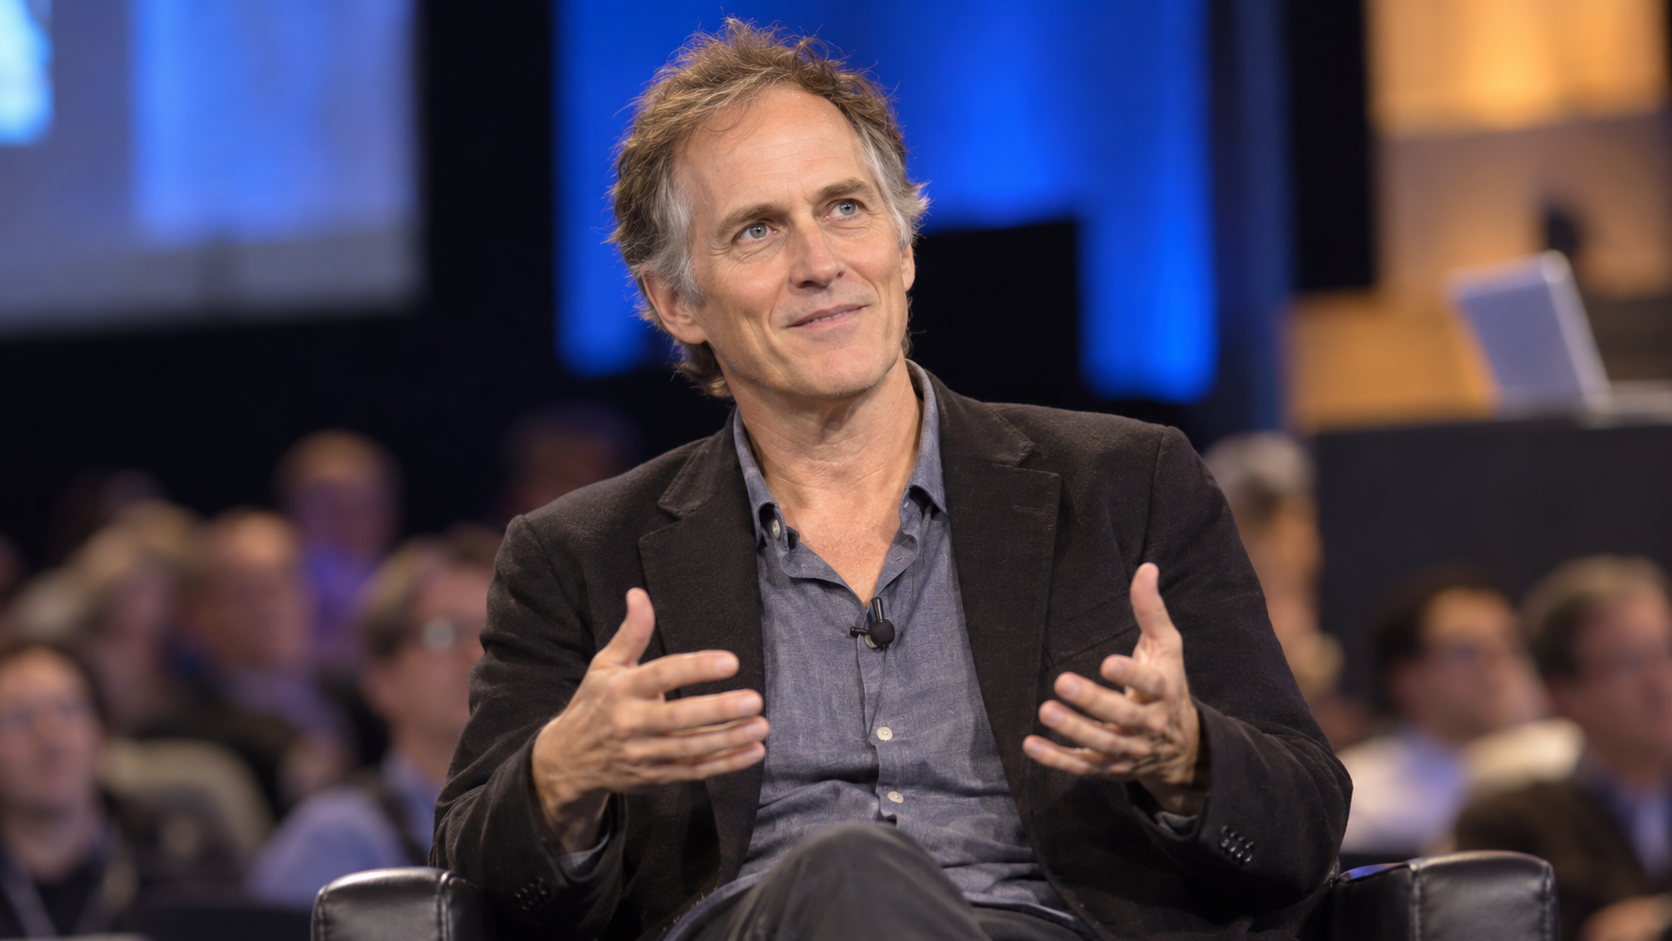
“Data is the Next Intel Inside.”
Tim O’Reilly used this phrase as a section heading in his September 2005 essay “What Is Web 2.0,” which tried to identify why some internet companies had survived the dot-com collapse and grown stronger. The comparison recalled the “Intel Inside” campaign that made an unseen computer component a recognizable source of value. O’Reilly argued that web services also had a critical component beneath the interface: a specialized database. Google had its web crawl, Amazon its product catalog, eBay its marketplace history, and mapping services their geographic records. Software mattered, but the information gathered, organized, and continually improved could be much harder for a competitor to reproduce.
The insight was not simply that applications use databases; that had been true for decades. Web services could turn participation and operation into a continuously refreshed asset. Searches revealed relationships among pages, purchases enriched recommendations, and contributions expanded shared collections. Better data could attract more use, which produced more signals and made the service better again. In that loop, value came from provenance, coverage, structure, and update speed rather than from raw volume alone. O’Reilly’s analogy helped explain why freely available software did not erase competitive advantage. When infrastructure became easier to copy, a distinctive and well-maintained body of information could become the scarce component.
The phrase also requires caution. Calling data an internal component can make the people represented by it disappear from view. Information may be incomplete, biased, licensed under restrictions, or gathered without meaningful consent. A large collection can be strategically valuable while remaining unreliable for a particular decision. Ownership is not the only path to durable value, either; open datasets and interoperable standards can support ecosystems that no single firm controls. The responsible reading of O’Reilly’s claim is therefore descriptive before it is prescriptive. Data can shape an application’s power and market position, so its quality, governance, and permitted uses deserve the same architectural attention as code.
Two decades later, the maxim follows technology into machine learning, where training corpora, evaluation sets, user feedback, and retrieval indexes influence what a model can do. It also applies to ordinary products that depend on inventories, identity records, sensor histories, or local knowledge. Yet accumulation alone is not a strategy. Data becomes useful when people can trace its source, correct errors, protect sensitive fields, and connect it to a clearly defined service. O’Reilly’s phrase remains a sharp test for builders: identify the information that truly improves the product, then ask who created it, what rights accompany it, how it changes, and whether the system can earn continued trust while using it.
O’Reilly made the phrase a core principle in his 2005 essay defining the business and design patterns associated with Web 2.0.
He pointed to the specialized databases behind search, commerce, auctions, and maps as components competitors could not easily recreate.
Distinctive data can create a feedback loop in which use improves the service and the improved service attracts more use.
Value does not erase obligations: provenance, consent, quality, licensing, bias, security, and interoperability remain design concerns.
Machine-learning systems and everyday digital products increasingly depend on datasets whose history directly shapes their behavior.
Responsible teams treat information as maintained infrastructure, asking where it came from, how it changes, and whether its use deserves trust.
Explore more "Quotes of The Day"
Discover more notable quotes from influential voices across politics, science, business, technology, sports, and culture. Each quote offers insight into how ideas, beliefs, and decisions shape the world around us.