

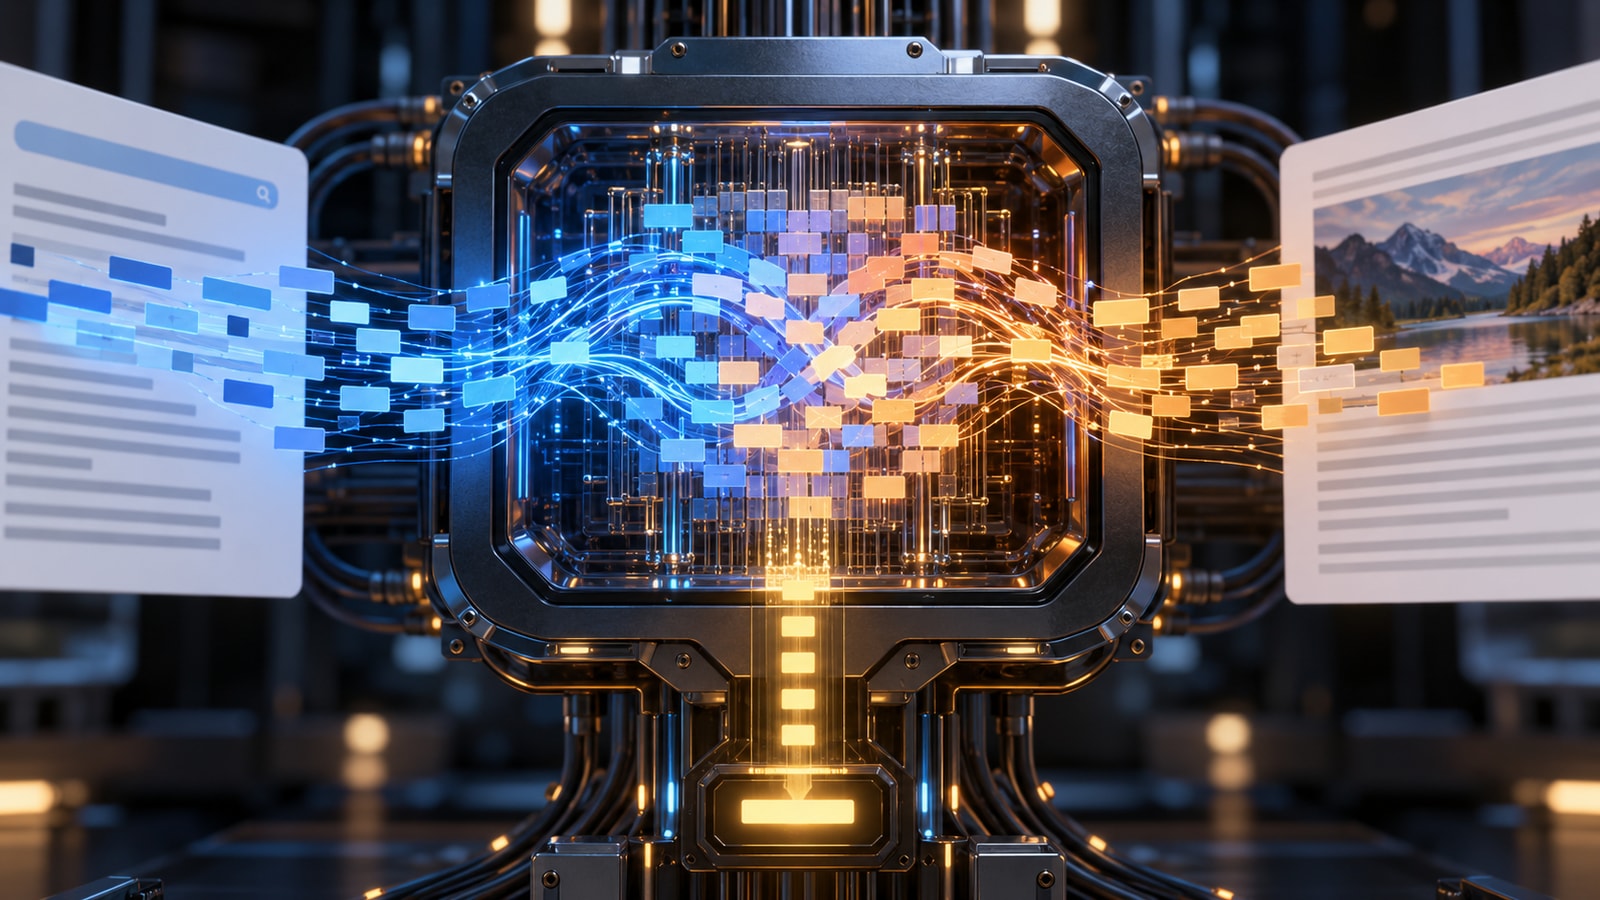
Cross-Encoder Explainer
A cross-encoder feeds two pieces of text, or two modalities, through one model together. For search, the query and candidate passage share the same attention layers, allowing every token in one input to interact with tokens in the other.
The model produces a relationship score or label, such as relevance, entailment, or semantic similarity. Joint processing captures detailed alignments that separate subtle matches from merely related content.
Cross-encoders are strong rerankers and pair classifiers. They are commonly applied after a fast retriever has reduced millions of candidates to tens or hundreds.
Because each query-candidate pair requires a fresh model pass, a cross-encoder cannot cheaply precompute independent document vectors. Cost grows with candidate count and input length. Deployment must balance accuracy, batch size, latency, and truncation.
A cross-encoder processes two inputs together so attention can model detailed interactions before predicting their relationship.
Key terms include cross-encoder, paired input, self-attention, interaction, relevance score, reranking, candidate and latency.
Joint attention exposes fine token-to-token relationships between the query and candidate.
The output directly scores that specific pair.
Every new pair needs its own computation, so large collections require a faster first stage.
Candidate count and input length drive latency and cost.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.