

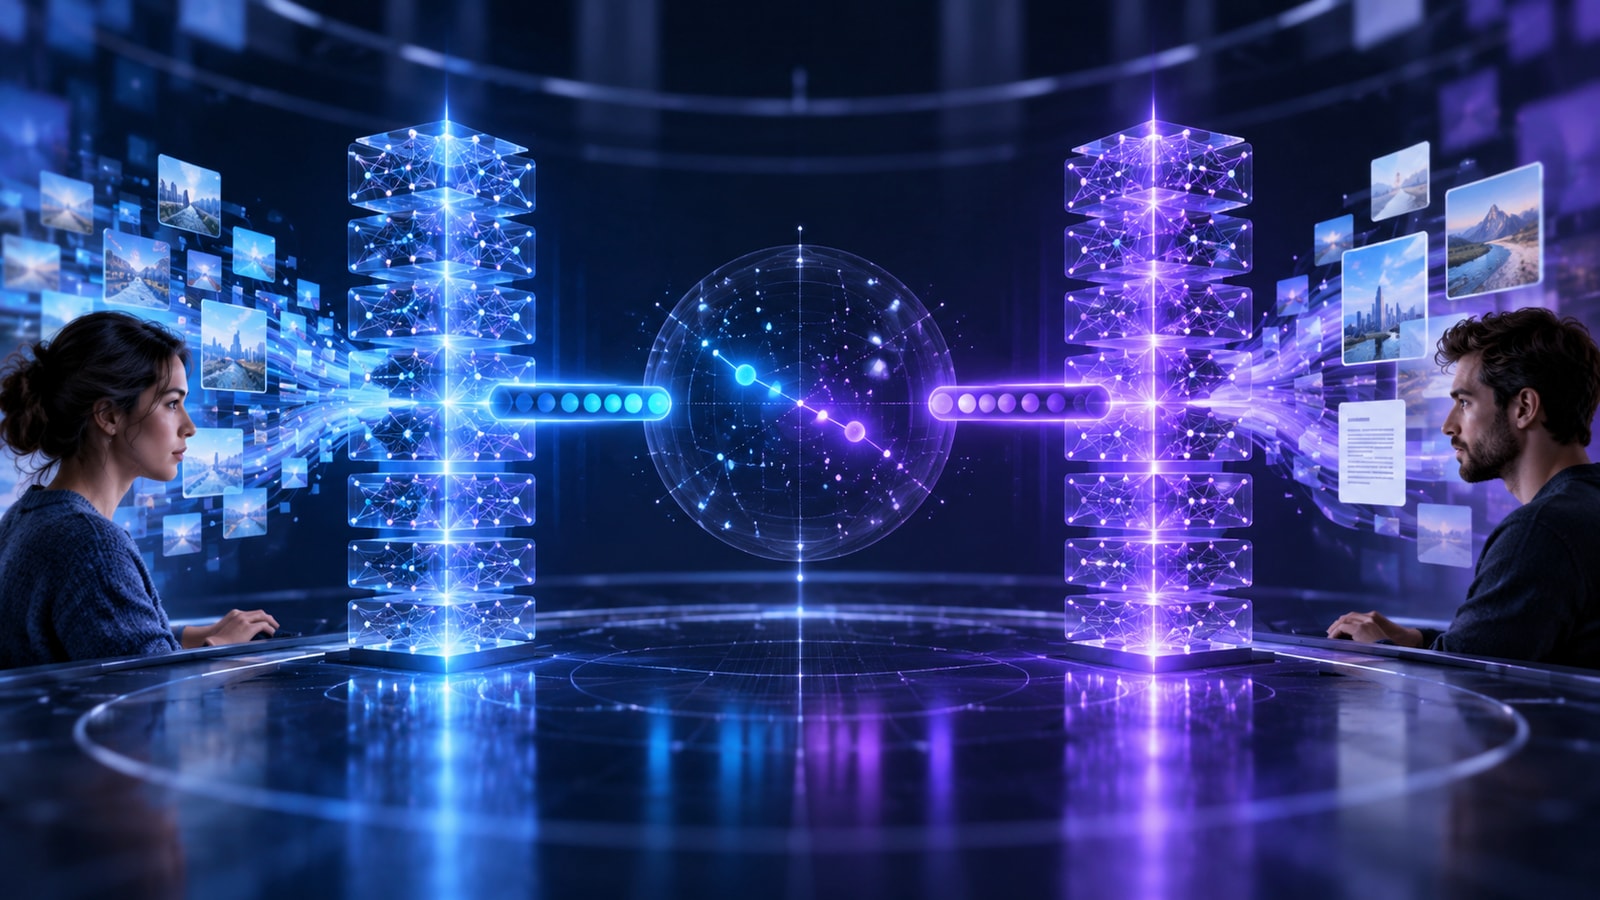
Bi-Encoder Explainer
A bi-encoder uses two encoding branches to transform inputs independently into vectors. The branches may share weights or use related models. A simple similarity function, often a dot product or cosine similarity, compares the resulting vectors.
Documents can be encoded before any query arrives and stored in a vector index. At search time, only the query needs a new encoding, making retrieval across a large collection efficient.
Bi-encoders support semantic search, duplicate detection, recommendation, and retrieval for question answering. Contrastive training pulls matched pairs together and pushes nonmatches apart.
Independent encoding cannot represent every fine interaction between query words and a candidate. Long or highly specific constraints may be compressed away. Strong systems use good negatives, careful pooling, calibrated similarity, and a cross-encoder reranker.
A bi-encoder converts two inputs independently into vectors that can be compared quickly with a similarity function.
Key terms include bi-encoder, dual encoder, embedding, cosine similarity, dot product, precomputation, contrastive learning and reranker.
Candidate vectors are computed once and reused across many queries.
A lightweight similarity calculation ranks large collections efficiently.
Each input must summarize itself without seeing the other input.
A later cross-encoder can restore detailed interaction for a shortlist.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.