

ALiBi in Transformer Models Explainer
ALiBi stands for Attention with Linear Biases. It represents position by adding a penalty to attention scores based on the distance between the query and key, rather than adding positional embeddings to token vectors.
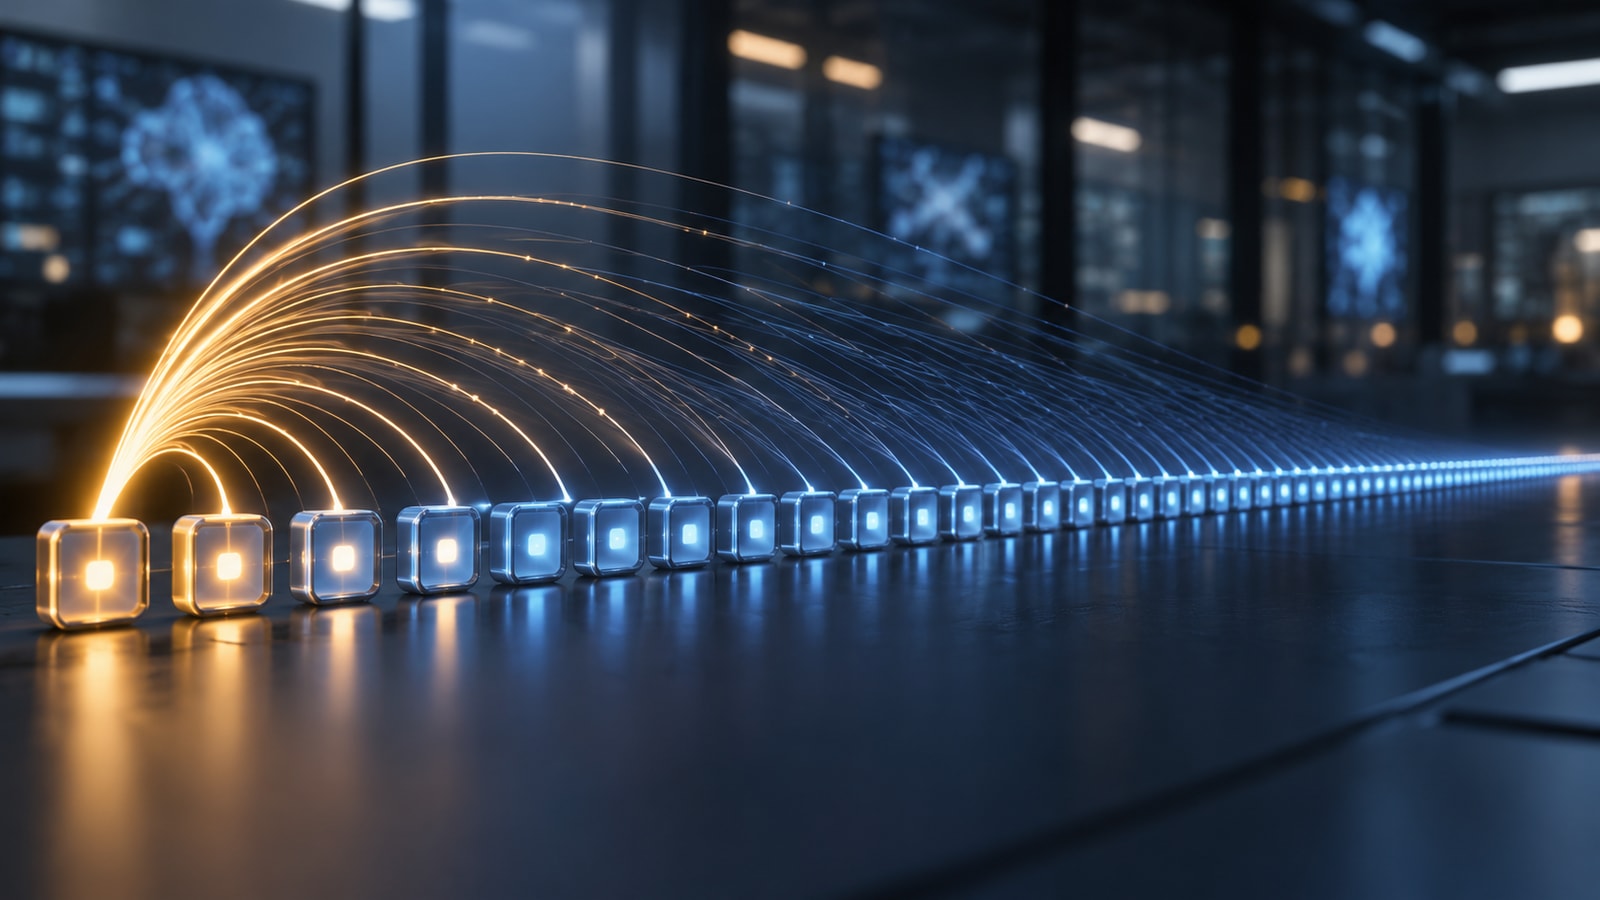
Different attention heads use different fixed slopes. Some heads strongly favor nearby tokens, while others apply a gentler distance penalty and can attend more broadly across the sequence.
The method is simple, adds little memory, and was designed to let models trained on shorter sequences operate on longer ones. It keeps relative distance inside the attention calculation.
A linear bias is an inductive preference, not proof of reliable long-context reasoning. Task quality depends on training data, architecture, and length distribution. Evaluation should compare extrapolation, local accuracy, long-range retrieval, and generation speed.
ALiBi adds a distance-based bias to attention scores so farther tokens receive a larger penalty without learned positional embeddings.
Key terms include ALiBi, attention bias, distance penalty, slope, attention head, position, extrapolation, sequence length and inductive bias.
Keys farther from the query receive a larger negative bias.
Different head slopes create several ranges of positional preference.
The model may accept more tokens without using distant evidence effectively.
Evaluation should test retrieval and reasoning across the full claimed length.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.