

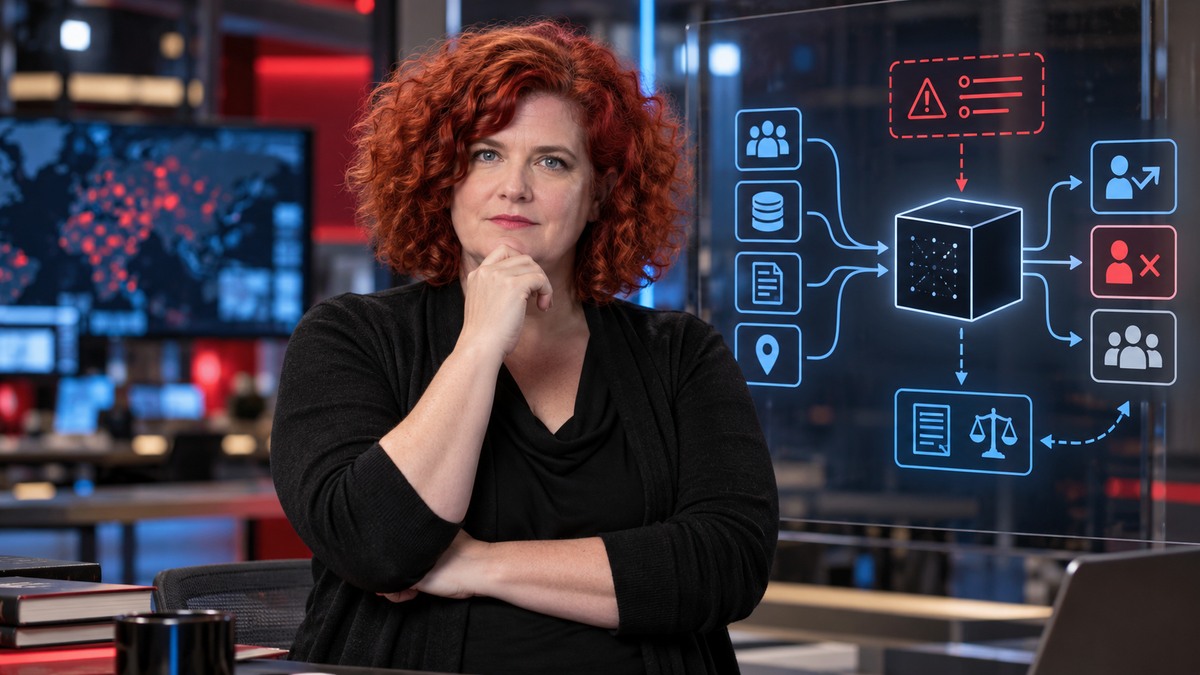
“Algorithms are opinions embedded in code.”
Cathy O’Neil used this formulation in explaining the argument of Weapons of Math Destruction and in public talks about algorithmic accountability. It challenges the idea that a mathematical model is neutral simply because its rules are written in software or expressed as a score. Every model reflects choices about the goal, training data, proxies, thresholds, and acceptable error. Those choices may be reasonable, but they are judgments. When a score allocates jobs, credit, insurance, attention, or discipline, its assumptions become part of organizational policy. Behind the concise wording is a claim about how organizations create results. It encourages leaders to look beyond individual effort and examine design, incentives, information, relationships, and the customer context that determine whether a good intention becomes reliable performance.
Leaders can document the decision a model supports, who benefits from each error type, which groups are underrepresented, and how performance changes after deployment. High-impact systems need independent testing, understandable notices, human review, and a practical appeal path. Managers can translate the claim into a small experiment with a baseline, an owner, a defined customer or employee outcome, and a review date. Specificity protects the work from drifting into broad language that nobody can challenge or verify.
Human decisions also contain bias, so abandoning models is not automatically safer. The comparison should be evidence-based and include consistency, transparency, accountability, and harm. Proprietary complexity cannot excuse a company from understanding the system it chooses to use. Responsible use also requires naming the tradeoff. Speed, cost, autonomy, safety, equity, and learning may not all improve at once. People closest to the consequences should have a meaningful voice, and uncertainty should be reported instead of hidden behind confidence.
Generative and predictive AI now influence everyday business decisions at unprecedented scale. Outputs can appear individualized and authoritative while remaining probabilistic. Governance must cover vendors, changing models, monitoring, incident response, and the cumulative effect of repeated automated judgments. Select one operational score and list its objective, proxy, data source, major error types, affected groups, and appeal process. If any element is unknown, pause expansion until the organization can explain and test the policy encoded by the model. Evidence from the experiment can guide scaling, revision, or stopping. The durable lesson is to join purpose with measurement and human judgment, so the organization becomes better at seeing reality and responding before a local success or failure hardens into mythology. Recording the decision and its limits gives colleagues a foundation they can inspect, challenge, and improve instead of asking them to rely on memory, authority, or an unexplained result.
Cathy O’Neil used this formulation in explaining the argument of Weapons of Math Destruction and in public talks about algorithmic accountability. It challenges the idea that a mathematical model is neutral simply because its rules are written in software or expressed as a score.
Every model reflects choices about the goal, training data, proxies, thresholds, and acceptable error. Those choices may be reasonable, but they are judgments. When a score allocates jobs, credit, insurance, attention, or discipline, its assumptions become part of organizational policy.
Leaders can document the decision a model supports, who benefits from each error type, which groups are underrepresented, and how performance changes after deployment. High-impact systems need independent testing, understandable notices, human review, and a practical appeal path.
Human decisions also contain bias, so abandoning models is not automatically safer. The comparison should be evidence-based and include consistency, transparency, accountability, and harm. Proprietary complexity cannot excuse a company from understanding the system it chooses to use.
Generative and predictive AI now influence everyday business decisions at unprecedented scale. Outputs can appear individualized and authoritative while remaining probabilistic. Governance must cover vendors, changing models, monitoring, incident response, and the cumulative effect of repeated automated judgments.
Select one operational score and list its objective, proxy, data source, major error types, affected groups, and appeal process. If any element is unknown, pause expansion until the organization can explain and test the policy encoded by the model.
Explore more "Quotes of The Day"
Discover more notable quotes from influential voices across politics, science, business, technology, sports, and culture. Each quote offers insight into how ideas, beliefs, and decisions shape the world around us.