

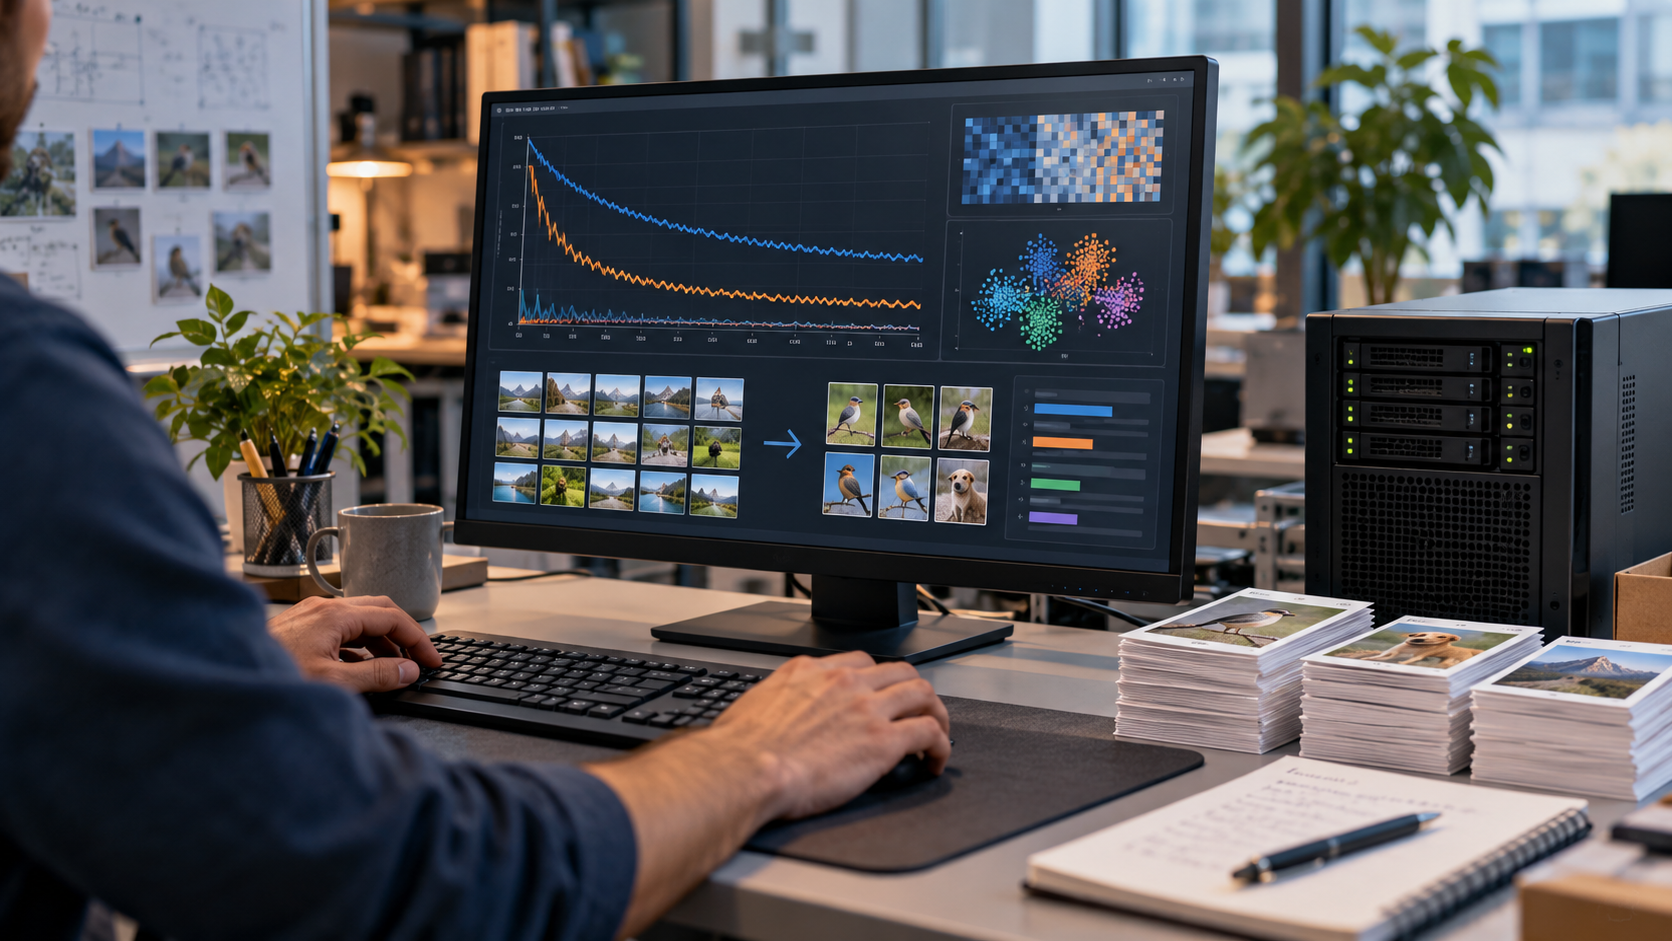
AI Model Fine-Tuning Explainer
Fine-tuning adapts an already trained AI model by continuing its training on a smaller dataset selected for a particular task, domain or style. The base model supplies broad capabilities learned during pretraining; the fine-tuning examples push its parameters toward more specialized behavior. This usually requires far less data and computing power than training a model from scratch.
In supervised fine-tuning, each example pairs an input with a desired output. The model makes a prediction, a loss function measures the gap from the target, and an optimizer adjusts weights over repeated batches and epochs. Teams normally separate training and validation data so they can detect whether the model improves on unseen examples instead of merely memorizing its lessons.
Fine-tuning is useful when prompting alone cannot deliver consistent format, tone or task performance. A support model might learn approved response patterns; a classifier might learn a specialized label set. Full fine-tuning updates many model parameters, while parameter-efficient methods such as adapters or LoRA train a much smaller set of added weights. The lighter approach can reduce storage and training cost.
Customization also creates risks. Narrow, biased or low-quality examples can teach the wrong behavior, and too much training can reduce general abilities through overfitting or catastrophic forgetting. Fine-tuning does not automatically add current facts or guarantee safety. Strong projects begin with a precise target, clean representative data, a held-out evaluation set and ongoing tests for accuracy, robustness, privacy and regressions.
Fine-tuning continues training a pretrained model on focused examples. Key terms include base model, training example, label, loss, optimizer, epoch, validation, overfitting, adapter and LoRA.
Hugging Face’s fine-tuning guide shows the training workflow. Google’s Machine Learning Glossary distinguishes full fine-tuning and parameter-efficient approaches.
Examples are tokenized and grouped into batches. The model’s error is calculated, gradients show how parameters should move, and an optimizer applies small updates.
Full fine-tuning can update most weights. Parameter-efficient methods freeze the base model and train compact adapter weights that can be stored or swapped separately.
Prompting supplies instructions at run time, retrieval supplies external evidence, and fine-tuning changes learned parameters. They solve different problems and can be combined.
Fine-tuning is strongest for repeatable behavior and formats; retrieval is often better for changing knowledge. Teams should choose the least complex method that meets measured requirements.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.