

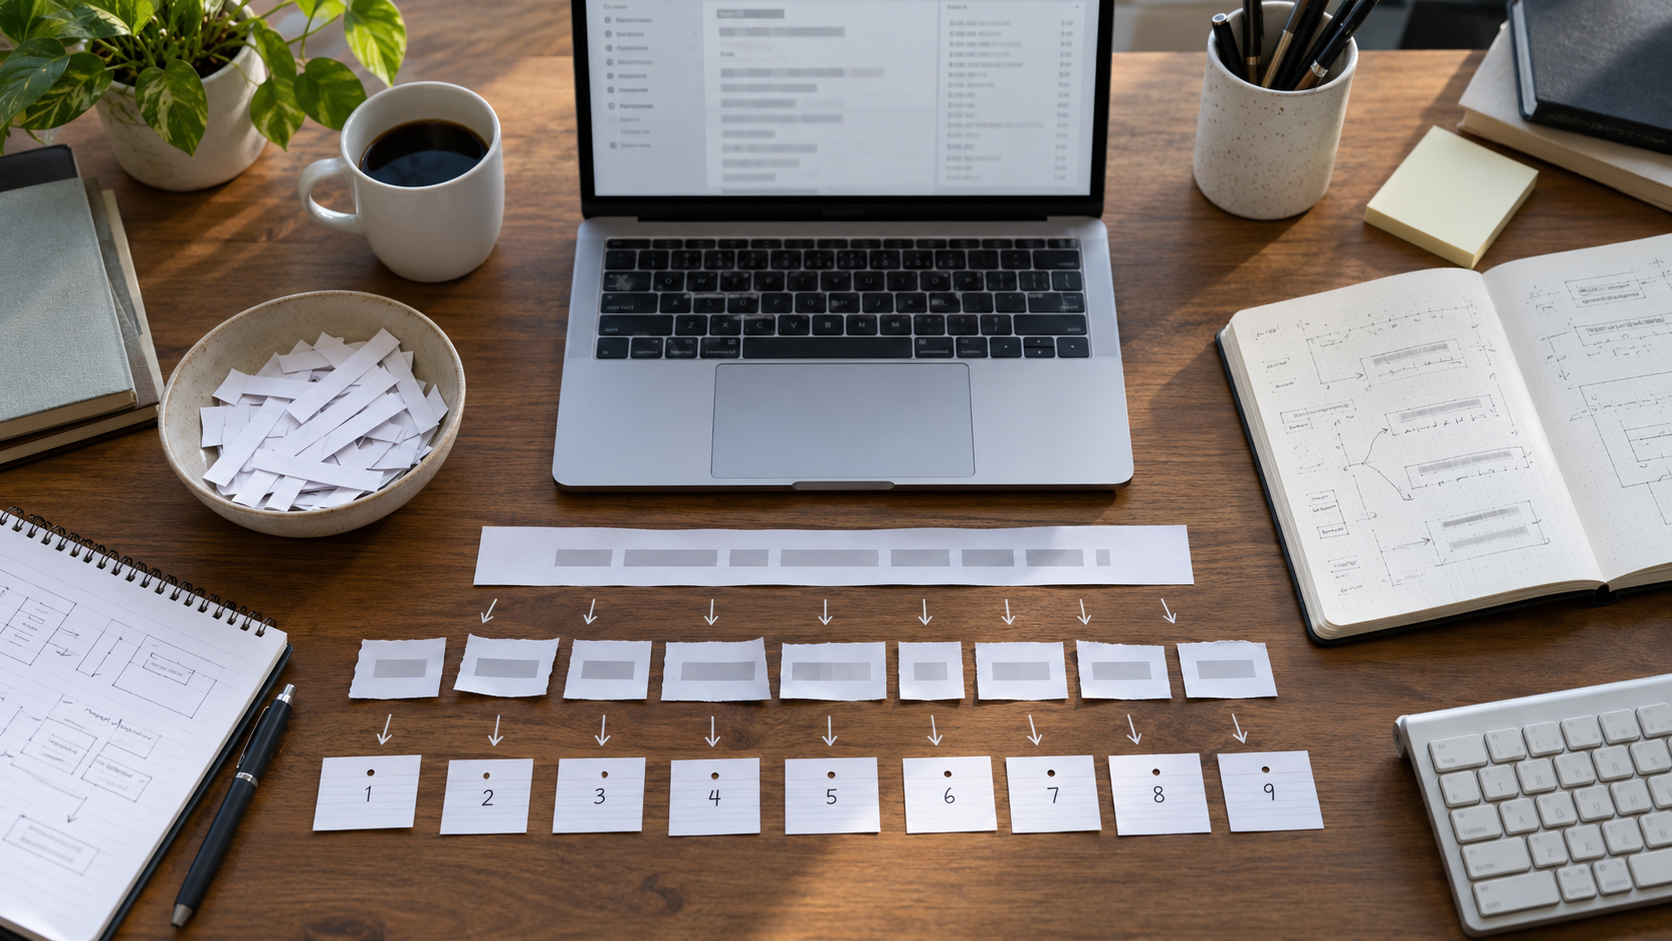
Tokenization in Language Models Explainer
Tokenization is the step that converts text into units a language model can process. A token may be a whole short word, part of a longer word, punctuation, a space pattern or another byte-level piece. The tokenizer then maps each piece to a numeric ID. Those IDs—not the original sentence—are the model’s direct input.
Modern tokenizers commonly use a learned vocabulary of subwords. Frequent strings can receive one token, while unusual names or long technical terms may be divided into several pieces. This helps a model work with an enormous range of text without storing every possible word. Language-independent systems such as SentencePiece can learn useful units directly from raw sentences rather than requiring spaces to define words first.
The exact tokenizer matters. Two models may split the same sentence differently and therefore count different numbers of tokens. Tokenization affects context limits, cost, speed and how efficiently a model represents different languages or writing systems. It can also make spelling, arithmetic and character-by-character tasks harder because the units the model sees do not always match the units a person notices.
During generation, the process runs in reverse. The model predicts a probability distribution over possible next token IDs, a decoding method selects one, and the sequence is converted back into text. Special tokens can mark beginnings, endings, padding, roles or multimodal placeholders. Tokenization does not give a model meaning by itself, but it creates the discrete vocabulary through which the model learns and communicates.
Tokenization splits text into model-readable pieces and converts those pieces to numeric IDs. Key terms include token, vocabulary, subword, byte pair encoding, unigram model, special token, encoding and decoding.
Hugging Face’s tokenizer documentation describes normalization, splitting, special tokens and decoding. The SentencePiece paper presents language-independent subword tokenization from raw text.
The tokenizer normalizes input, divides it into learned pieces, adds any required special markers and looks up an integer ID for each token.
After the model predicts more IDs, the decoder joins their token strings and removes or interprets special markers to produce readable output.
A common word may be one token while a rare name becomes several. Punctuation, capitalization, spacing, code and writing systems can all change the split.
Because context windows and many API costs are measured in tokens, users should count with the tokenizer for the specific model instead of relying on a universal words-to-tokens rule.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.