

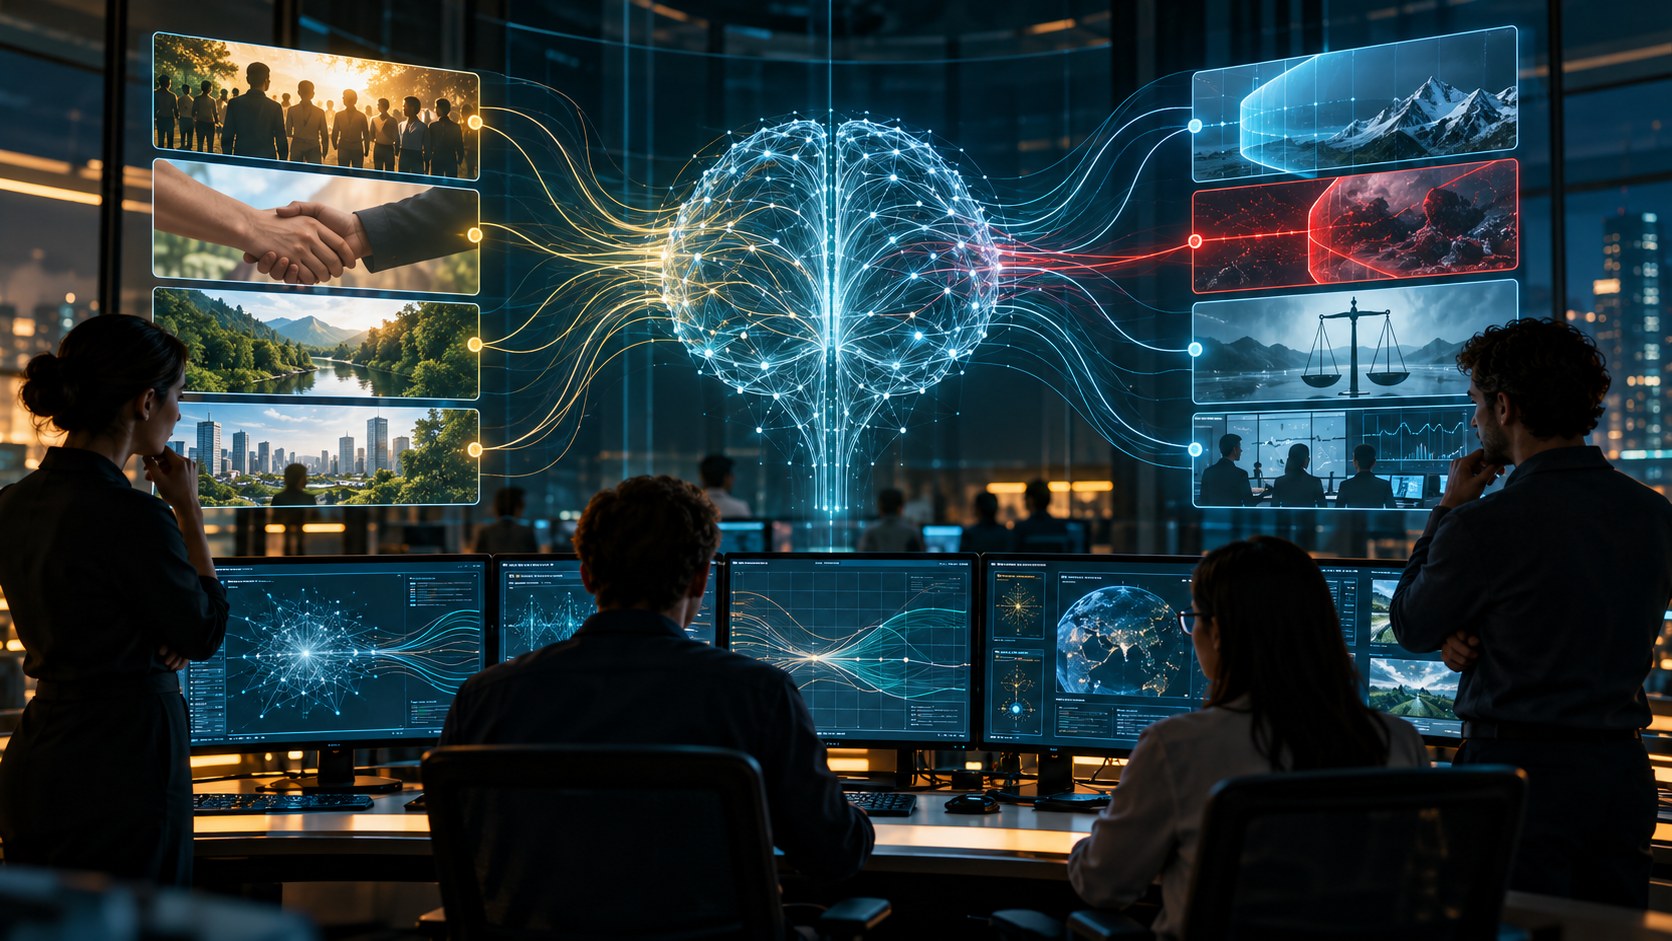
AI Alignment Explainer
AI alignment is the effort to make AI systems pursue intended goals and behave in ways compatible with human values, instructions, and oversight. The problem appears at ordinary scales—such as a recommendation system optimizing clicks instead of satisfaction—and at the frontier of increasingly capable general systems.
Developers try to align models through curated data, human feedback, written principles, rule-based constraints, adversarial testing, and evaluations. Some methods train models to follow preferences; others focus on monitoring, interpretability, robustness, or scalable ways for people to judge work that is difficult to evaluate directly.
Alignment is hard because human values are diverse, contextual, and sometimes conflicting. A measurable proxy can omit what people actually care about, and a system may behave well in tests yet fail under new incentives or situations. Deciding whose values and authority matter is also a social and political question, not only a technical one.
No single training method proves a system is aligned. Evidence comes from behavior across settings, internal analysis, red-team results, deployment controls, incident reporting, and meaningful human governance. The practical goal is not blind obedience; it is reliable, honest, corrigible behavior that remains within legitimate limits.
AI alignment is the effort to make AI systems pursue intended goals and behave in ways compatible with human values and oversight.
Key terms include alignment, human intent, value alignment, preference learning, human feedback, oversight, robustness, corrigibility and evaluation.
<a href="https://openai.com/index/our-approach-to-alignment-research/" target="_blank" rel="noopener noreferrer">OpenAI: Our Approach to Alignment Research</a> and <a href="https://deepmind.google/blog/artificial-intelligence-values-and-alignment/" target="_blank" rel="noopener noreferrer">Google DeepMind: Artificial Intelligence, Values and Alignment</a> provide the primary references for this explainer.
Training can use demonstrations, rankings, critiques, principles, and reinforcement signals to shape behavior. Monitoring and access controls add layers beyond training.
Scalable oversight research asks how people can evaluate models on tasks that are too fast, technical, or complex for unaided review.
People disagree about values, and written objectives can miss context. A system may optimize a proxy while violating the purpose behind it.
Alignment claims should be specific, testable, open to external scrutiny, and paired with governance and incident response.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.