

Federated Learning Explainer
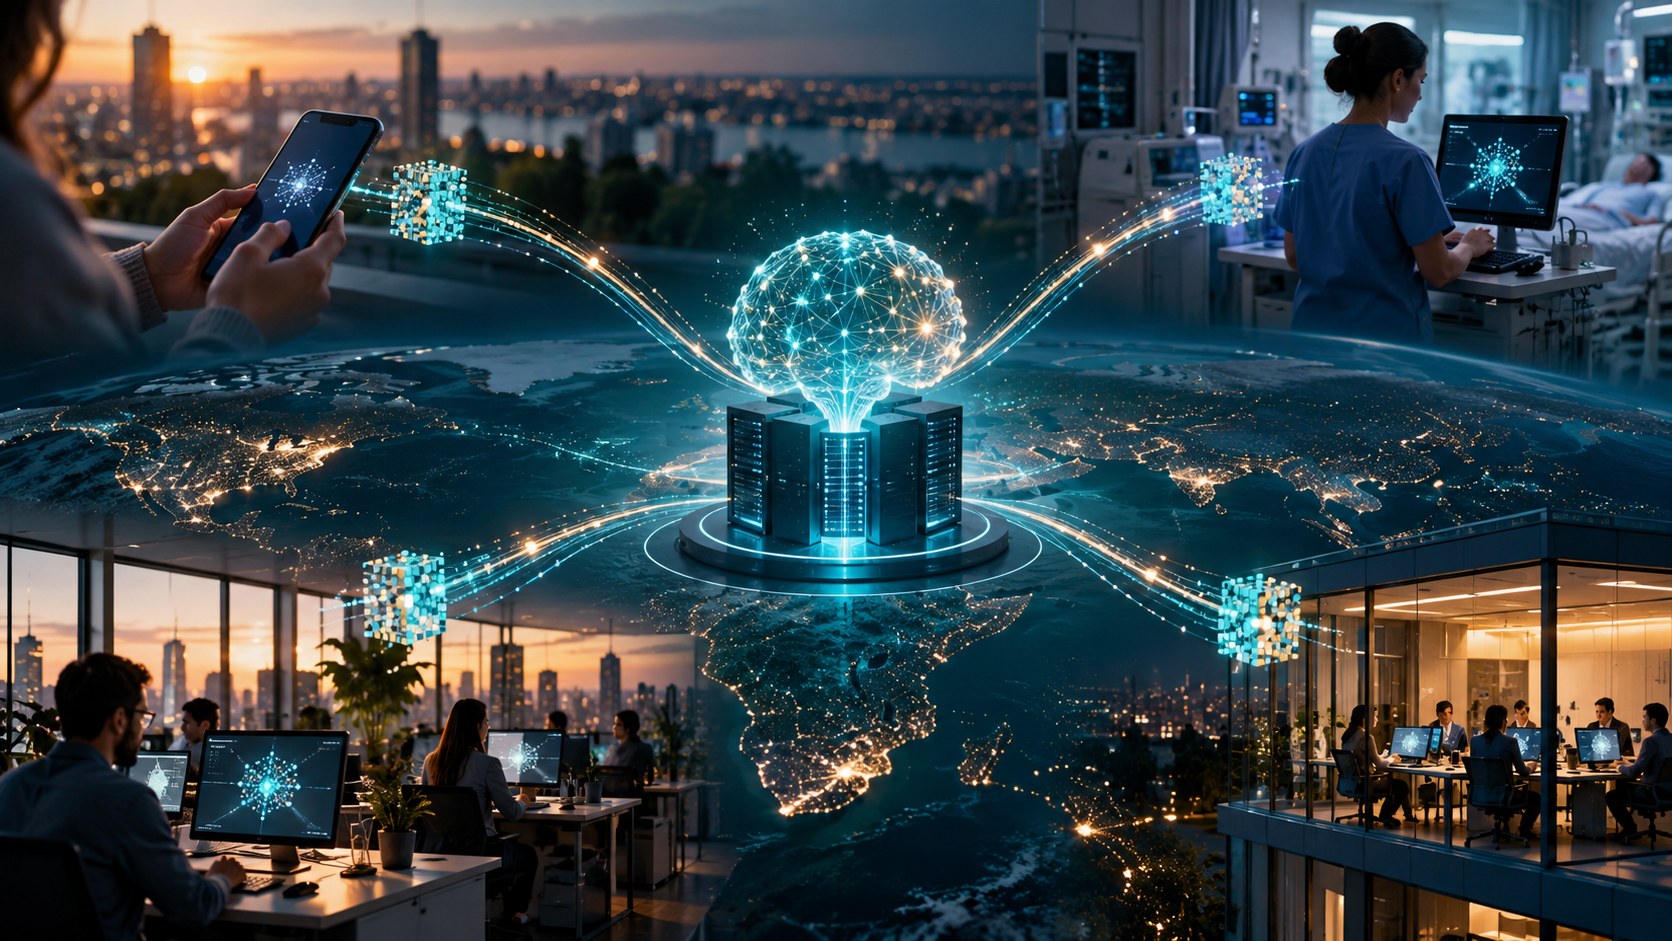
Federated learning is a machine-learning approach in which many devices or organizations help train a shared model while keeping their raw data in local storage. A coordinating server sends a model to selected participants, each participant trains it on local examples, and the server combines the resulting updates.
One influential method, Federated Averaging, repeatedly aggregates local model changes into a new global model. The cycle can continue across different subsets of clients. The approach is useful when data is naturally distributed and cannot or should not be copied into one central dataset.
Keeping raw records local can reduce central data collection and allow learning from diverse real-world environments. Federated learning has applications across phones, health institutions, finance, and other settings where data ownership, bandwidth, or regulation limits centralized training.
Federated learning is not automatic privacy. Model updates can leak information, malicious clients can poison training, and participation patterns can reveal sensitive facts. Secure aggregation, differential privacy, authentication, robust statistics, and governance may be needed. Unequal devices and non-identical local data also make training harder.
Federated learning trains a shared model across decentralized devices or organizations while keeping raw training data local.
Key terms include federated learning, client, server, local training, model update, aggregation, Federated Averaging, secure aggregation and differential privacy.
<a href="https://arxiv.org/abs/1602.05629" target="_blank" rel="noopener noreferrer">Communication-Efficient Learning of Deep Networks from Decentralized Data</a> and <a href="https://www.tensorflow.org/federated" target="_blank" rel="noopener noreferrer">TensorFlow Federated</a> provide the primary references for this explainer.
Clients receive the current model, train locally, and return parameter updates. A server aggregates those updates into the next shared model.
Communication efficiency matters because clients may have slow networks, limited power, and intermittent availability.
Updates can leak information or be manipulated. Keeping raw files on-device does not remove the need for privacy and security protections.
Secure aggregation, differential privacy, robust aggregation, client authentication, and careful governance address different parts of the risk.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.