

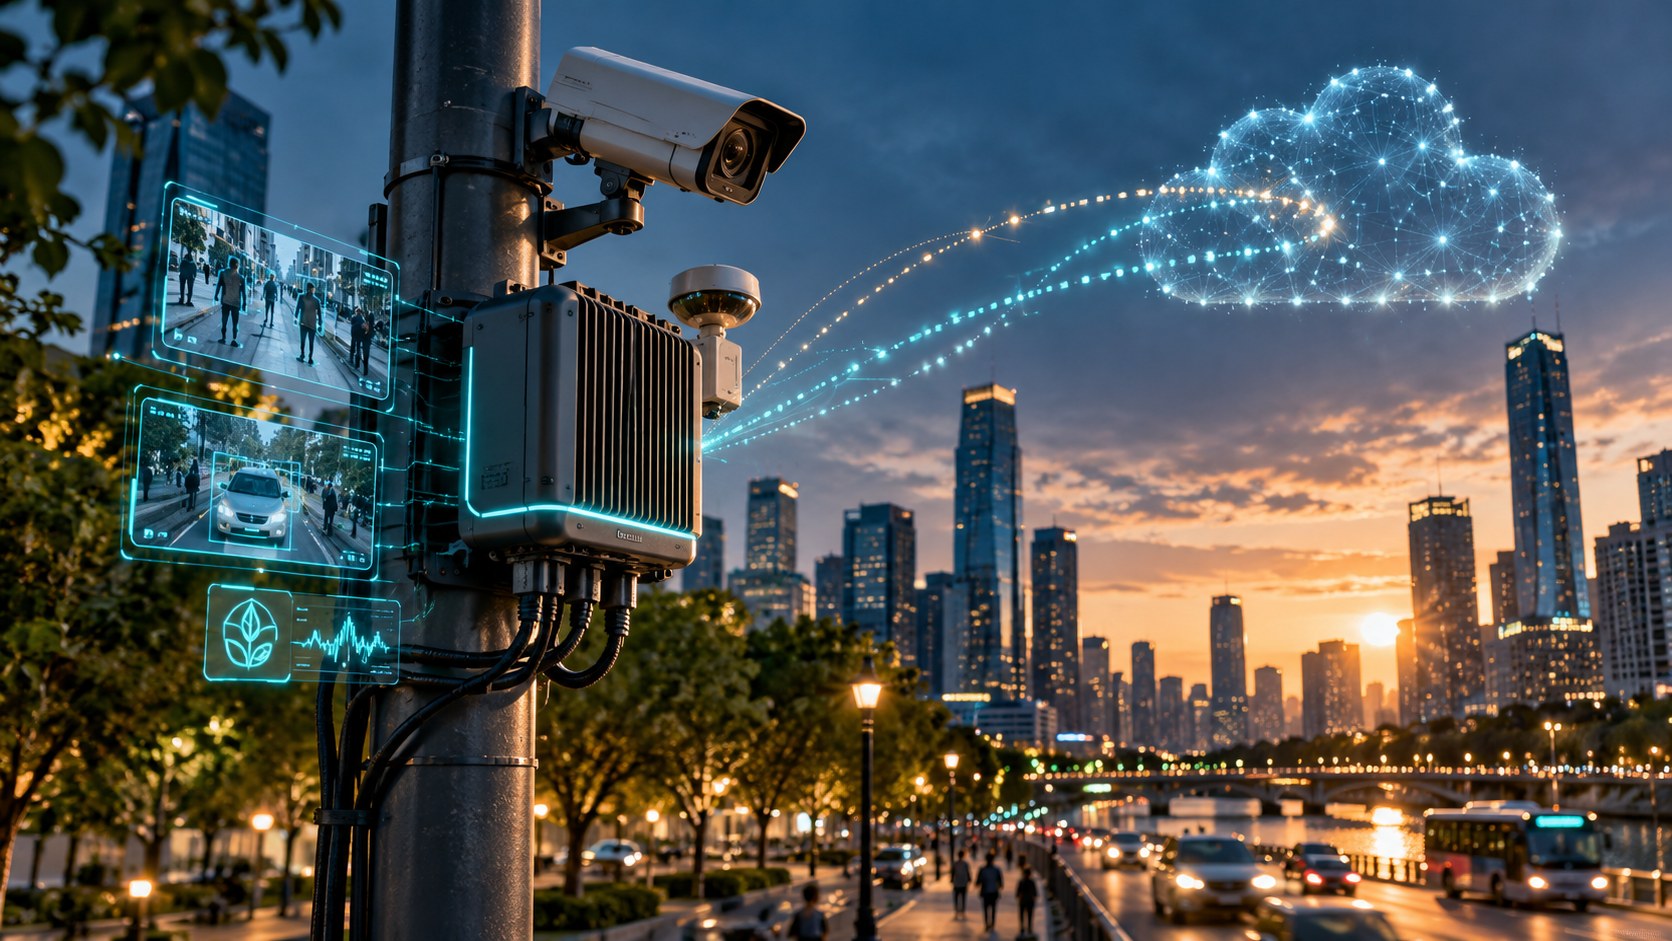
Edge AI Explainer
Edge AI runs machine-learning models on or near the device where data is produced, such as a phone, camera, vehicle, appliance, factory controller, or local gateway. Instead of sending every input to a distant data center, the device performs some or all inference locally.
Local processing can reduce network delay, keep an application working offline, lower bandwidth use, and limit how much raw data leaves the device. Hardware may include CPUs, GPUs, neural processing units, or specialized accelerators, while runtimes translate and optimize a model for the platform.
Edge AI supports live translation, camera effects, predictive maintenance, accessibility features, robotics, and safety systems that cannot wait for a network round trip. Cloud and edge can also work together: the device handles immediate tasks while servers provide heavier analysis, updates, or coordination.
Edge devices have tight limits on memory, power, heat, and maintainability. Smaller or quantized models may lose quality, and compromised devices can expose models or manipulated inputs. Teams must test on real hardware, plan secure updates, protect local data, and decide what should happen when the model or sensor is uncertain.
Edge AI runs machine-learning models on or near the device where data is produced instead of relying entirely on a distant cloud.
Key terms include edge AI, on-device inference, gateway, accelerator, latency, offline operation, quantization, power budget and secure update.
<a href="https://developers.google.com/edge" target="_blank" rel="noopener noreferrer">Google AI Edge</a> and <a href="https://www.tensorflow.org/model_optimization/guide" target="_blank" rel="noopener noreferrer">TensorFlow Model Optimization Toolkit</a> provide the primary references for this explainer.
Local inference can reduce latency and bandwidth, support offline operation, and keep some raw sensor data on the device.
Hybrid systems split work between edge and cloud according to speed, privacy, cost, and model capability.
Memory, battery, heat, processor support, and update channels limit what can run reliably at the edge.
Benchmark the complete device, secure the model and update path, and design a safe fallback for uncertain or failed inference.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.