

AI Inference Explainer
AI inference is the stage when a trained model is used to produce an output from new input. A vision model may label an image, a forecasting model may estimate demand and a language model may generate a response to a prompt. Training determines the model’s parameters; inference applies those learned parameters without repeating the full training process.
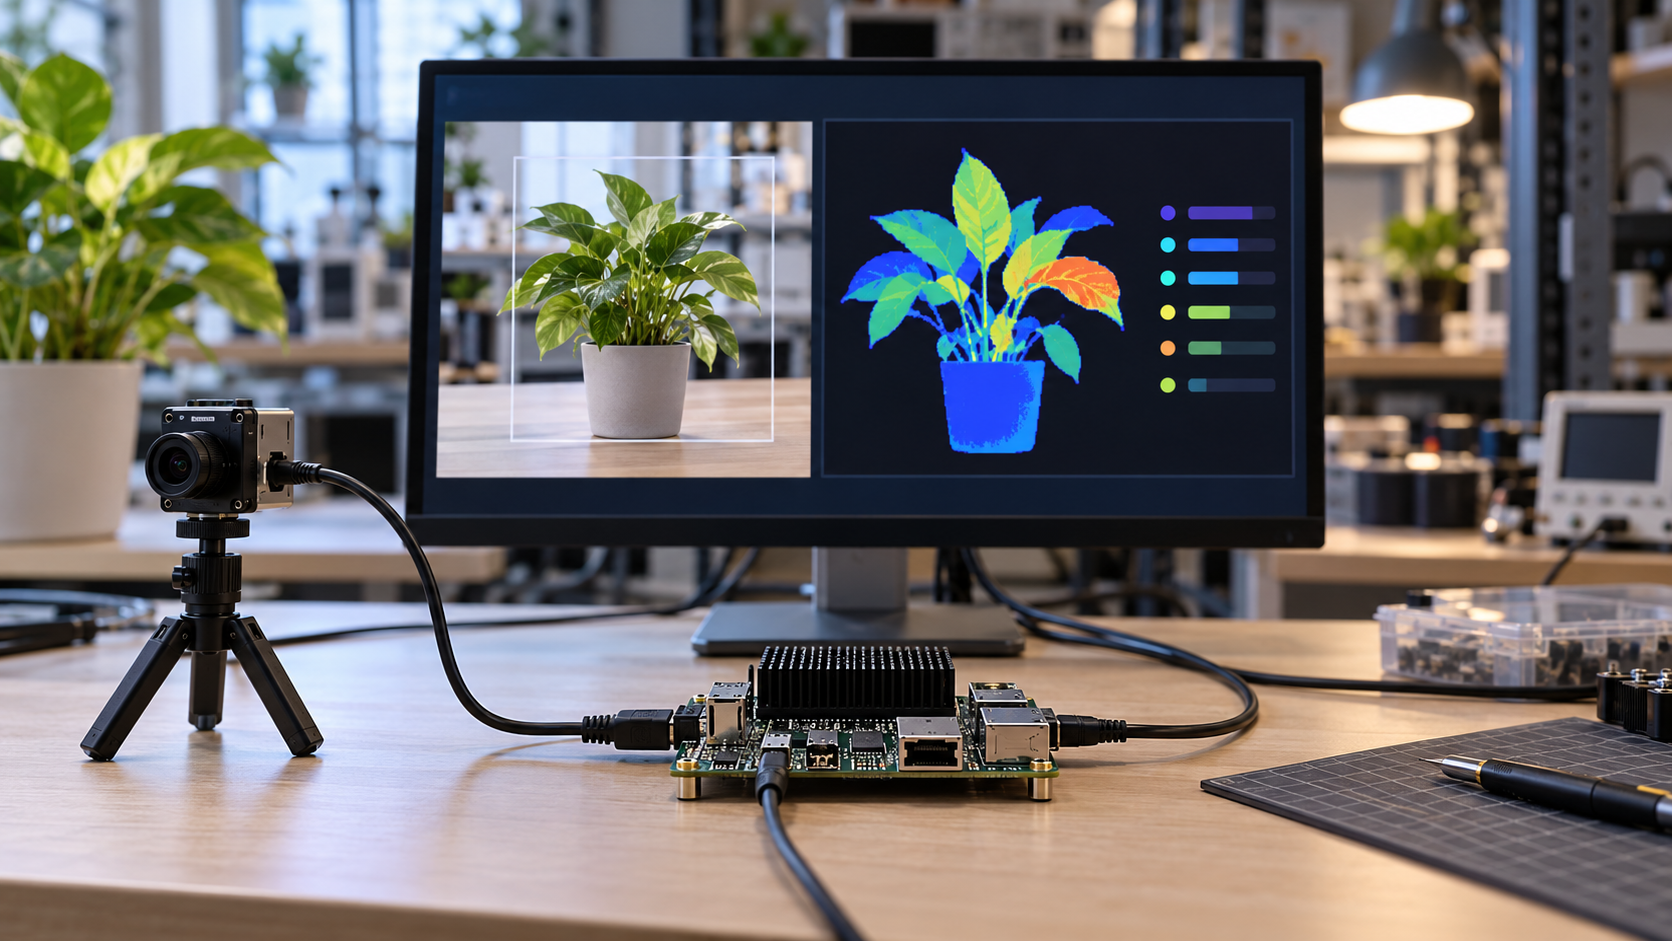
An inference pipeline prepares the input in the same form the model expects, loads the model or an optimized runtime, performs mathematical operations across its layers and converts raw outputs into a usable result. For a language model, that cycle can run once for each generated token. For a camera system, it may repeat many times per second as new frames arrive.
Where inference runs depends on the product. Cloud servers can offer large pools of accelerators and centralized updates. Edge devices such as phones, vehicles and sensors can reduce network delay and keep some data local, but they have tighter limits on memory, power and heat. Batch inference processes many stored examples together; online inference responds to requests as they arrive.
Production teams balance accuracy, latency, throughput, cost, energy use and reliability. They may quantize weights, batch requests, cache repeated work, compile models for specific hardware or use smaller models for easier tasks. Optimization can change performance, so the deployed system must be tested on realistic inputs. Inference is where a trained model meets the world—and where its speed, limits and errors become visible to users.
Inference uses a trained model to compute an output for new input. Key terms include prediction, runtime, serving, latency, throughput, batch, online inference, edge device, quantization and accelerator.
Google’s Machine Learning Glossary defines inference for traditional and large language models. NVIDIA’s TensorRT guide shows the path from a trained model to an optimized runtime and deployed predictions.
Training repeatedly adjusts model weights using examples and a loss signal. Inference keeps the learned weights fixed while it processes a new request.
One inference is usually cheaper than training, but serving millions of requests can make inference the larger continuing expense for a widely used product.
Latency measures how long one request takes; throughput measures how much work a system completes over time. Batching can improve throughput while adding wait time.
Compilers, lower-precision numbers, caching and specialized chips can accelerate serving. Every optimization should be checked for accuracy, compatibility and behavior on real workloads.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.