

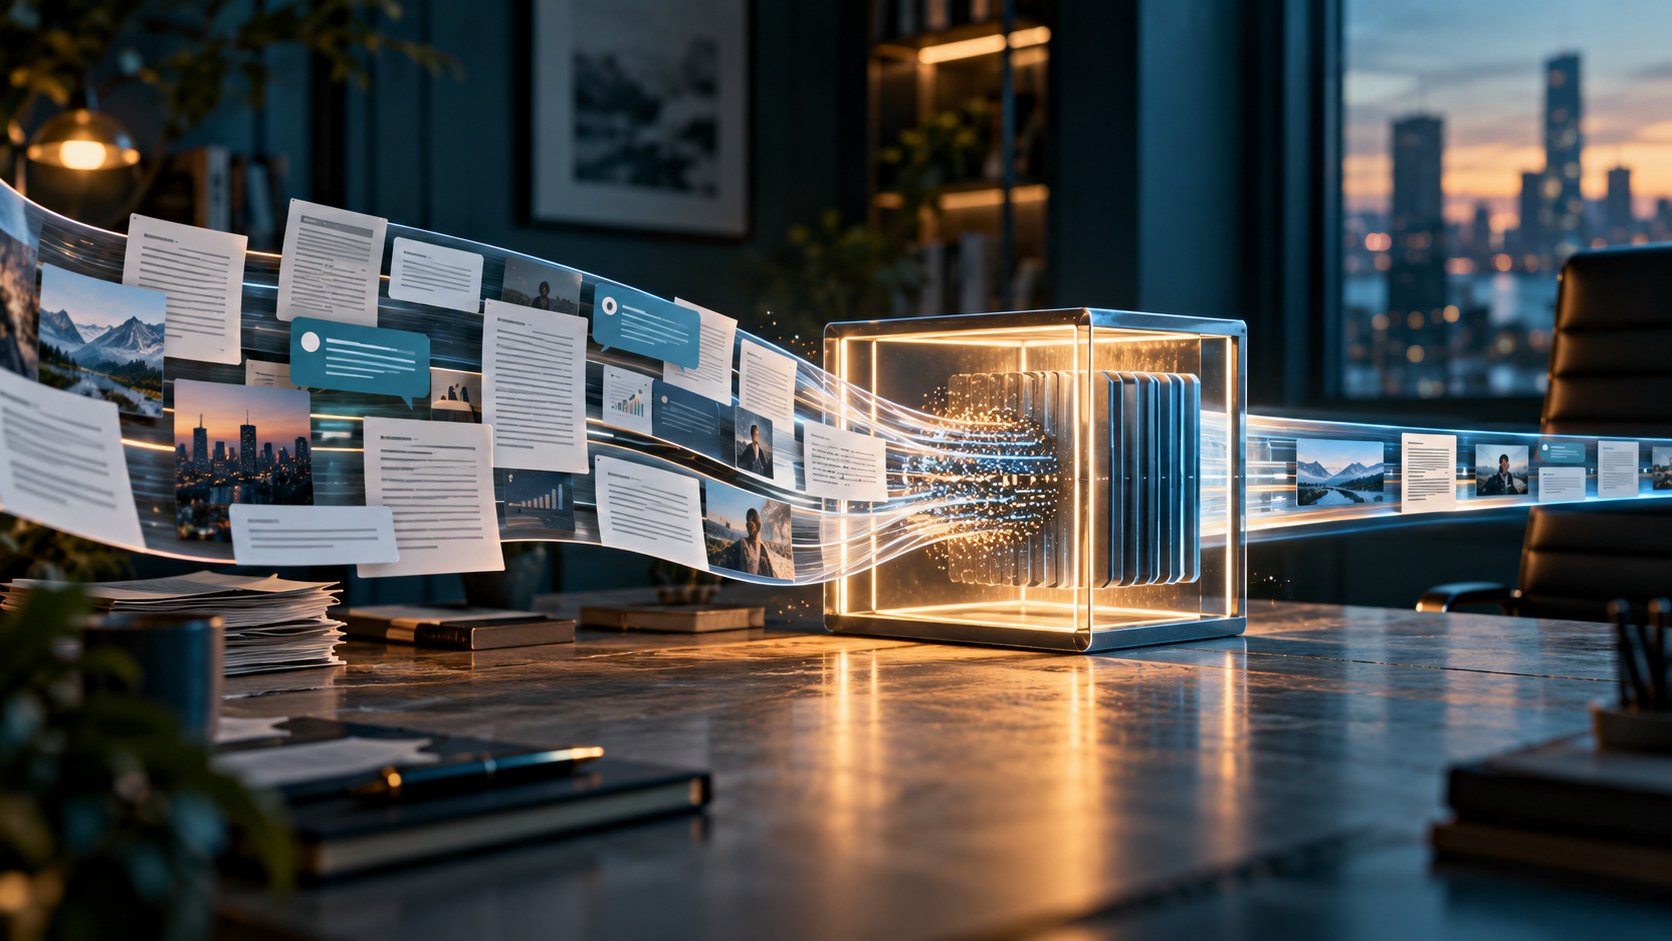
AI Context Windows Explainer
An AI context window is the maximum amount of information a model can work with during one request or conversation turn. It commonly includes system instructions, user messages, tool results, retrieved documents, and the tokens the model generates in reply. When the total approaches the model’s limit, an application must remove, summarize, or reorganize material.
Context windows are measured in tokens rather than pages or words because tokens are the units processed by the model. The same document can use different numbers of tokens with different tokenizers. Images, audio, and other inputs may also consume context through model-specific representations.
A longer context window can let a model compare more documents, retain a longer conversation, or analyze a larger codebase. It is not the same as permanent memory. Context is temporary input for the current computation, while persistent memory requires an application to store information and deliberately bring it back later.
More context does not guarantee better answers. Irrelevant passages can distract the model, important details can be overlooked, and processing very long inputs can raise latency and cost. Good systems select useful evidence, place instructions clearly, test retrieval quality, and verify that the model can actually use information across the length it advertises.
An AI context window is the limited amount of input and generated output a model can consider during one interaction.
Key terms include context window, token, prompt, completion, system message, retrieval, truncation, summarization and persistent memory.
<a href="https://platform.claude.com/docs/en/build-with-claude/context-windows" target="_blank" rel="noopener noreferrer">Anthropic: Context Windows</a> and <a href="https://developers.openai.com/api/docs/guides/prompt-engineering" target="_blank" rel="noopener noreferrer">OpenAI: Prompt Engineering</a> provide the primary references for this explainer.
Instructions, conversation history, tool output, uploaded or retrieved material, and the generated response can all share the same token budget.
Applications may trim old turns, summarize them, or retrieve only relevant passages when the budget is tight.
A model can miss a detail even when it technically fits inside the window. Position, clutter, conflicting evidence, and task difficulty affect performance.
Developers should test realistic document lengths and track both answer quality and cost instead of treating the maximum window size as a memory score.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.