

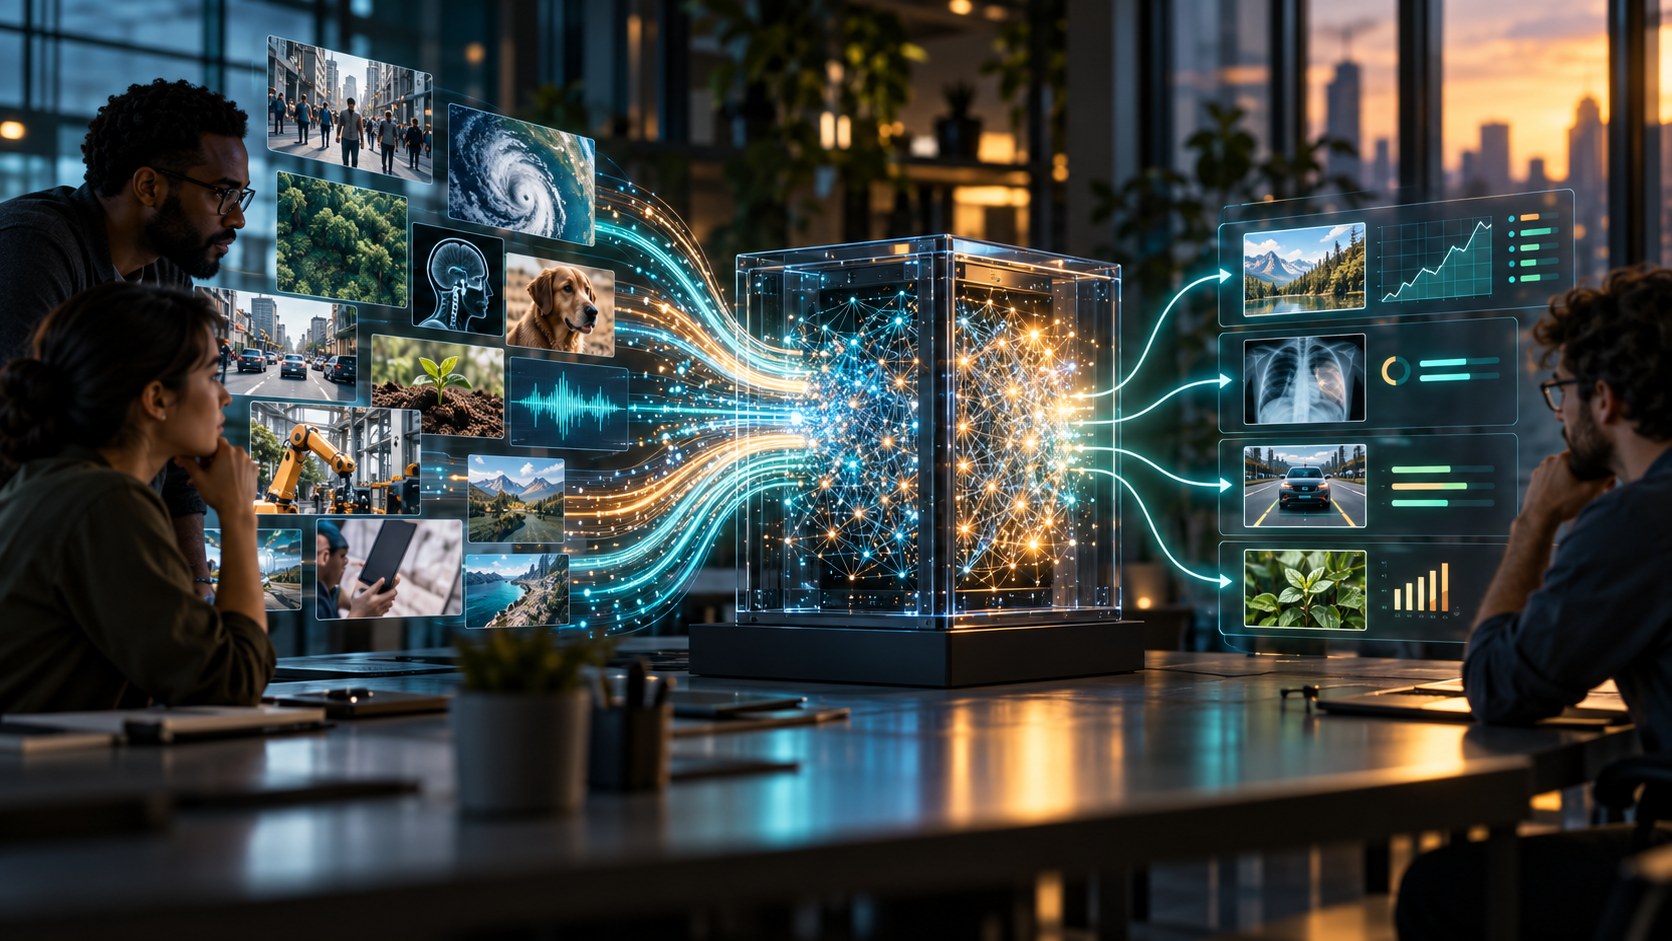
Machine Learning Explainer
Machine learning is a branch of artificial intelligence in which algorithms learn patterns from data and use those patterns to make predictions, classifications, recommendations, or other outputs. Instead of writing a separate rule for every situation, developers define a model, an objective, and a training process that estimates useful parameters from examples.
A typical project begins with data preparation and a choice of features or representation. The model is trained on one portion of the data, tuned with another portion, and evaluated on held-out examples it has not seen. That separation helps reveal whether the model learned a general pattern or merely memorized the training set.
Supervised learning uses labeled examples; unsupervised learning searches for structure in unlabeled data; reinforcement learning improves behavior from rewards and consequences. Neural networks are one family of machine-learning models, alongside methods such as decision trees, linear models, support-vector machines, and clustering algorithms.
Machine learning is useful when patterns are too numerous or subtle to encode by hand, but it is not automatic truth. Results depend on the data, objective, evaluation, and deployment conditions. Biased samples, leakage, shifting real-world behavior, or the wrong success metric can produce a system that looks good in testing but fails the people using it.
Machine learning uses data and algorithms to build models that improve at predictions or decisions without a rule for every case.
Key terms include training data, feature, label, model, parameter, loss, validation, test set, inference and generalization.
<a href="https://developers.google.com/machine-learning/crash-course/" target="_blank" rel="noopener noreferrer">Google Machine Learning Crash Course</a> and <a href="https://csrc.nist.gov/topics/technologies/machine-learning" target="_blank" rel="noopener noreferrer">NIST Machine Learning Resources</a> provide the primary references for this explainer.
Training adjusts model parameters to reduce an objective or loss on examples. Validation guides choices, while a separate test set estimates performance on unseen data.
After training, inference applies the fixed model to new inputs. Monitoring is still needed because real-world data can change after launch.
A model learns statistical relationships present in its data; it does not automatically understand cause and effect or know whether the data are fair and complete.
Responsible use requires representative data, meaningful metrics, human review for consequential cases, security testing, and a plan for drift and errors.
Explore more "Explainers"
Discover additional explainers across politics, science, business, technology, and other fields. Each explainer breaks down a complex idea into clear, everyday language—helping you better understand how major concepts, systems, and debates shape the world around us.